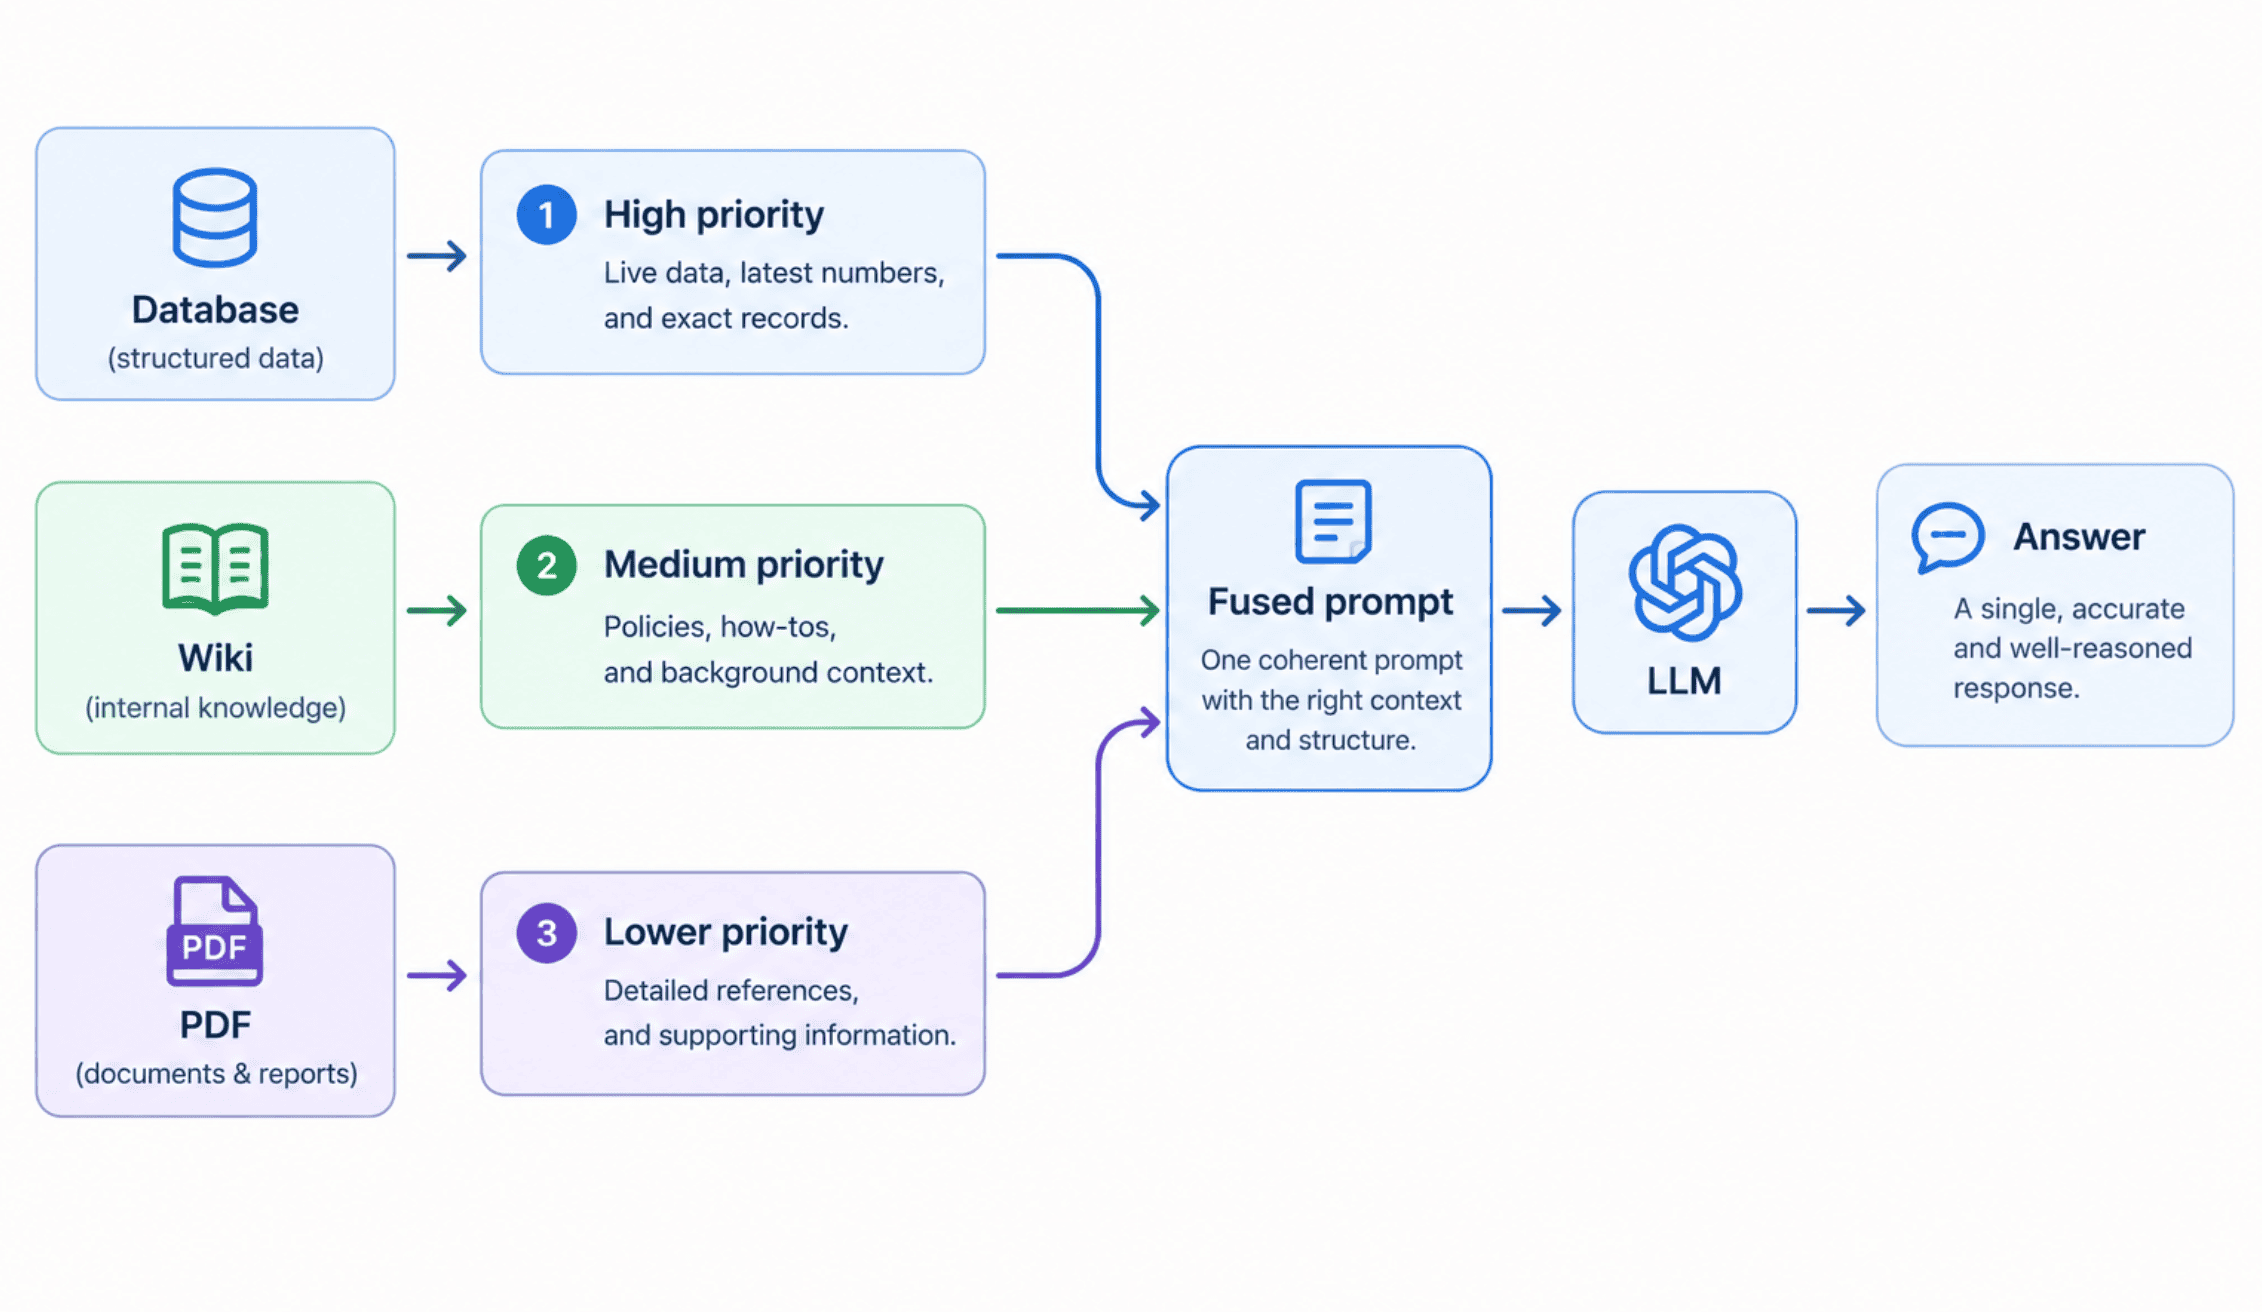
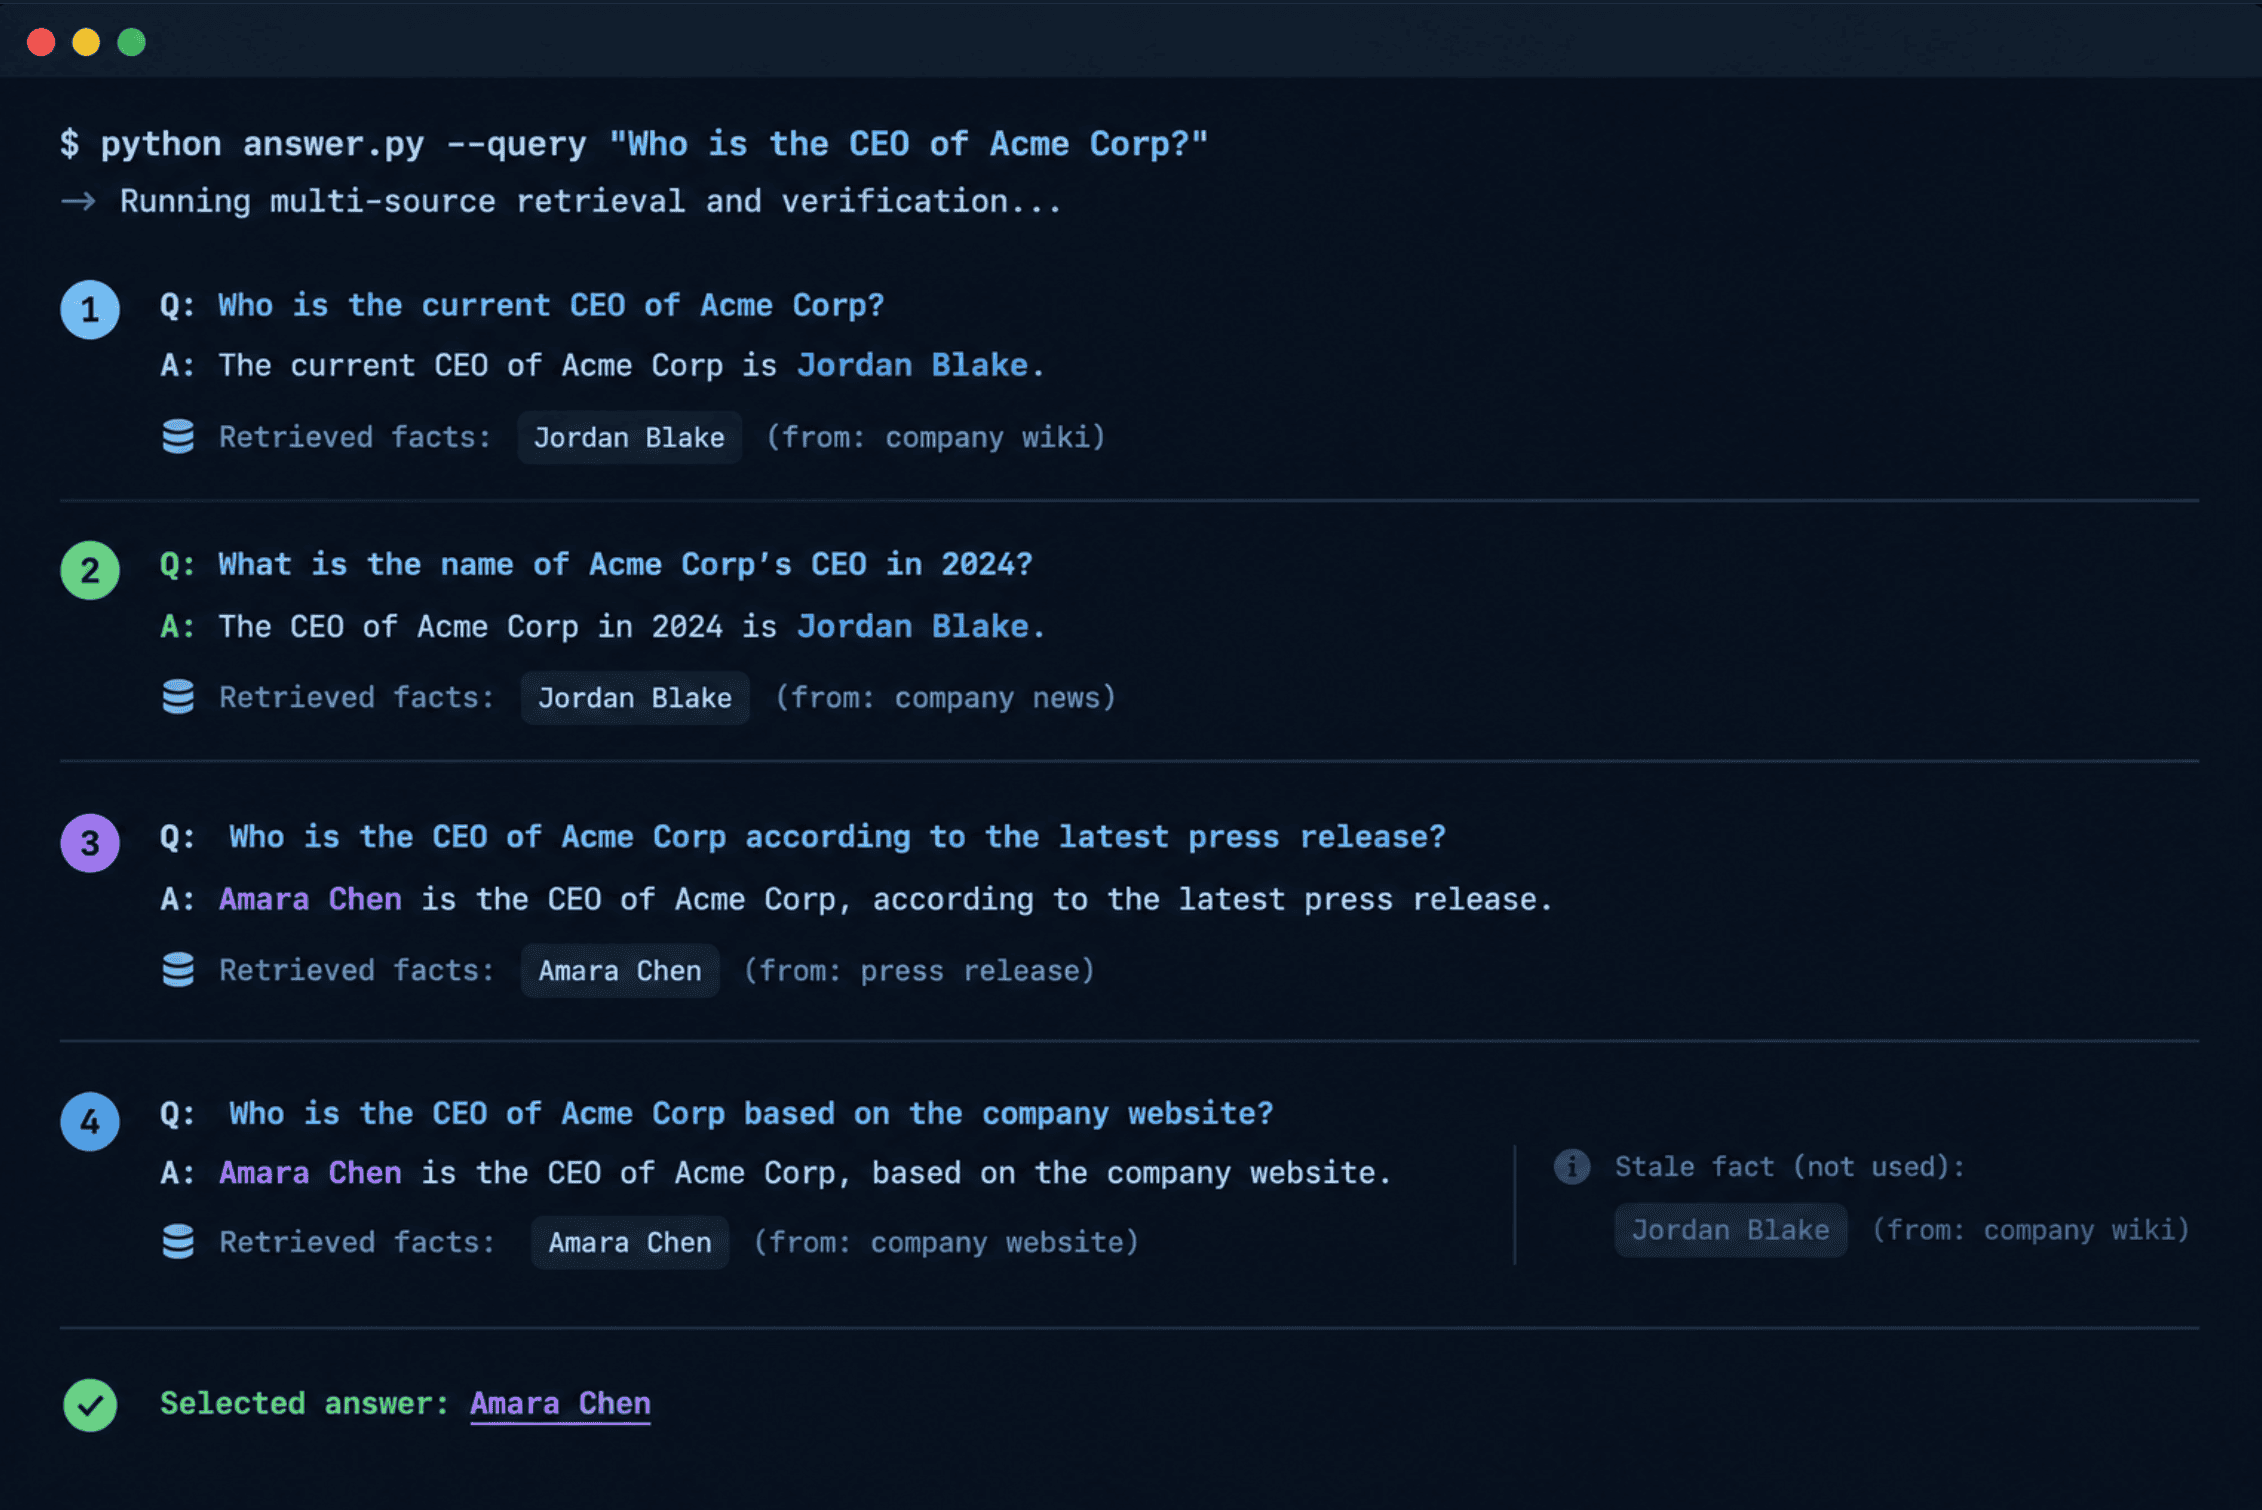
In this article, you will learn how to build a Graph-RAG system that combines a live database, wiki pages, and PDFs into one prioritized knowledge source, so your assistant gives a single, correct answer when those sources disagree.
Topics we will cover include:
How to turn database rows and wiki runbooks into prioritized facts in a simple quad store.
How to extract, chunk, and embed PDF text with pdfplumber and Chroma as a vector fallback.
How to fuse all three tiers into one prompt with explicit priority rules that resolve conflicts.
An engineer pings your internal AI assistant at 11 p.m. and asks who’s on-call for the payments service. The assistant has read the wiki, indexed every PDF in the shared drive, and has a live connection to the service registry. It should be a trivial question. But the wiki was last edited four months ago, the on-call rotation has changed twice since then, and the database has the current answer sitting in a single row.…