A practical walkthrough of LoRA fine-tuning a small language model on 8-24 GB of VRAM, with code snippets, a checklist and fixes for the usual failures.
Austin-based novelist Karen Olsson’s background as a journalist (as writer-at-large for Texas Monthly and an editor of the late Texas Observer) has enriched her fiction since the beginning of her c…
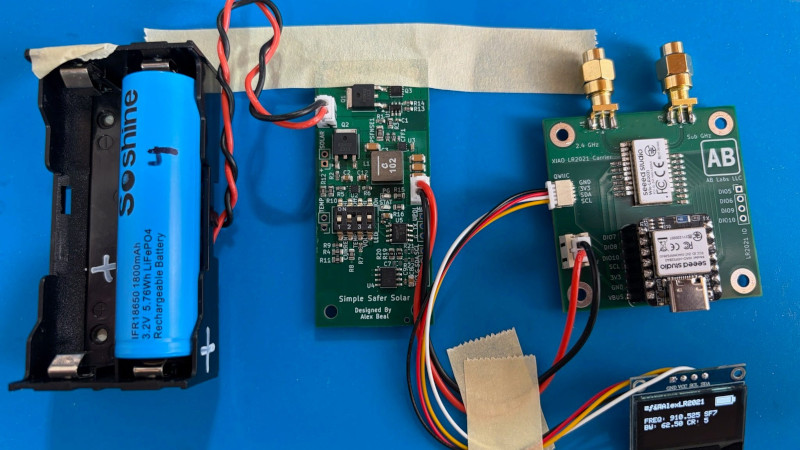
If you’ve ever done anything with LoRa, the chances are you’ve used a LoRa chip or module as a peripheral for a microcontroller, and left it at that. But that’s not always the cas…
Most ESP32 boards I buy end up doing one thing forever. I got tired of that, so I built KoaOS for the Heltec WiFi LoRa 32 V4 (ESP32-S3): a small Unix-style OS that turns the board into something you can repurpose without reflashing.…
Fine-tune a Sentence Transformers embedding model with a LoRA adapter: training data, working code, the settings that matter, and the re-embedding step.
We've been working on an experimental wireless video transmission system using LoRa modulation, and we wanted to see how far we could push it beyond the usual low-bandwidth sensor data.…
Seeed Studio has posted MeshCore on GitHub, a lightweight C++ library that handles multi-hop packet routing for embedded projects using LoRa and other packet radios.…
Foundation models are reshaping computational biology. Pretrained on massive corpora of protein or genomic sequences, models such as ESM2 (a protein language…
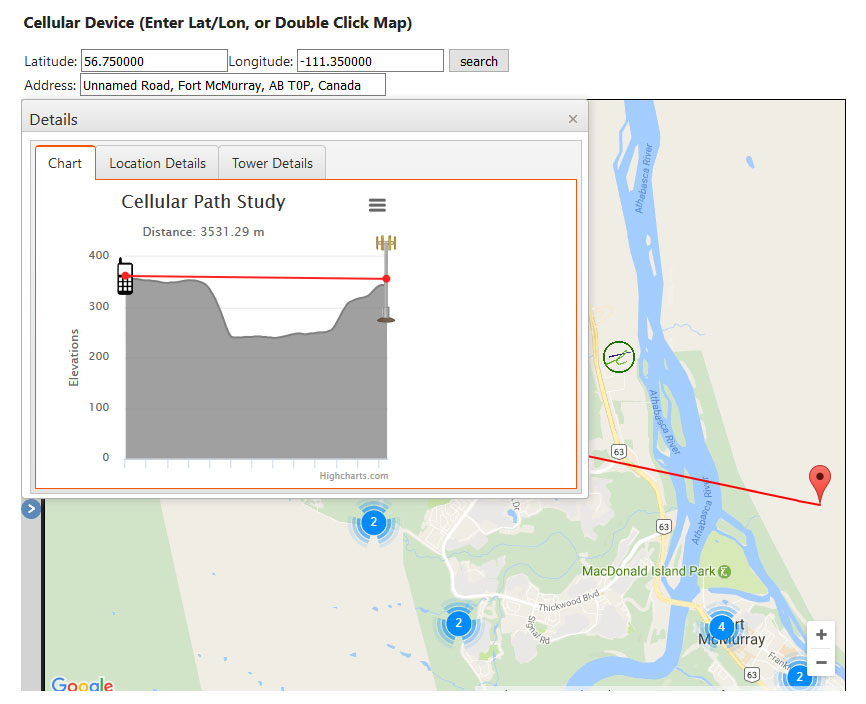
RF Line-of-Sight The RF Line-of-Sight tool allows users to easily drag-and-drop locations and obtain point-to-point line-of-sight information anywhere using Google Maps.…