#Ollama
183 posts
Feed·
20 of 183 posts

📰
15s

📰
How to Run GPT-OSS 20B and Llama 3.1 70B From Your Android Phone in 2026 (On Your Own Computer)
15s

📰

📰
5 Mistakes I Made Swapping a Hosted LLM for Local Ollama in .NET
15s

📰
Ollama in Your Dev Loop: Swapping the Base URL Is the Easy Part
15s

🖼️
Running an AI Agent on a Local LLM: What I Measured on One GPU
View the full article
Create a free account to read full articles inline — no redirect to the original site.
🖼️
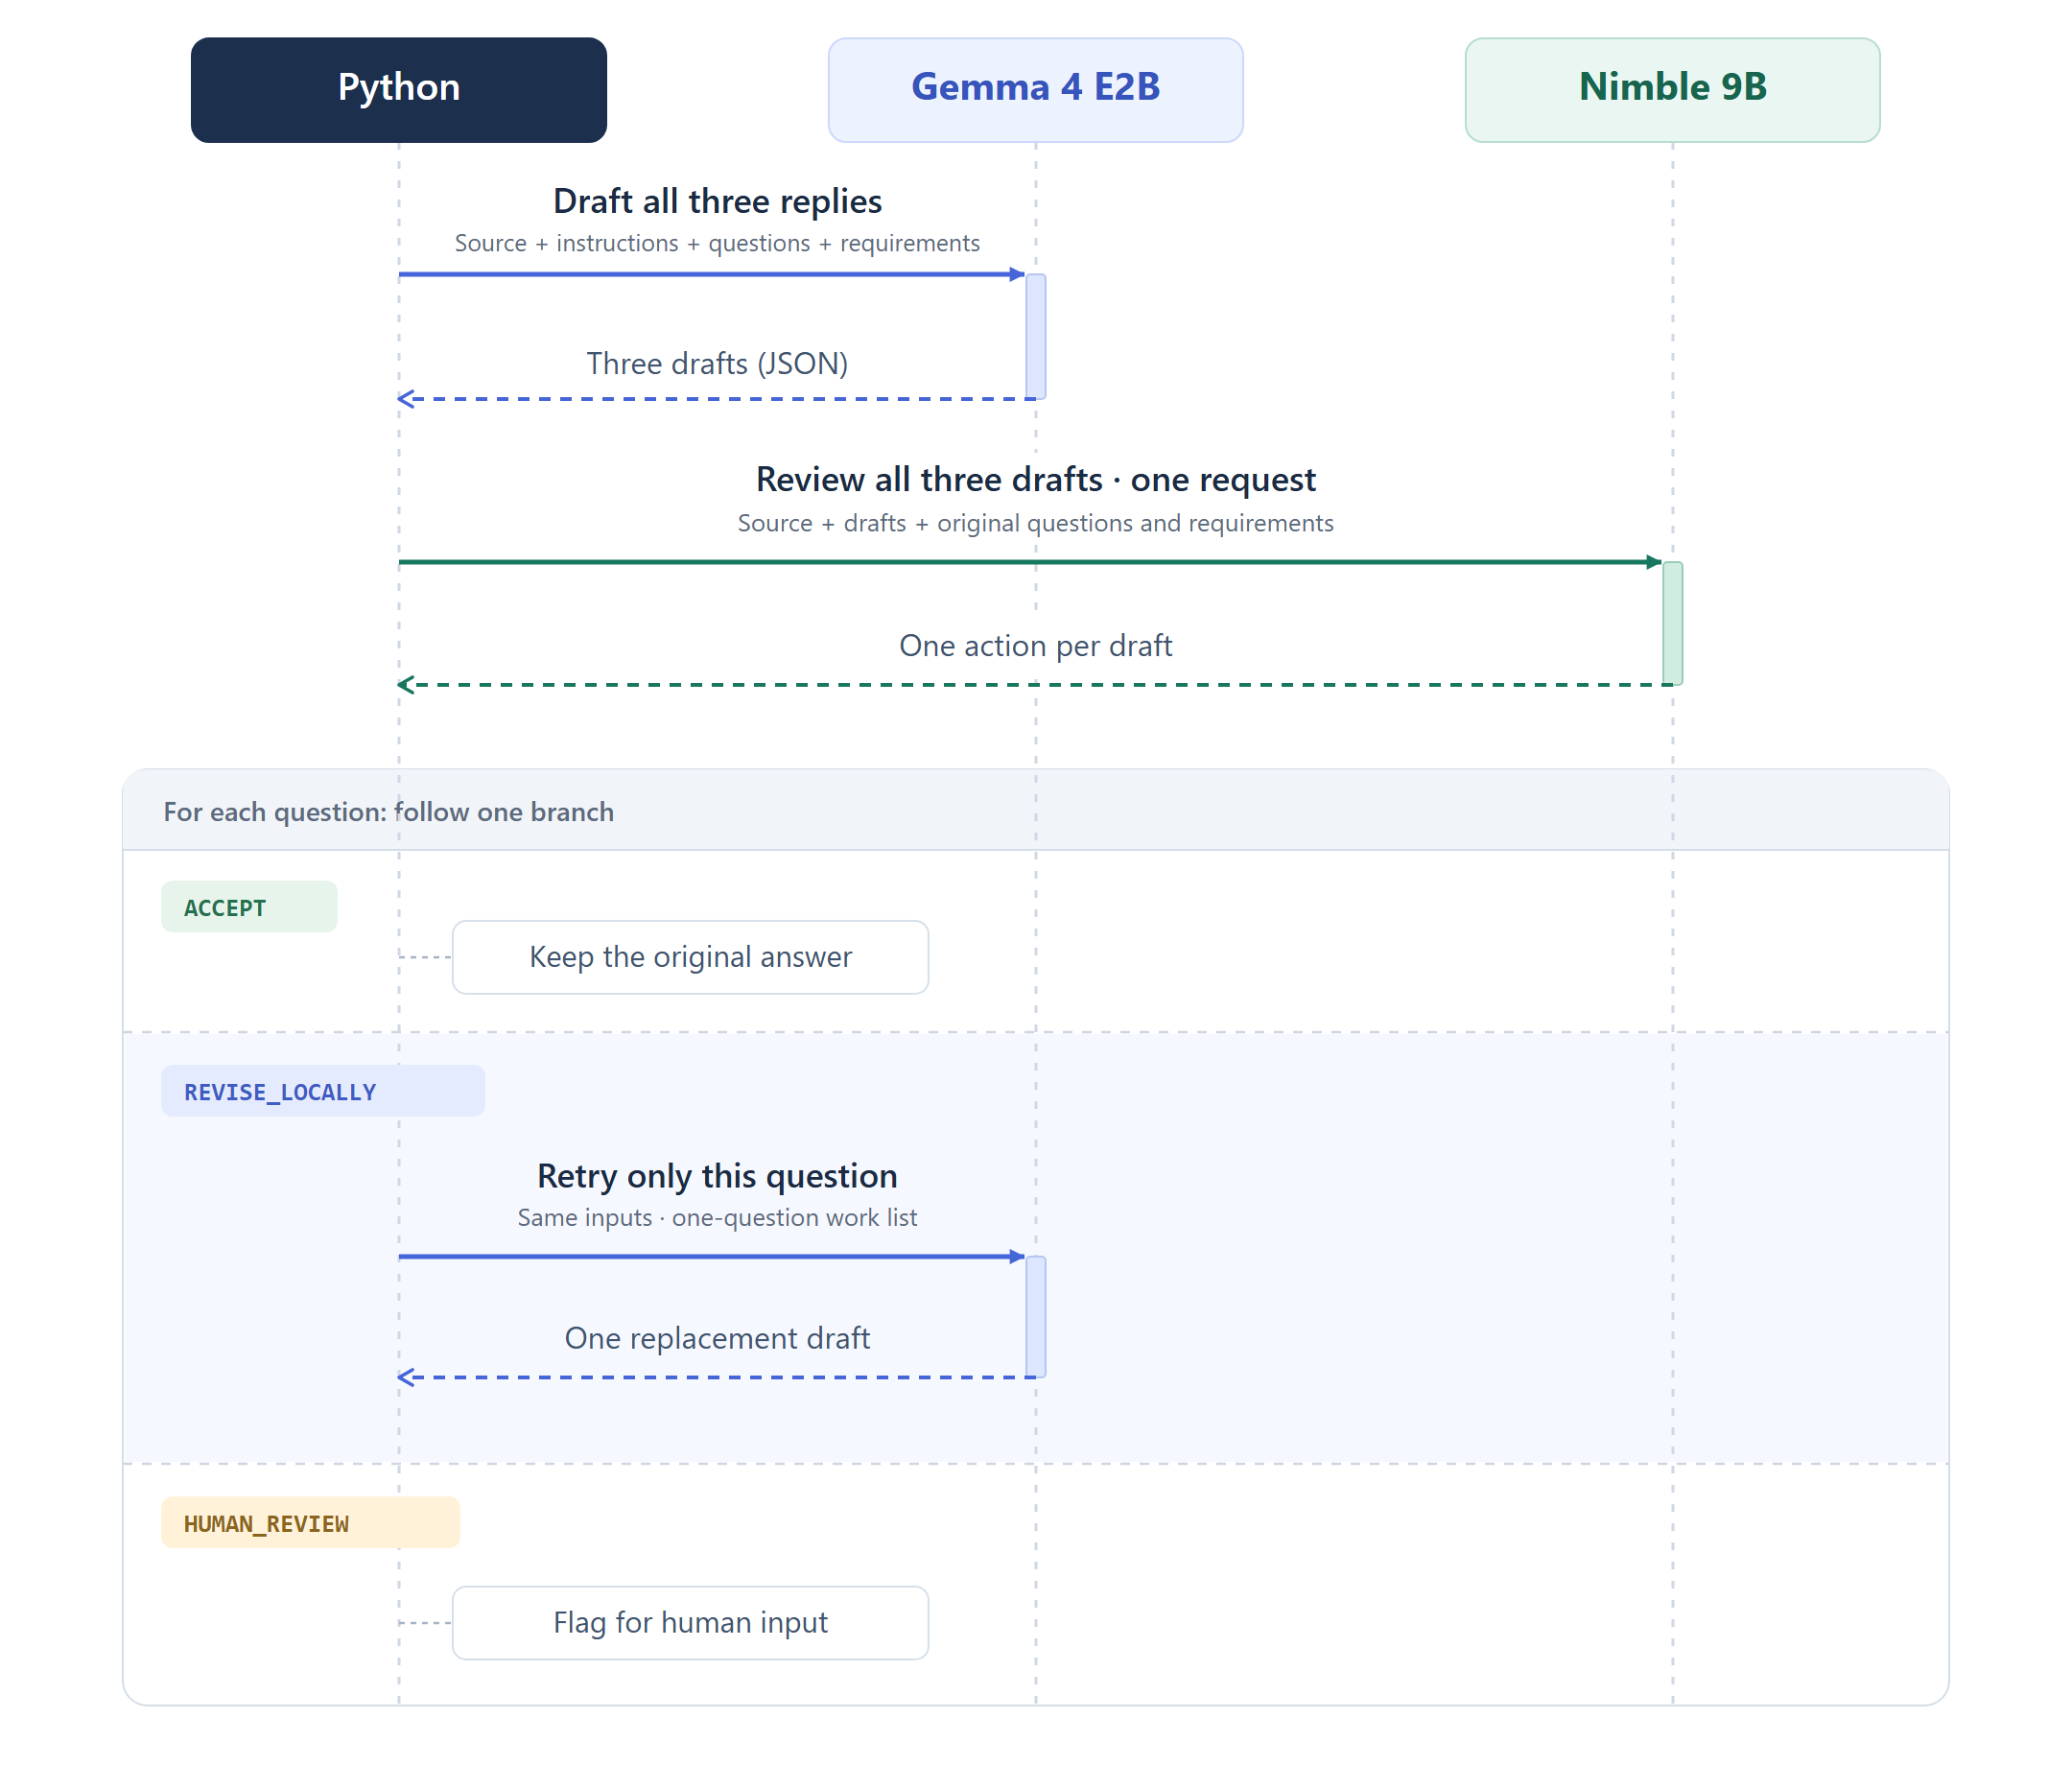
Before Your Local LLM's Answer Goes Downstream, Let Nimble 9B Review It
15s

🖼️
I Built J.A.R.V.I.S. — A Local AI Assistant
15s

📰
Serverless Cold Start Optimization: 60 Percent Faster
15s
🖼️
View the full article
Create a free account to read full articles inline — no redirect to the original site.

📰
Benchmarking Scikit-Ollama vs. Groq-Backed Scikit-LLM: Speed, Cost, and Accuracy - MachineLearningMastery.com
15s

🖼️
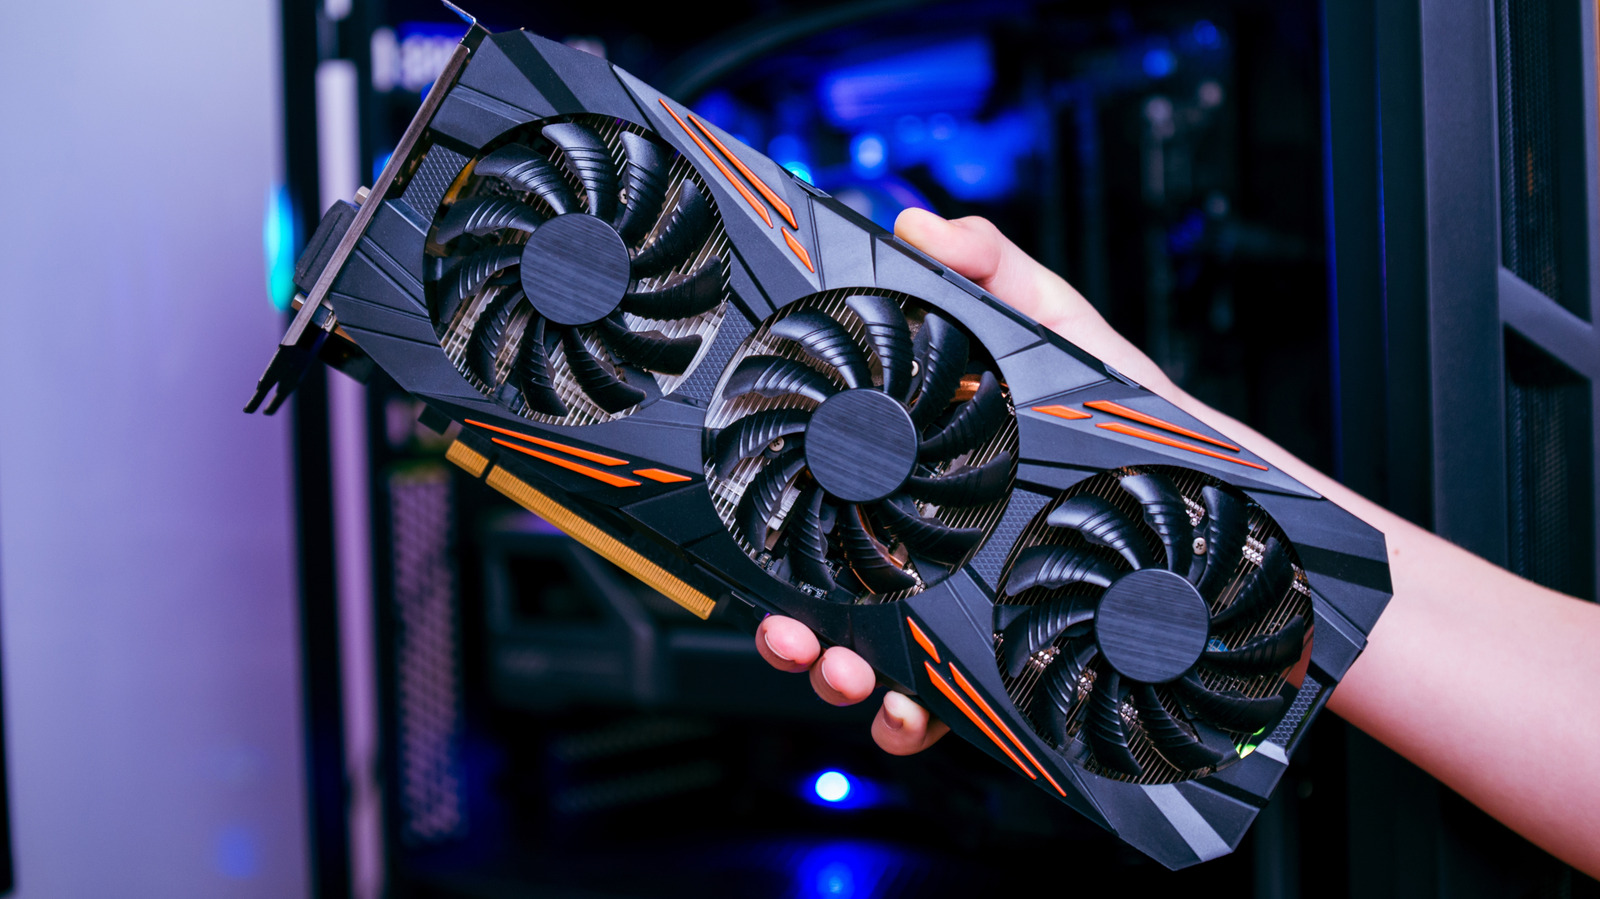
What Hardware Does Your PC Need To Run A Local AI Model?
15s

📰
PrivaSearch: private AI search with SearXNG and a local LLM
15s

📰
Run DeepSeek R1 Locally with Ollama (2026): VRAM Formula & Hardware Sizing Matrix (1.5B to 671B)
15s

🖼️
Ollama was holding back my "weak" Intel GPU, and one swap turned it into a solid local AI setup
View the full article
Create a free account to read full articles inline — no redirect to the original site.
📰

📰

📰

📰
Ollama Docker Setup: GPU, Volumes and Compose
15s

🖼️
Top 5 Local AI Models and How to Get Them
15s