#Llama
131 posts
Feed·
20 of 131 posts

📰
15s

🖼️
Developer's llama.cpp Fork Makes Prompt Lookup Drafting Up to 42x Faster
15s

📰
Kindi – fast local inference on low-cost GPUs, and the exact-match rule that makes its numbers trustworthy
15s

📰
Show HN: 53ON AI Server – OpenAI-compatible server for AMD Ryzen AI Max
15s

📰
Compress Gemma 4 by 3x with 2x Speedup: Complete Air-26B-A4B Multimodal Deployment Guide on Consumer GPUs
15s

📰

🖼️
DeFiLlama digital asset pools
15s
🖼️

🖼️
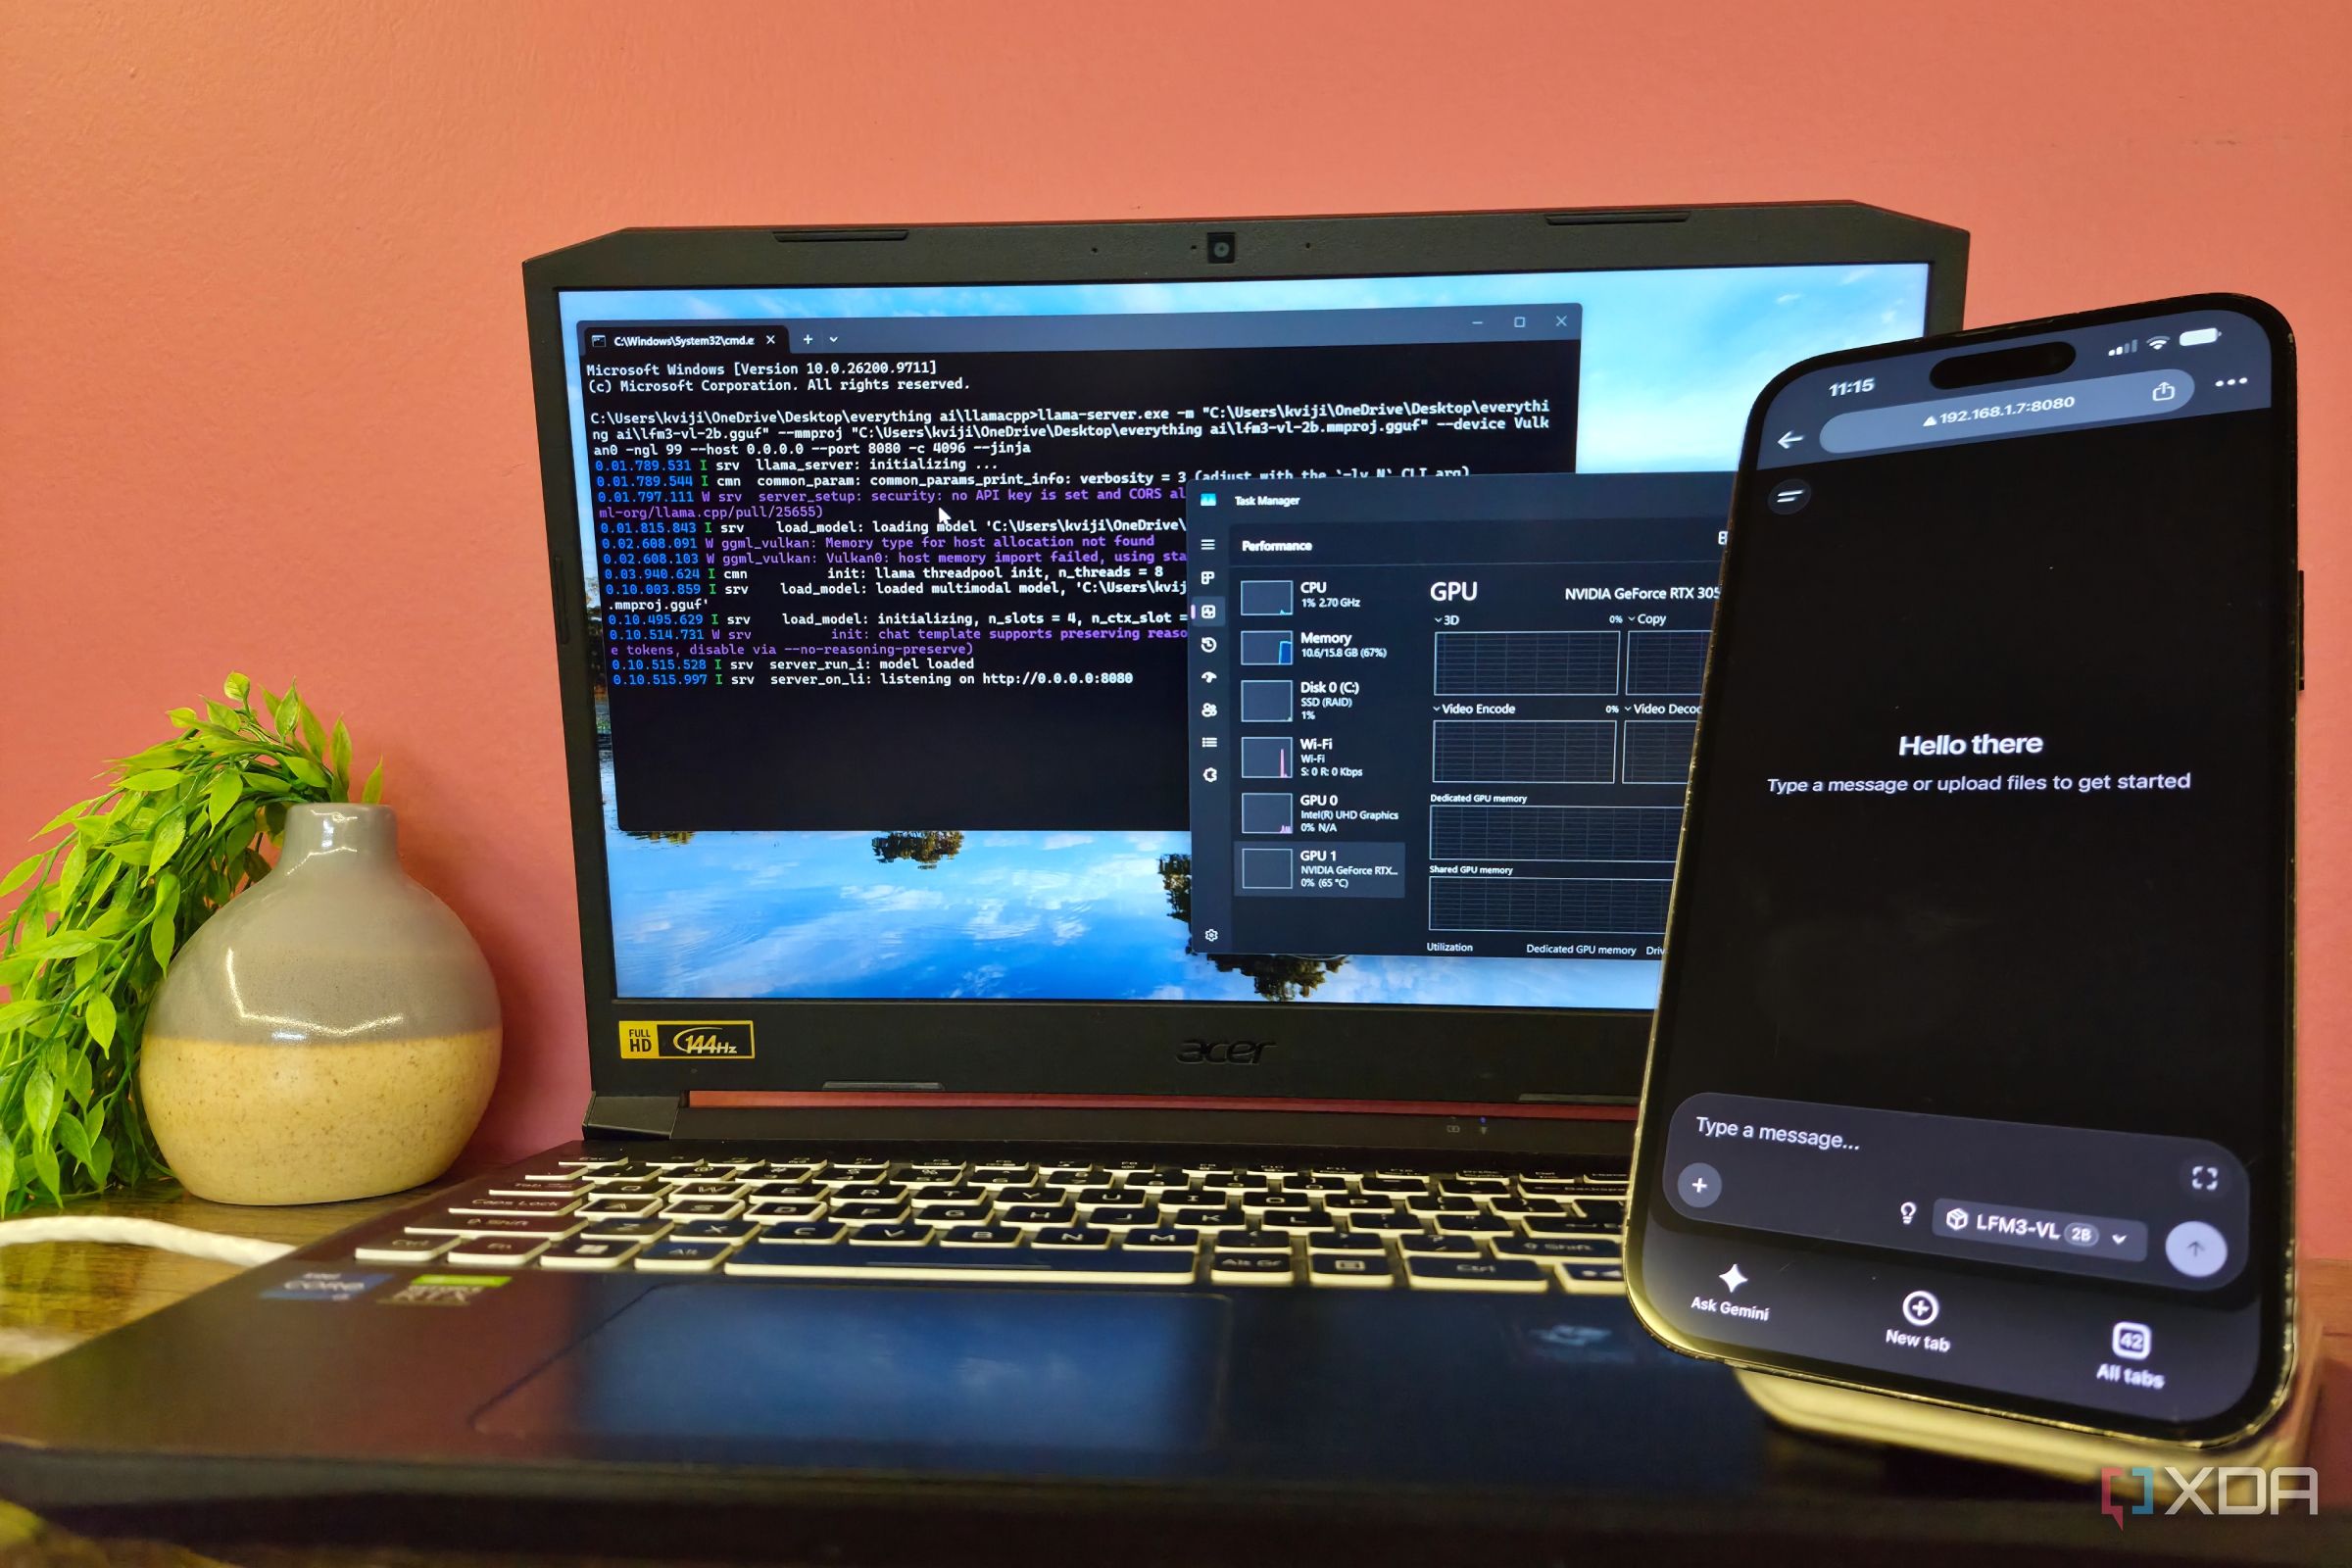
I run a small local model on my laptop's integrated graphics, so my dedicated GPU stays free for other work
View the full article
Create a free account to read full articles inline — no redirect to the original site.

📰
Ten engines for one box: which local inference engine fits a 100 GB rig with two 16 GB cards?
15s

📰

🖼️
Ollama was holding back my "weak" Intel GPU, and one swap turned it into a solid local AI setup
View the full article
Create a free account to read full articles inline — no redirect to the original site.

📰
Serving Sage-A1.5 on an RTX 4090: one broken flag, one queue, and a self-check mode to measure
15s

📰

🖼️
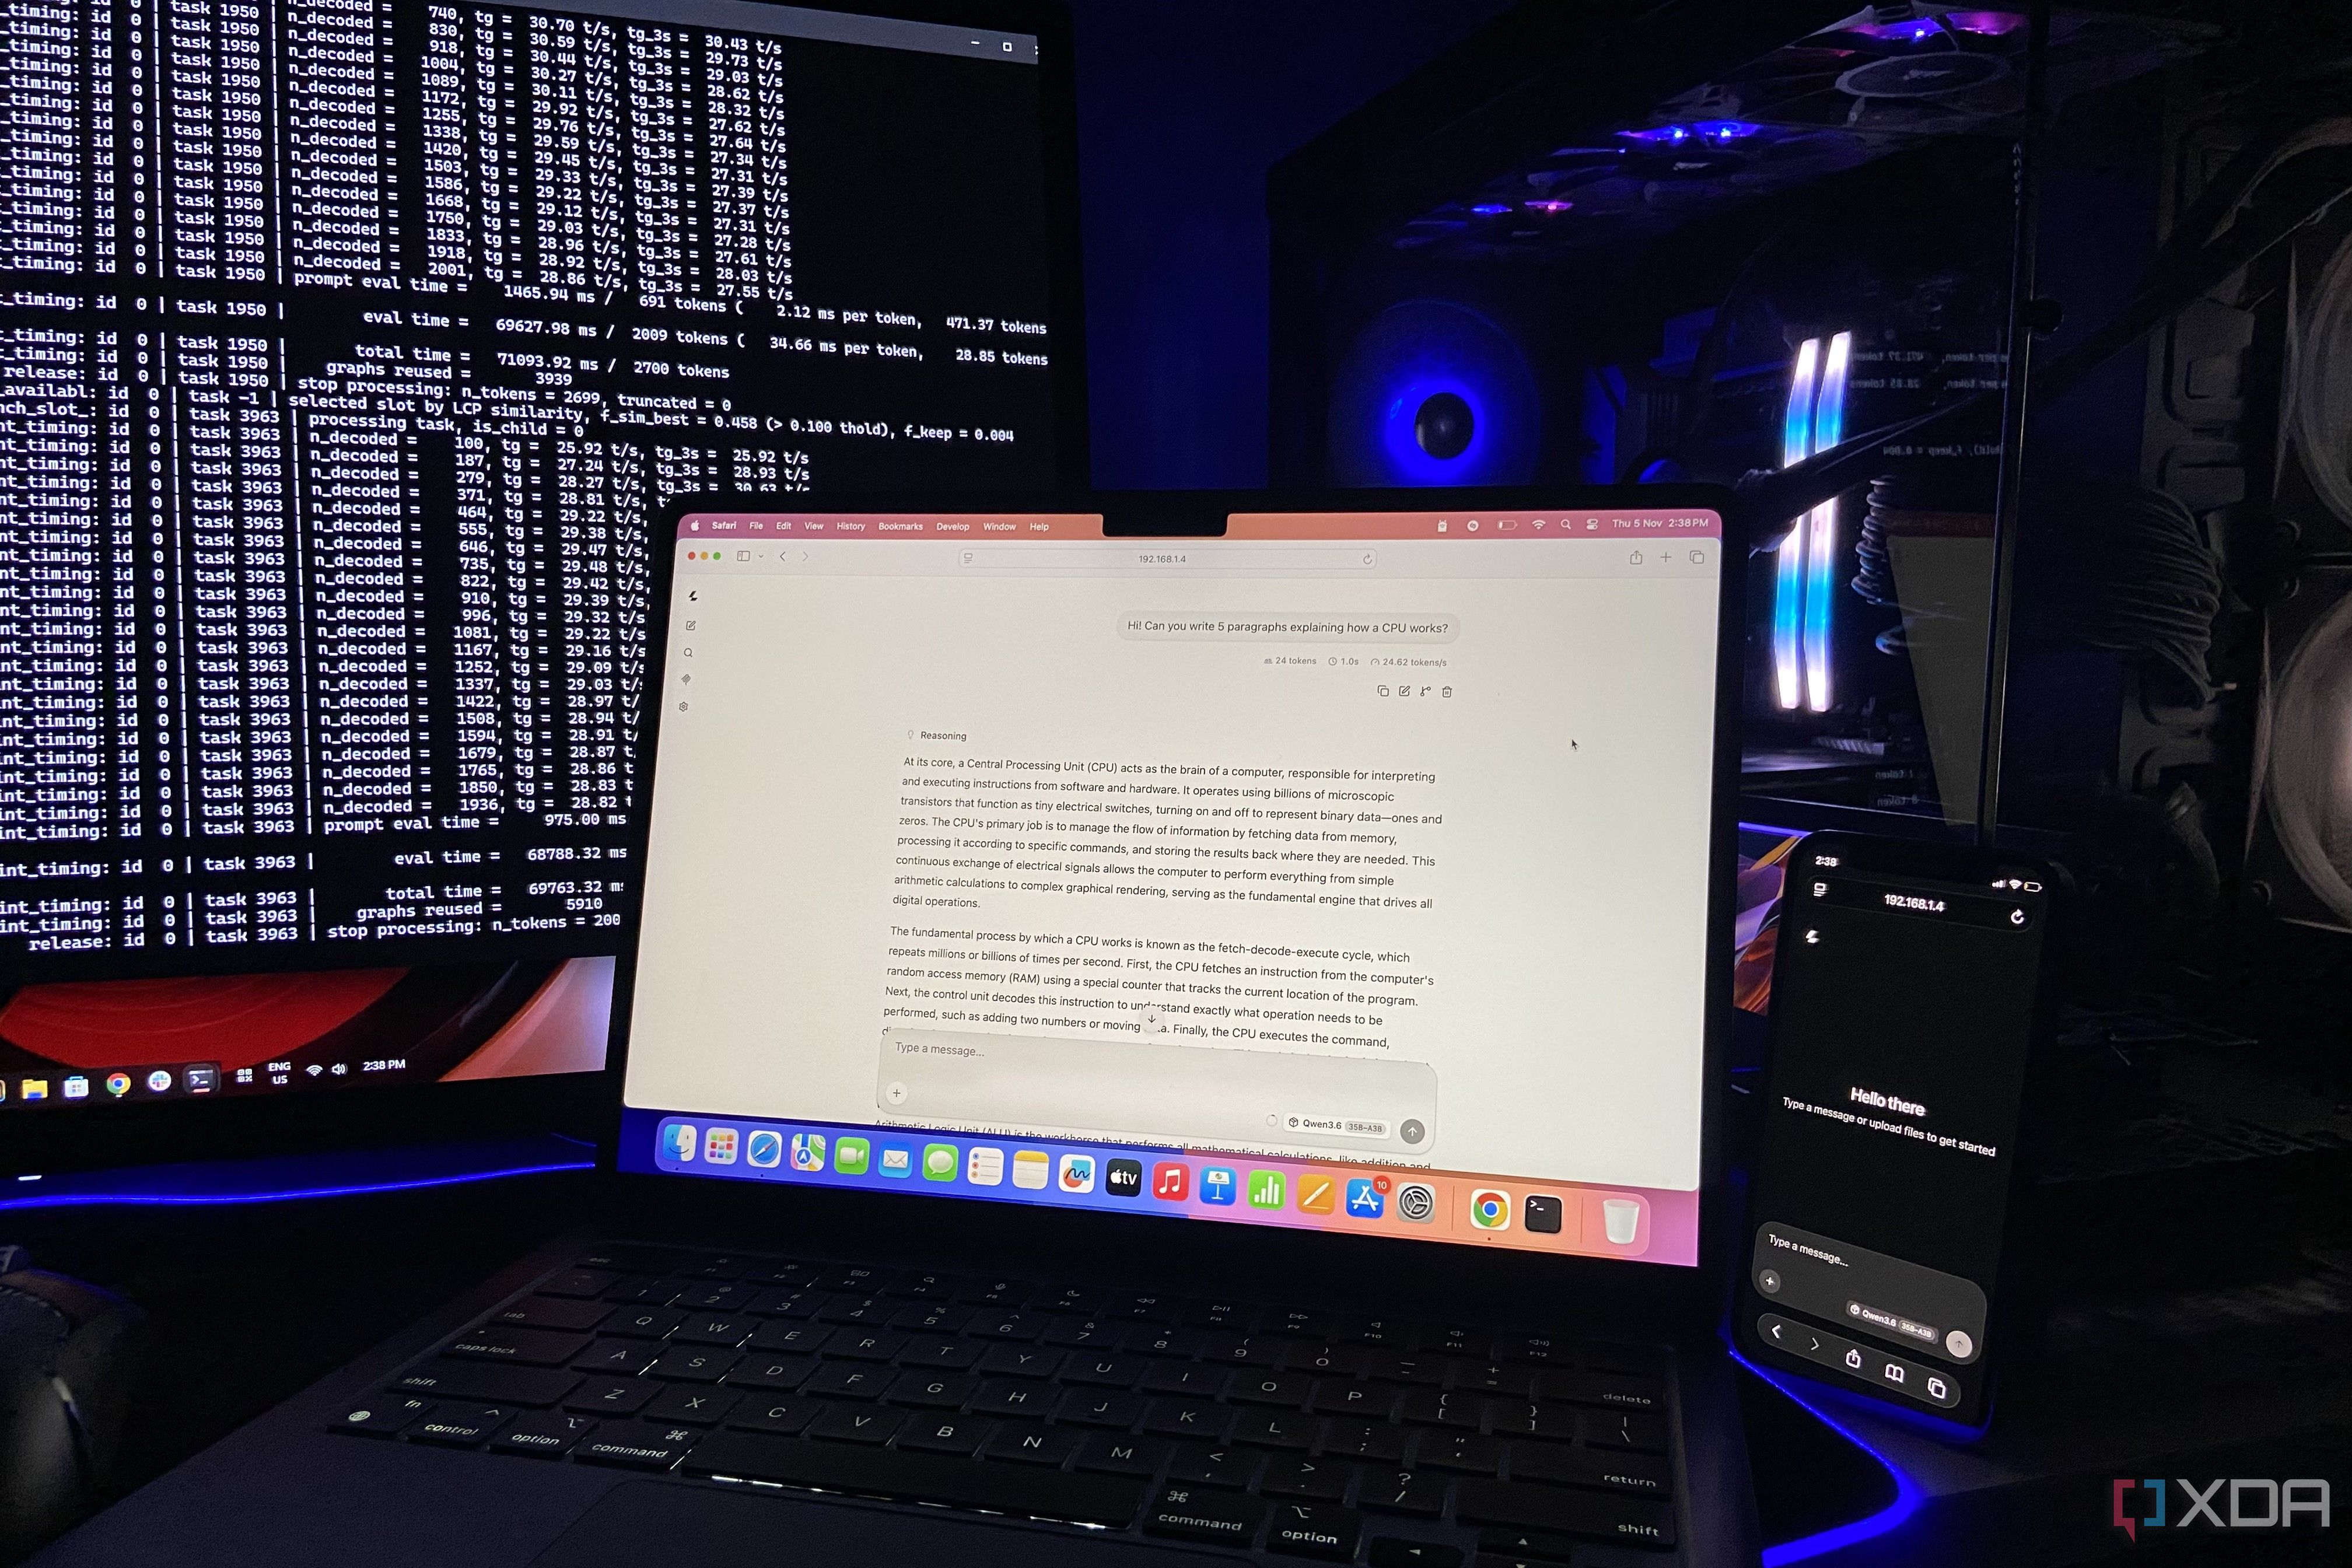
My gaming GPU sat idle most of the day, so I turned it into a local AI server the whole house can use
15s

📰

🖼️
Making Local LLMs Usable on 8GB GPUs
15s

📰

📰
How much VRAM do popular LLMs really need at 4-bit and 8K context? Data from 26 models
15s