Menu

#Gguf

17 posts

Feed·
14 of 17 posts
Compress Gemma 4 by 3x with 2x Speedup: Complete Air-26B-A4B Multimodal Deployment Guide on Consumer GPUs
📰
0Read More

Compress Gemma 4 by 3x with 2x Speedup: Complete Air-26B-A4B Multimodal Deployment Guide on Consumer GPUs

DEV Community: deeplearning·Rich Ng·1 day ago
#nTHhwufM
#devtodeeplearning#education#devto#dev#llama

1. The Multimodal Efficiency Paradox: Why Massive Models Fail in Production The artificial...

15s
Which Open LLMs Are Downloaded Now? A Daily Leaderboard of 30-Day Downloads by Country
📰
0Read More

Which Open LLMs Are Downloaded Now? A Daily Leaderboard of 30-Day Downloads by Country

DEV Community: machinelearning·AI OpenFree·3 days ago
#AgPsHXws

A daily Hugging Face leaderboard of trailing 30-day downloads: global top 300 and Korea top 30. China-trained families hold 61.7% of top-300 downloads, the US 32.3%. Korea's top two models are VIDRAFT's POCKET series.

15s
How to Run Tencent WeVisOne-VL-4B Locally on 8 GB VRAM (Ollama Drops the Masks)
🖼️
0Read More

How to Run Tencent WeVisOne-VL-4B Locally on 8 GB VRAM (Ollama Drops the Masks)

DEV Community: computervision·Alan West·18 days ago
#5VEEyyUN

It refuses to box objects that aren't there 96.4% of the time vs 18.3% for Qwen3-VL-8B. Q4_K_M plus projector is ~3.2 GB; Ollama and llama.cpp commands inside.

15s
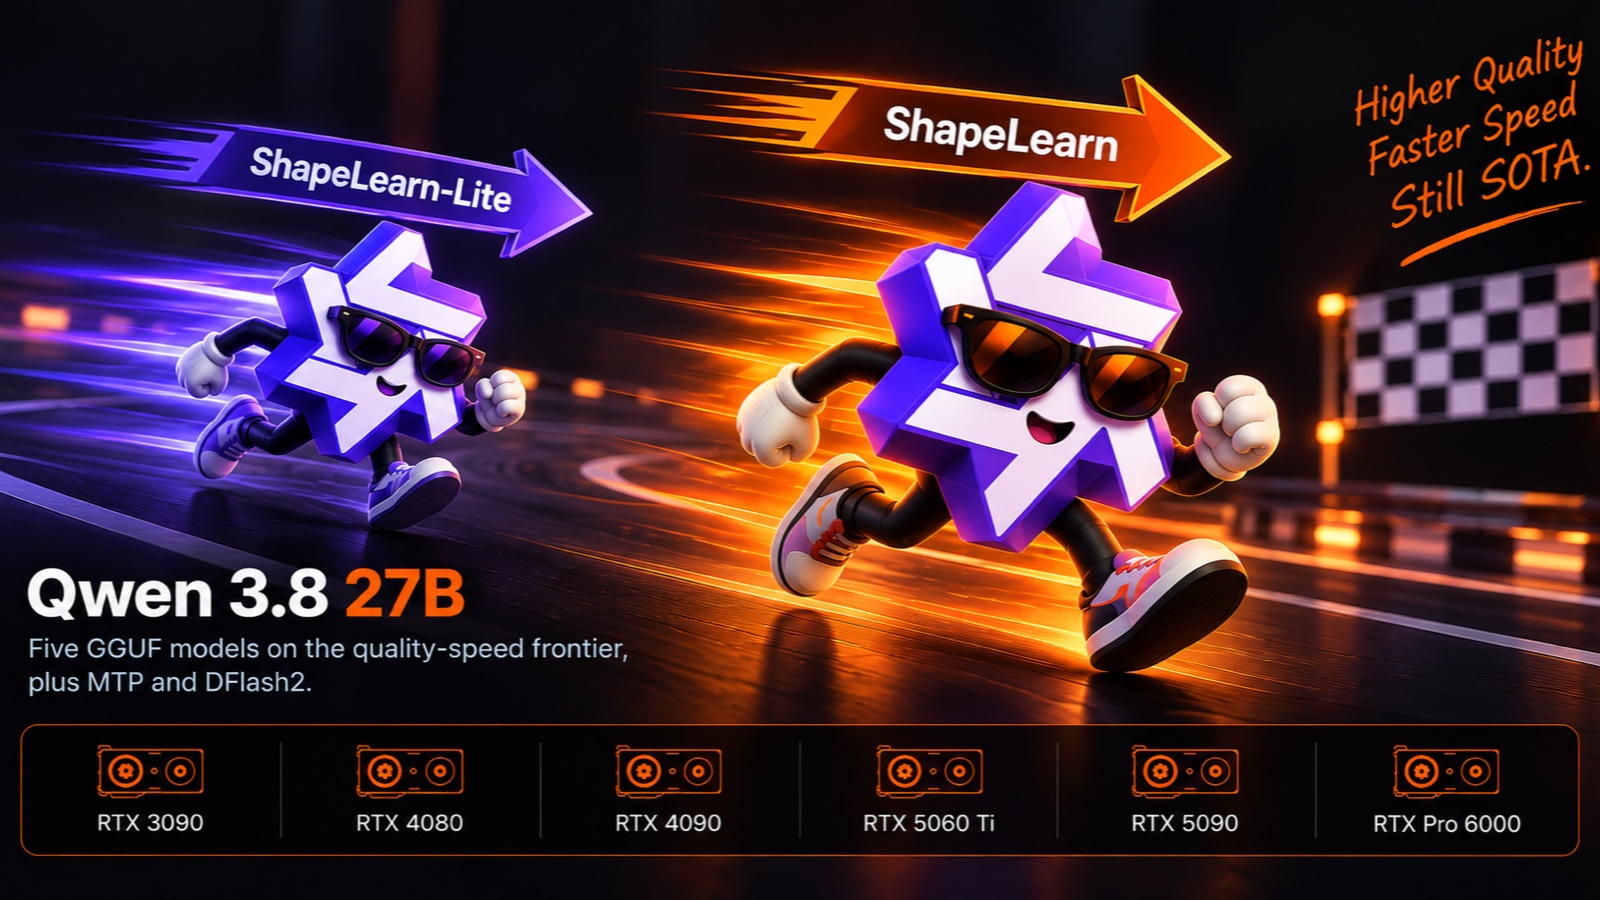
ShapeLearn-Lite Held Up. ShapeLearn Did Better: Qwen 3.8 27B
🖼️
0Read More

ShapeLearn-Lite Held Up. ShapeLearn Did Better: Qwen 3.8 27B

Hacker News·about 2 months ago
#hfIHskmF

ByteShape's full ShapeLearn release of Qwen 3.8 27B: five GGUF models on the measured quality-speed frontier across six GPUs, plus MTP and DFlash2 speculative decoding.

15s
How to Setup a Local Coding Agent on macOS
🖼️
475Read More

How to Setup a Local Coding Agent on macOS

Hacker News·5 months ago
#dEOSDGqk
#ikyle#gguf#gemma#llama#models

Running Gemma 4 26B-A4B and Qwen3.6 35B-A3B locally with llama.cpp, MTP speculative decoding, multimodal support, and PI as a coding agent.

15s
GGUF Quantization Explained: Q4_K_M vs Q5_K_M vs Q8 — Which to Pick (2026)
🖼️
0Read More

GGUF Quantization Explained: Q4_K_M vs Q5_K_M vs Q8 — Which to Pick (2026)

DEV Community·Patrick Hughes·6 months ago
#fqnJEpdi
#gguf#llamacpp#quantization#model#q4_k_m

Q4_K_M cuts model size 75% with minimal quality loss — but when should you use Q5, Q6, or Q8 instead? We benchmarked every quant level on real hardware and measured the actual accuracy tradeoffs.

15s
Meet Tian AI: Your Completely Offline AI Assistant for Android
🖼️
0Read More

Meet Tian AI: Your Completely Offline AI Assistant for Android

DEV Community·Jeffrey.Feillp·7 months ago
#jx3alb4D
#android#ai#opensource#software#tian

Meet Tian AI — the open-source, completely offline AI assistant for Android that runs entirely on your phone via Termux. No cloud, no data leaks, no subscriptions.

15s
How to Deploy Llama 3.2 7B with GGUF Quantization on a $5/Month DigitalOcean Droplet: Sub-1GB Memory Inference
📰
0Read More

How to Deploy Llama 3.2 7B with GGUF Quantization on a $5/Month DigitalOcean Droplet: Sub-1GB Memory Inference

DEV Community·RamosAI·7 months ago
#zd3DHbX5
#programming#tutorial#ai#llama#ollama

From Dev.to - tutorial: How to Deploy Llama 3.2 7B with GGUF Quantization on a $5/Month DigitalOcean Droplet: Sub-1GB Memory Inference

15s
Meet Tian AI: Your Completely Offline AI Assistant for Android
📰
0Read More

Meet Tian AI: Your Completely Offline AI Assistant for Android

DEV Community·Jeffrey.Feillp·7 months ago
#ONRMfXNb
#android#ai#opensource#software#tian

Meet Tian AI — the open-source, completely offline AI assistant for Android that runs entirely on your phone via Termux. No cloud, no data leaks, no subscriptions.

15s