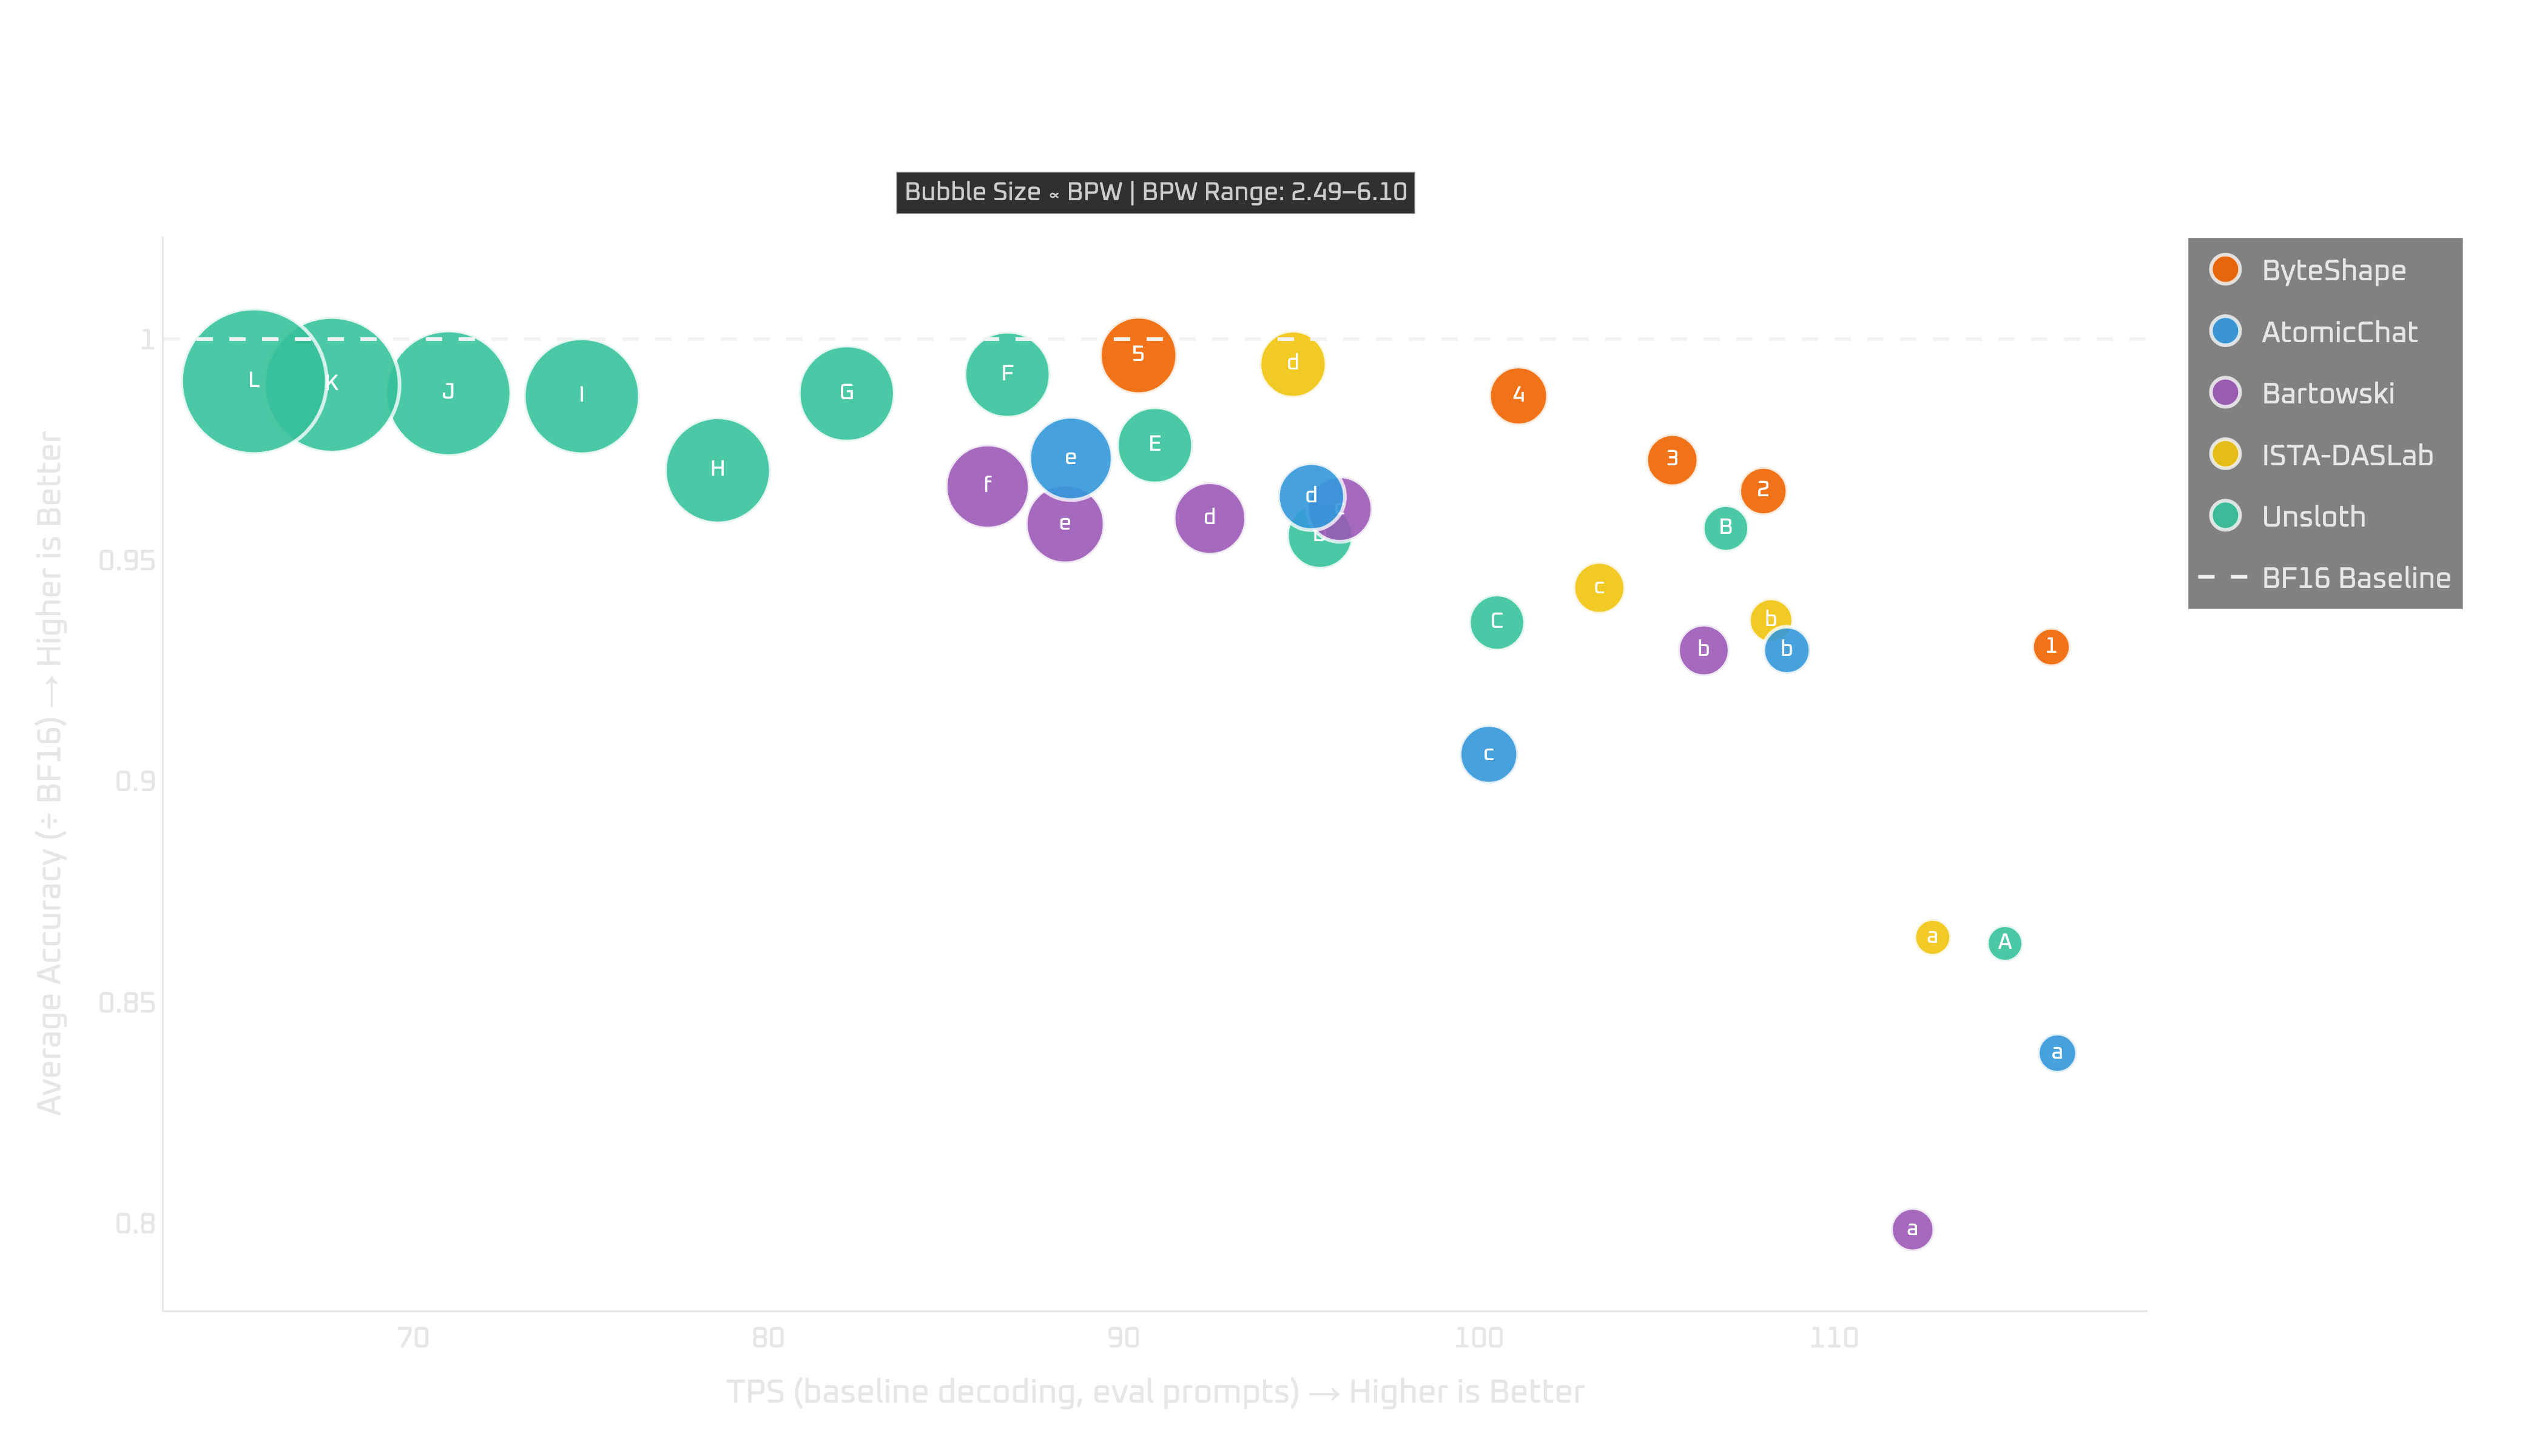
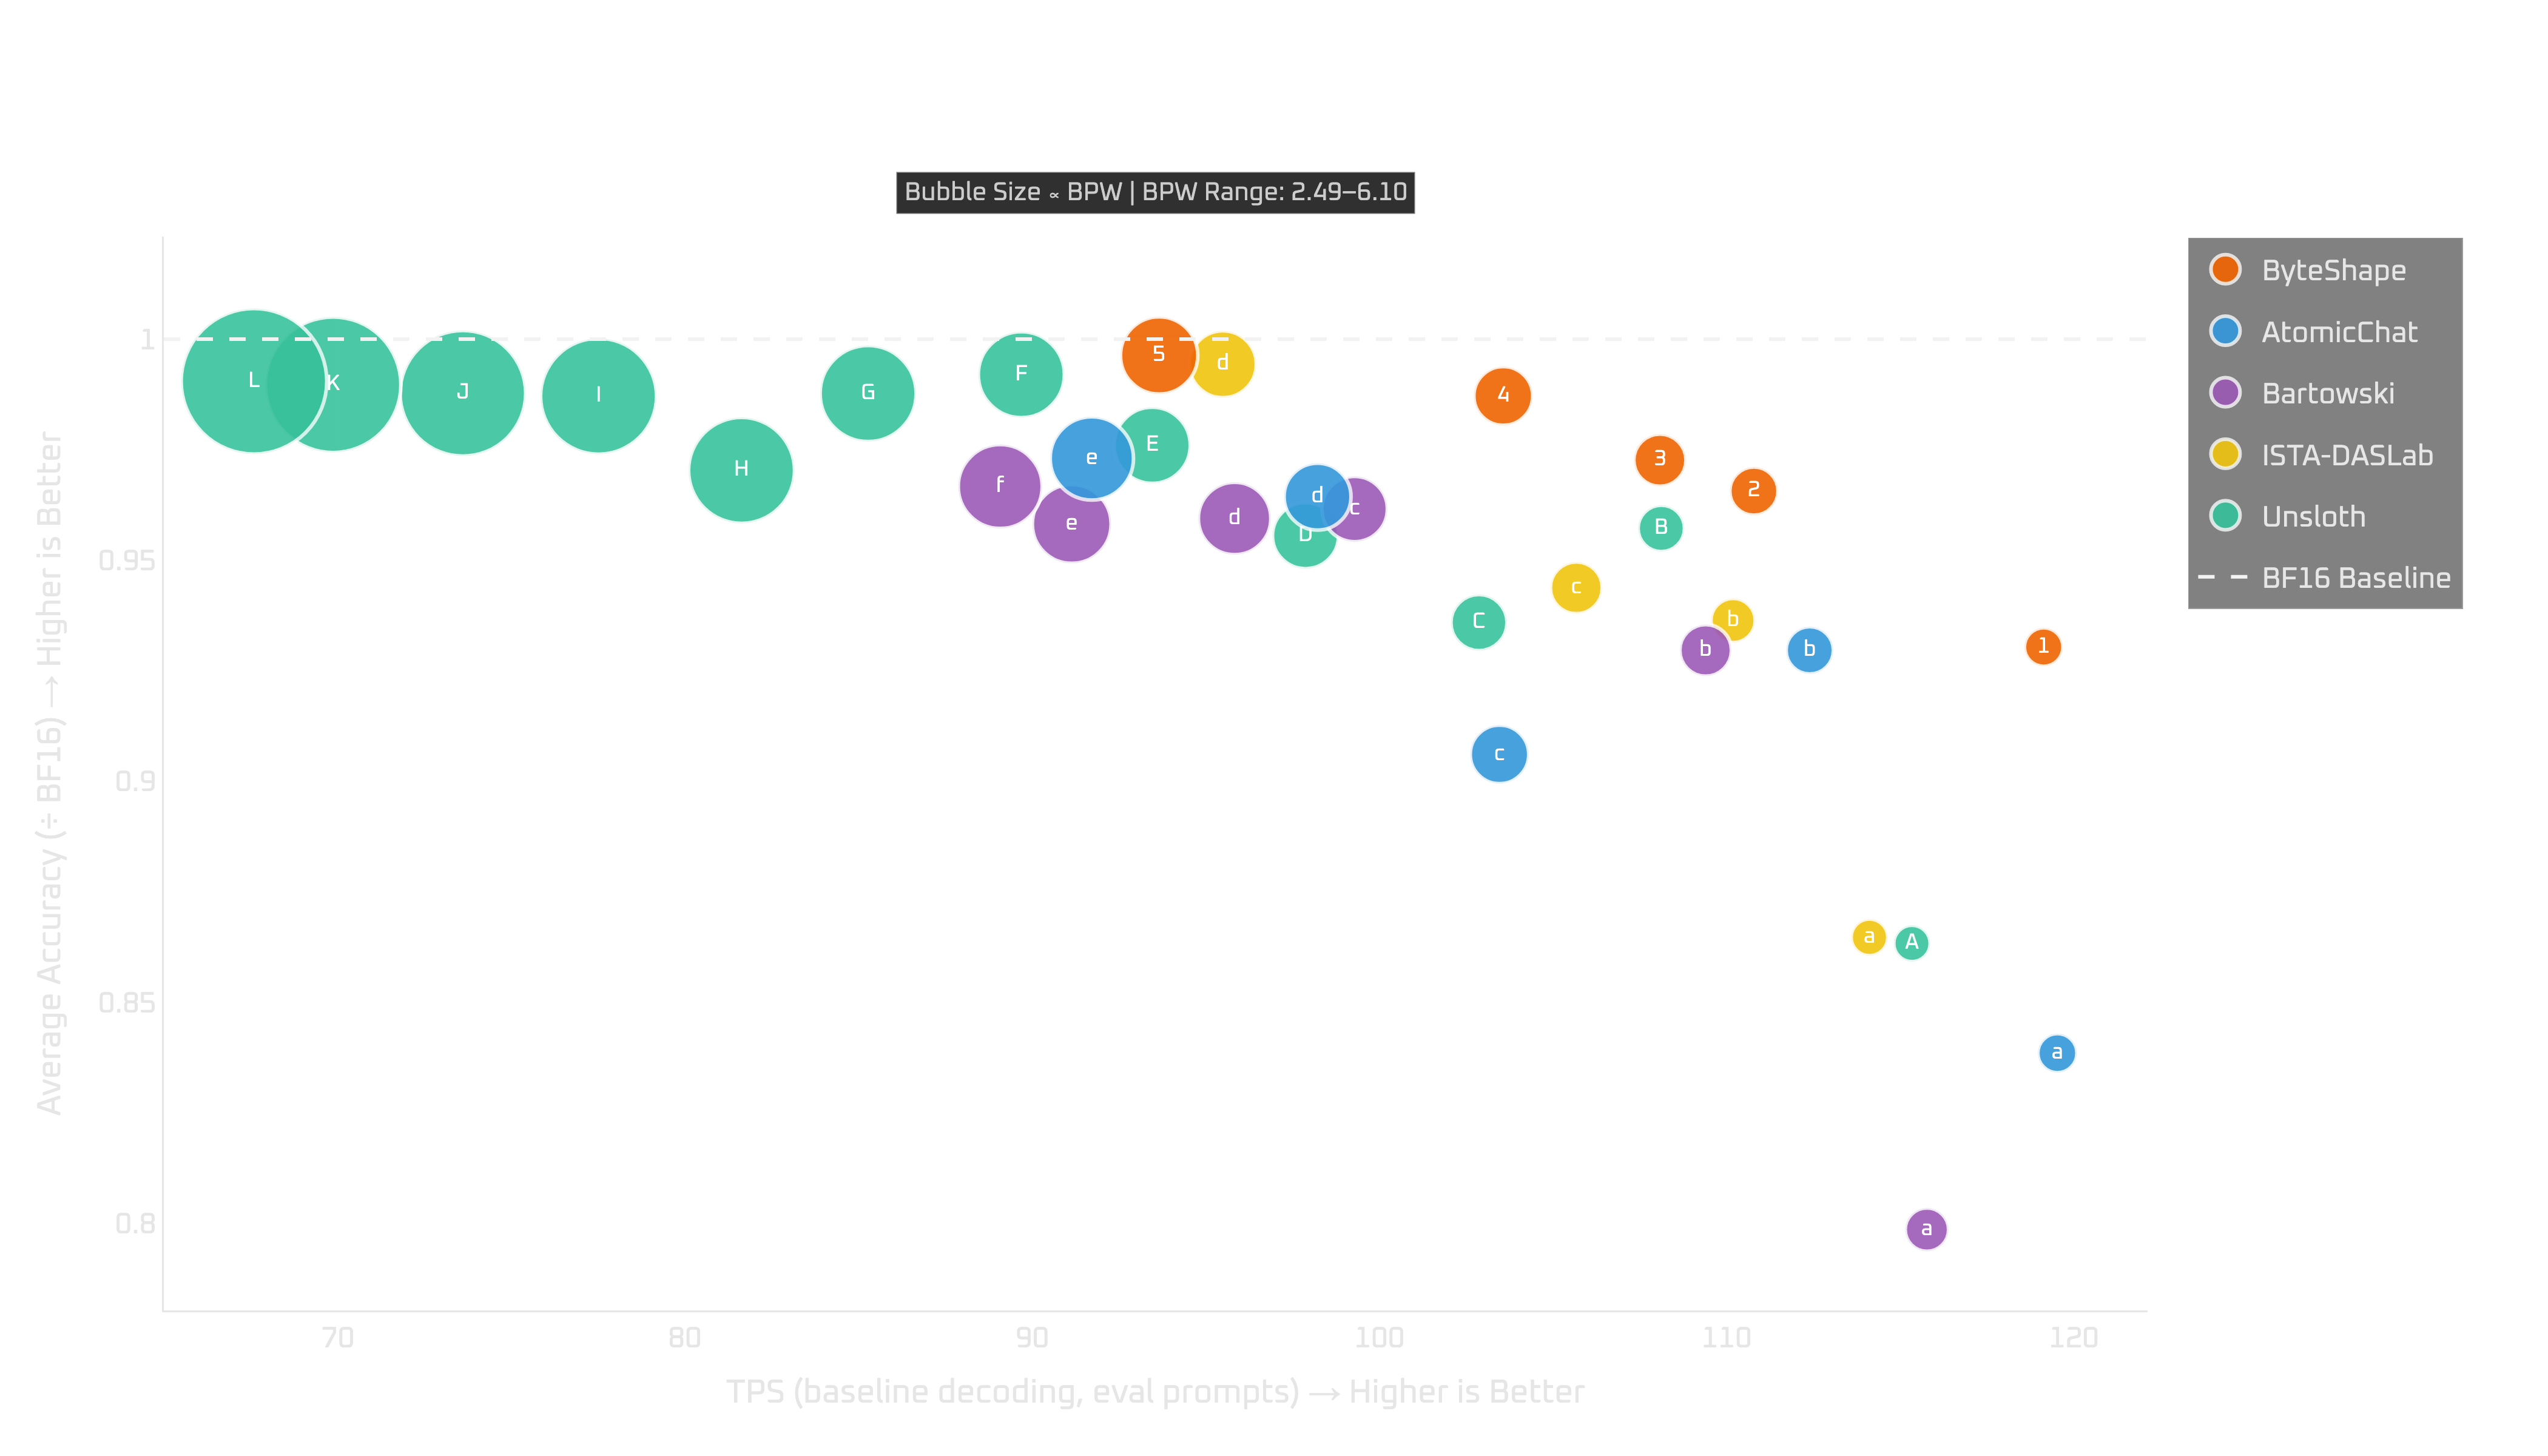
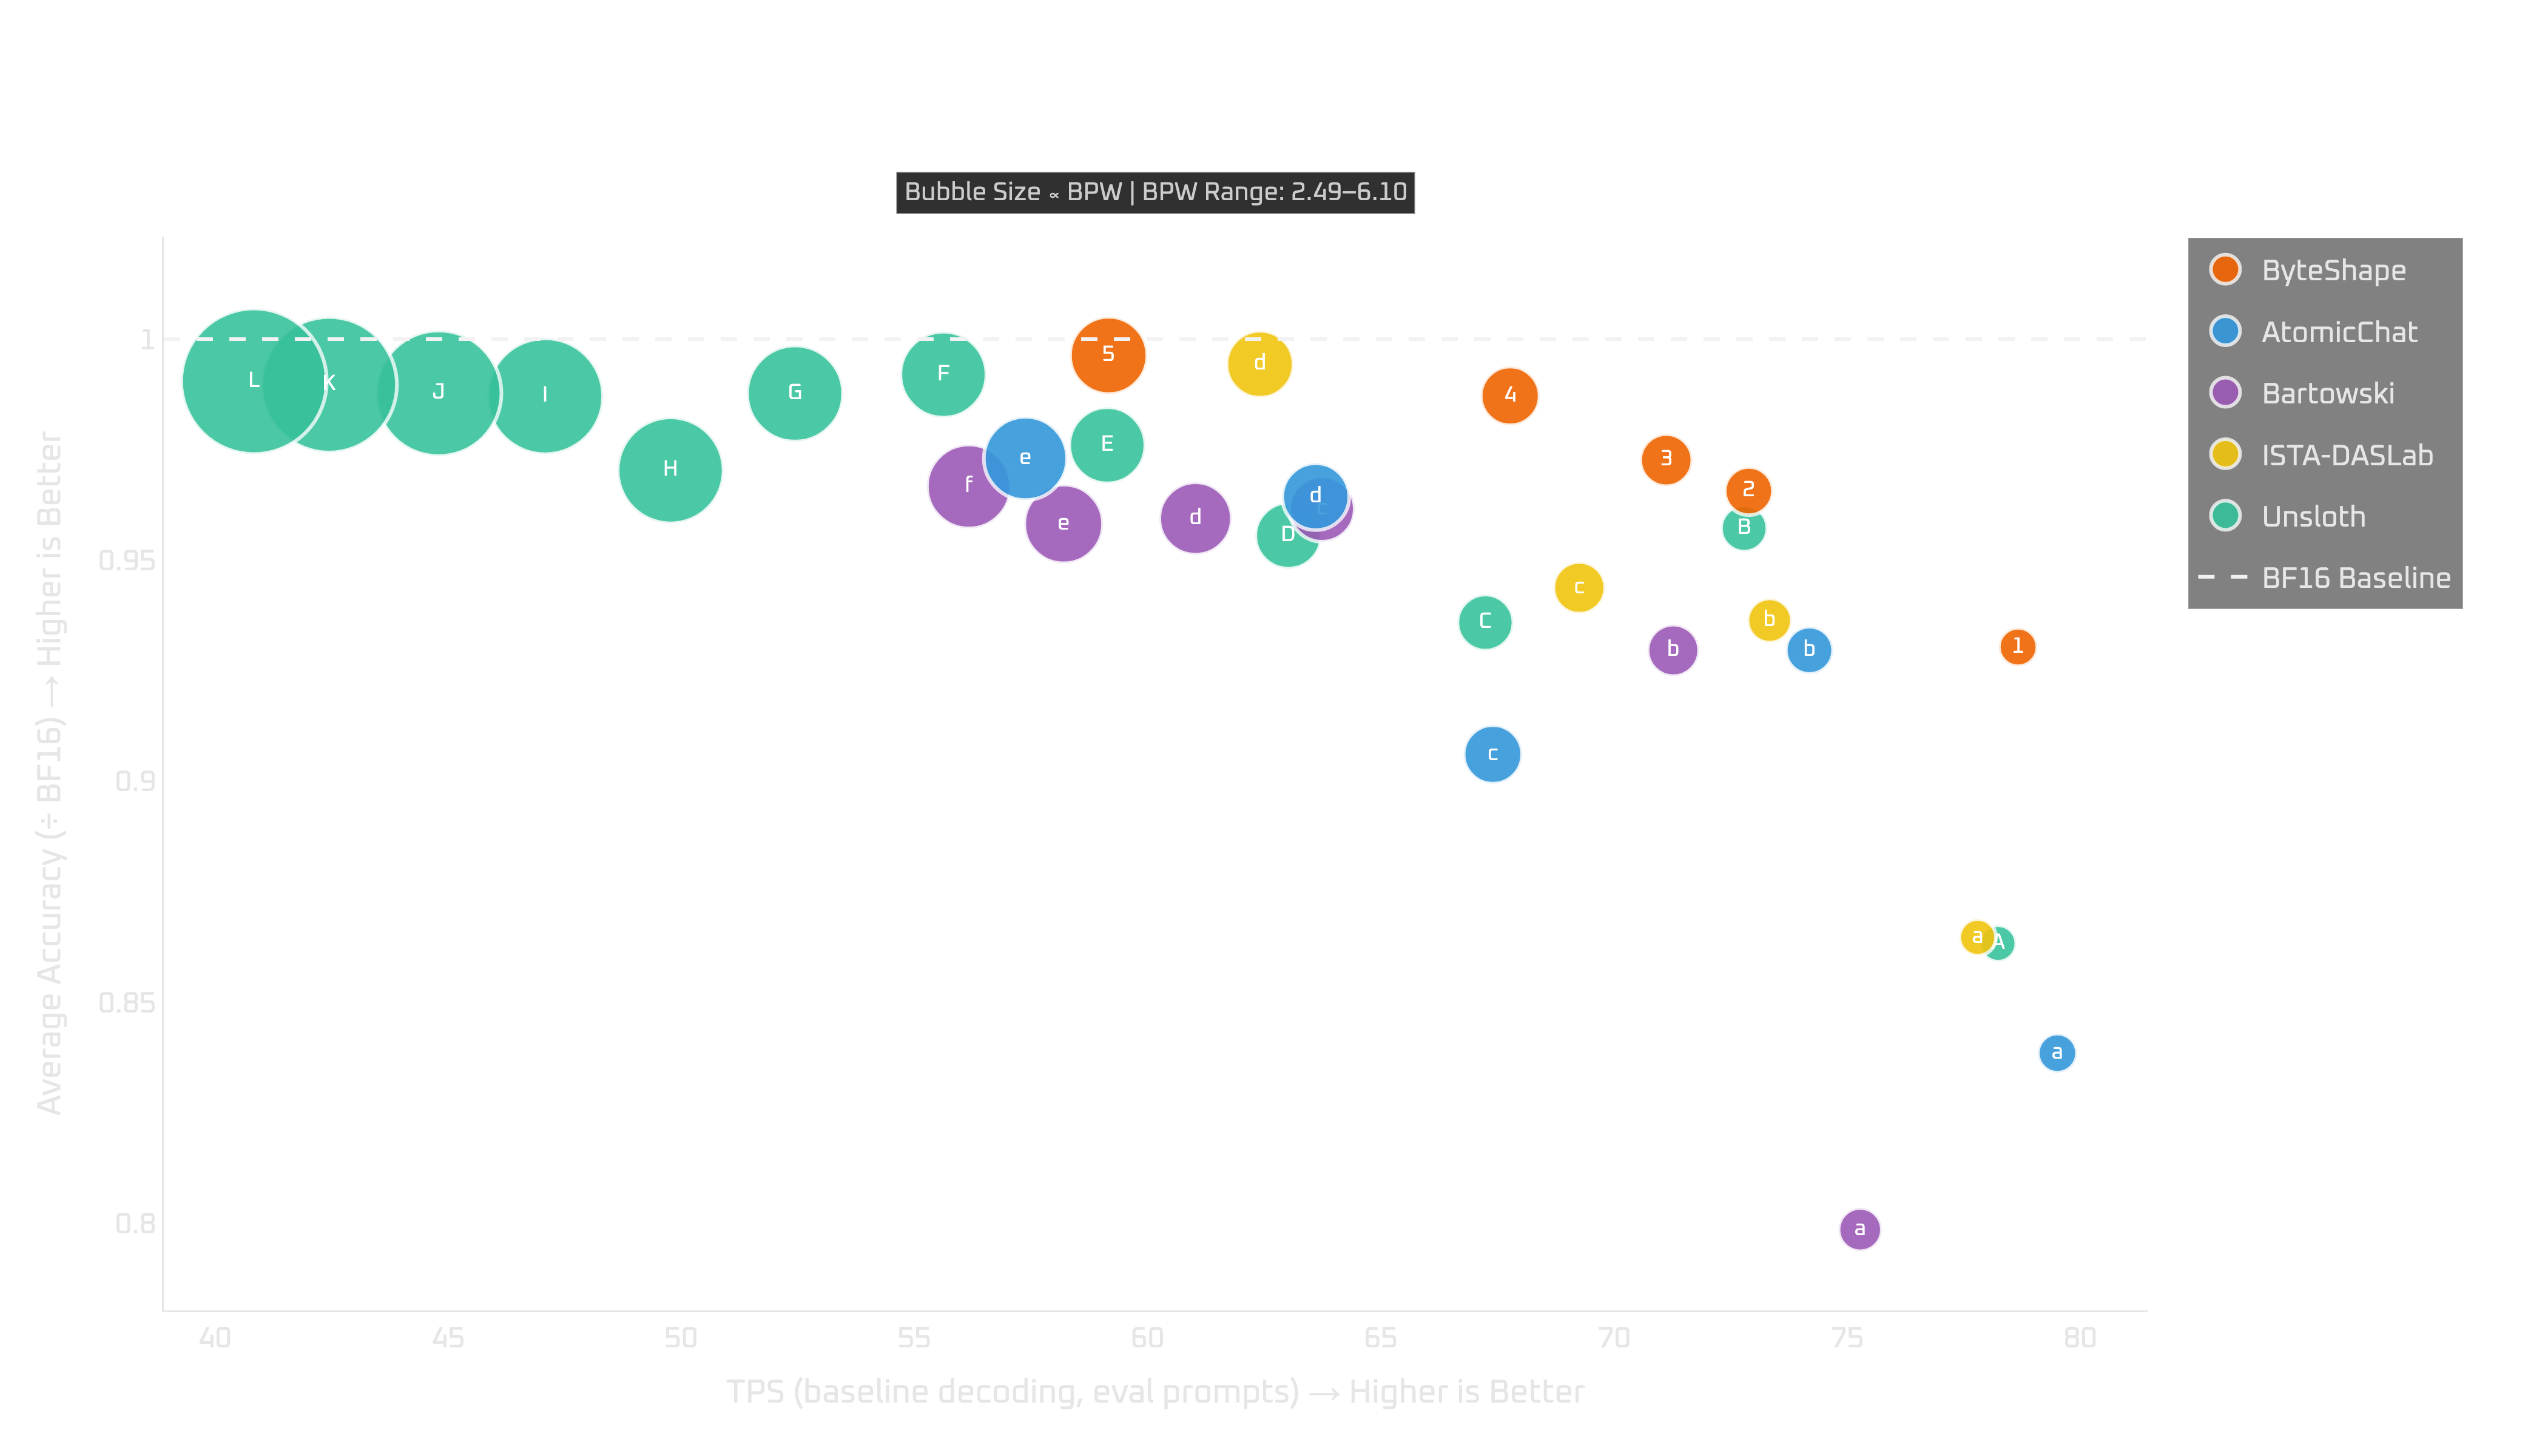
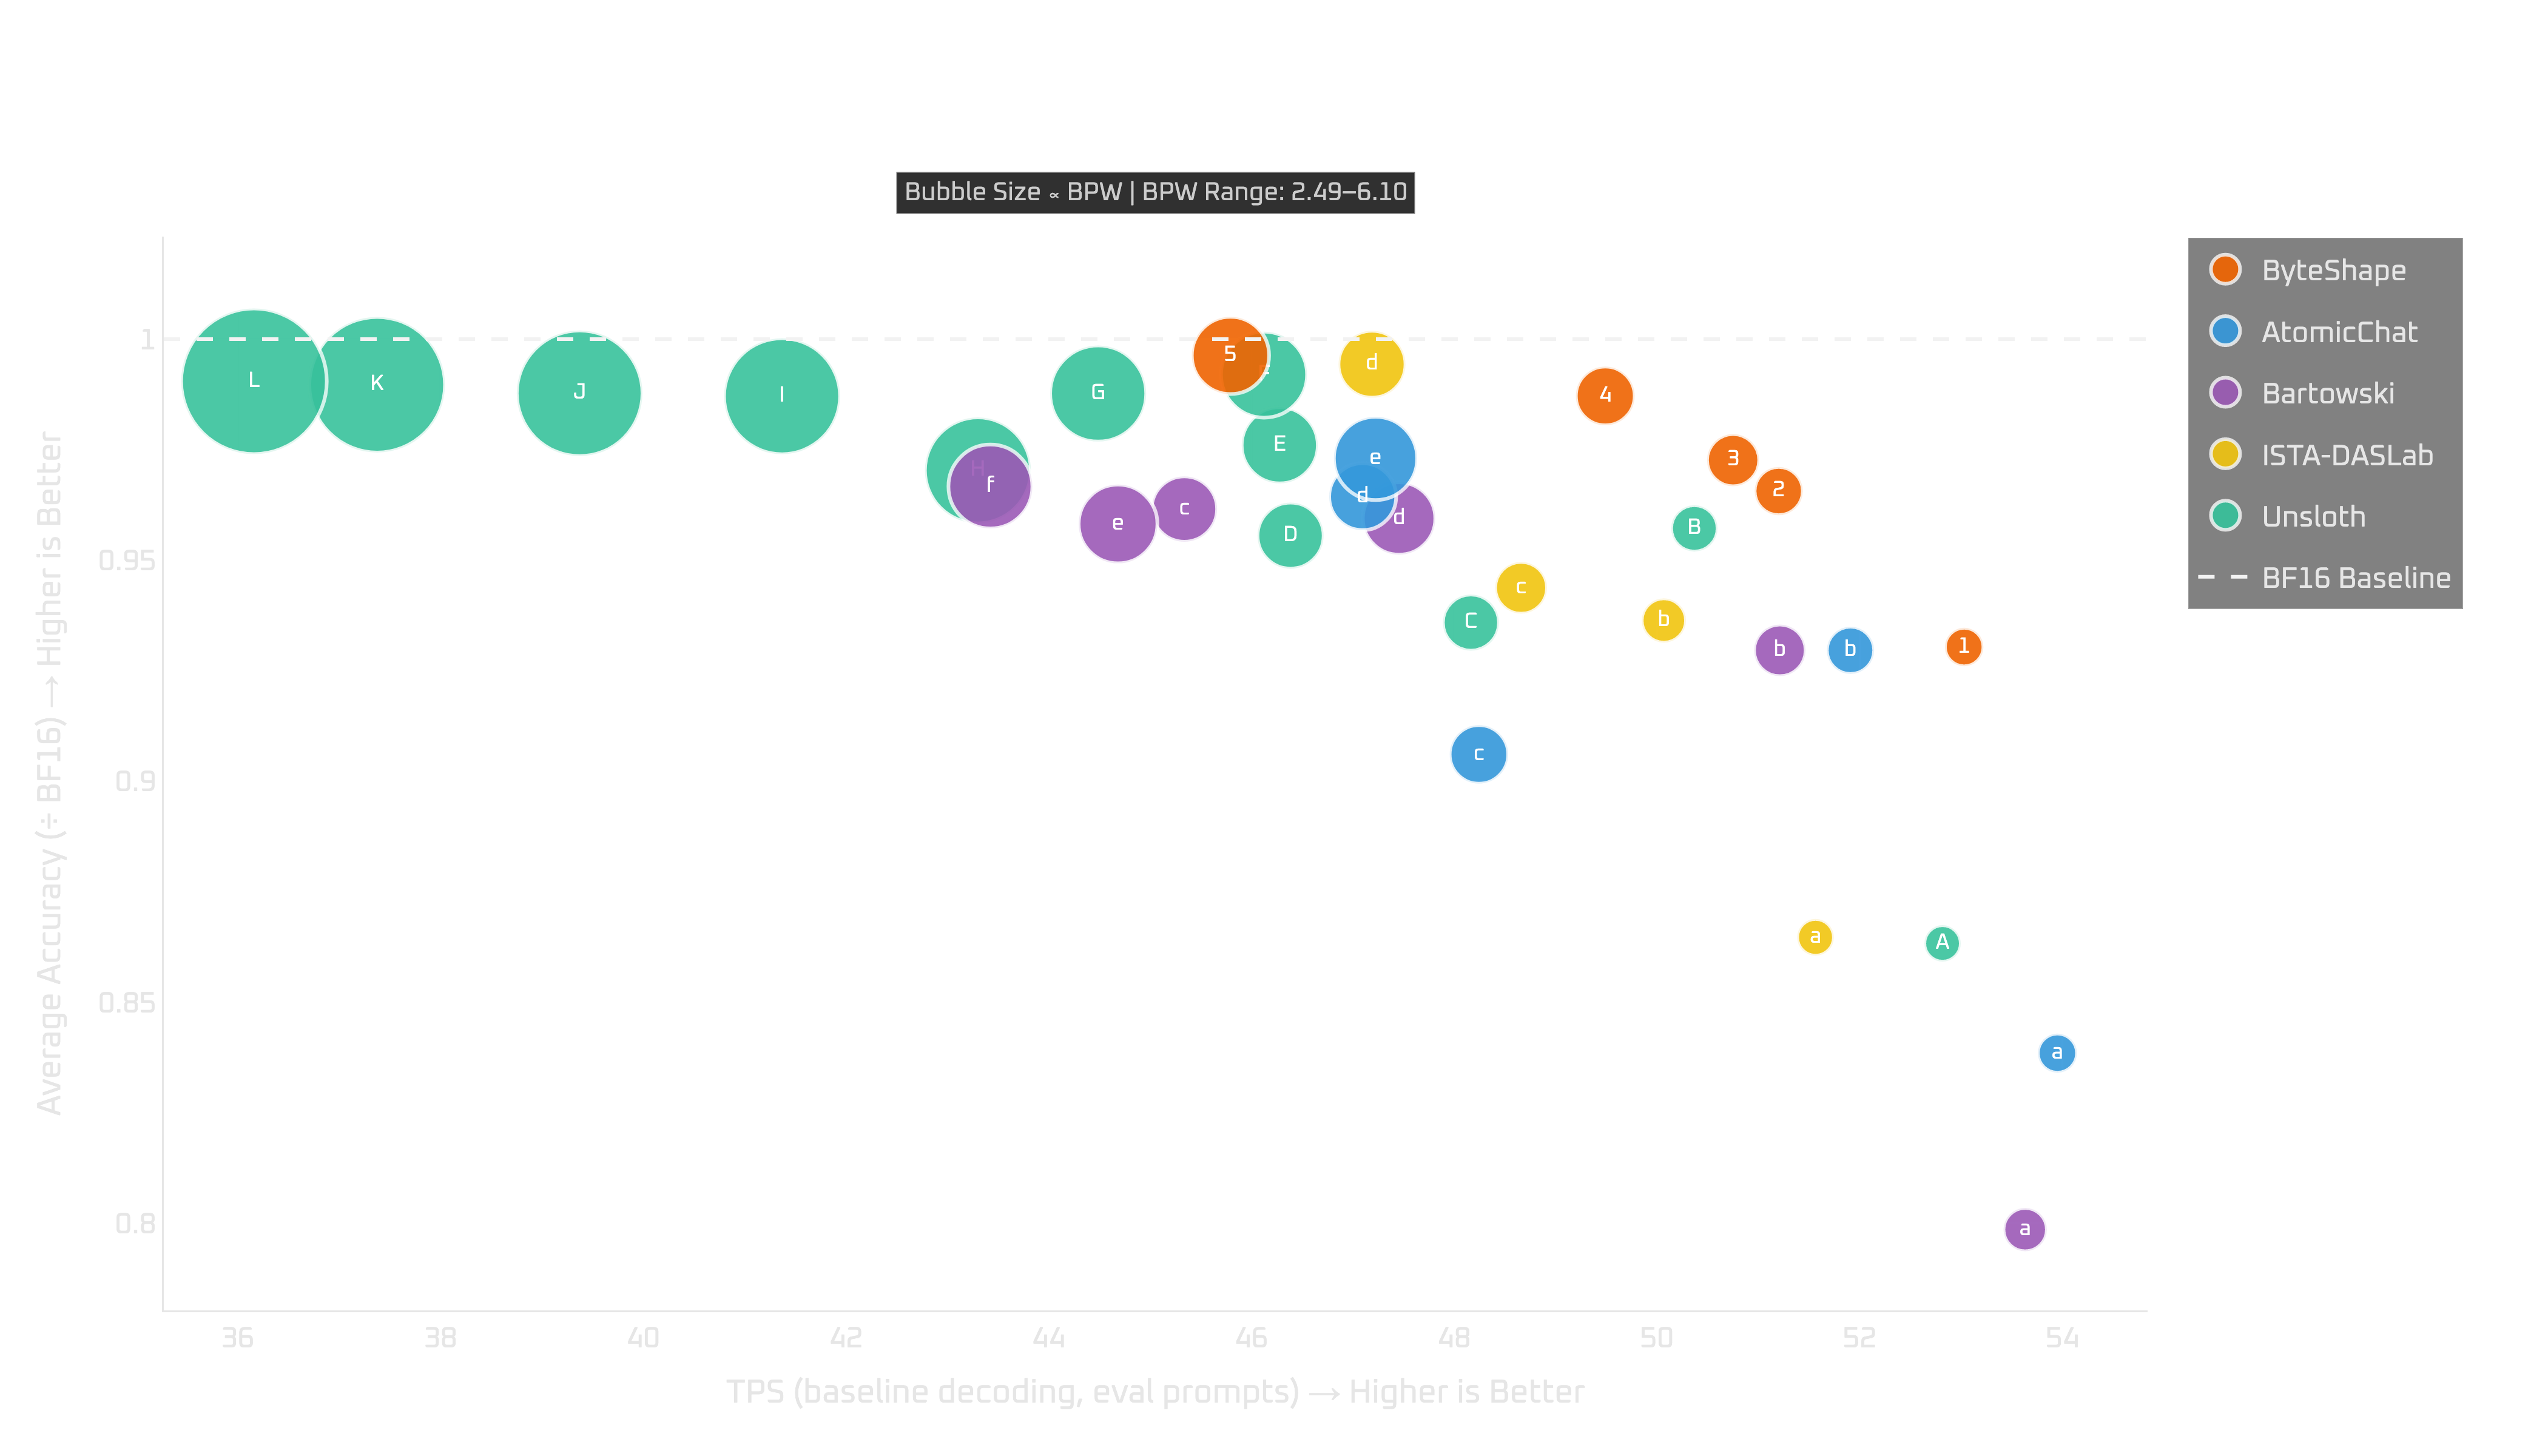
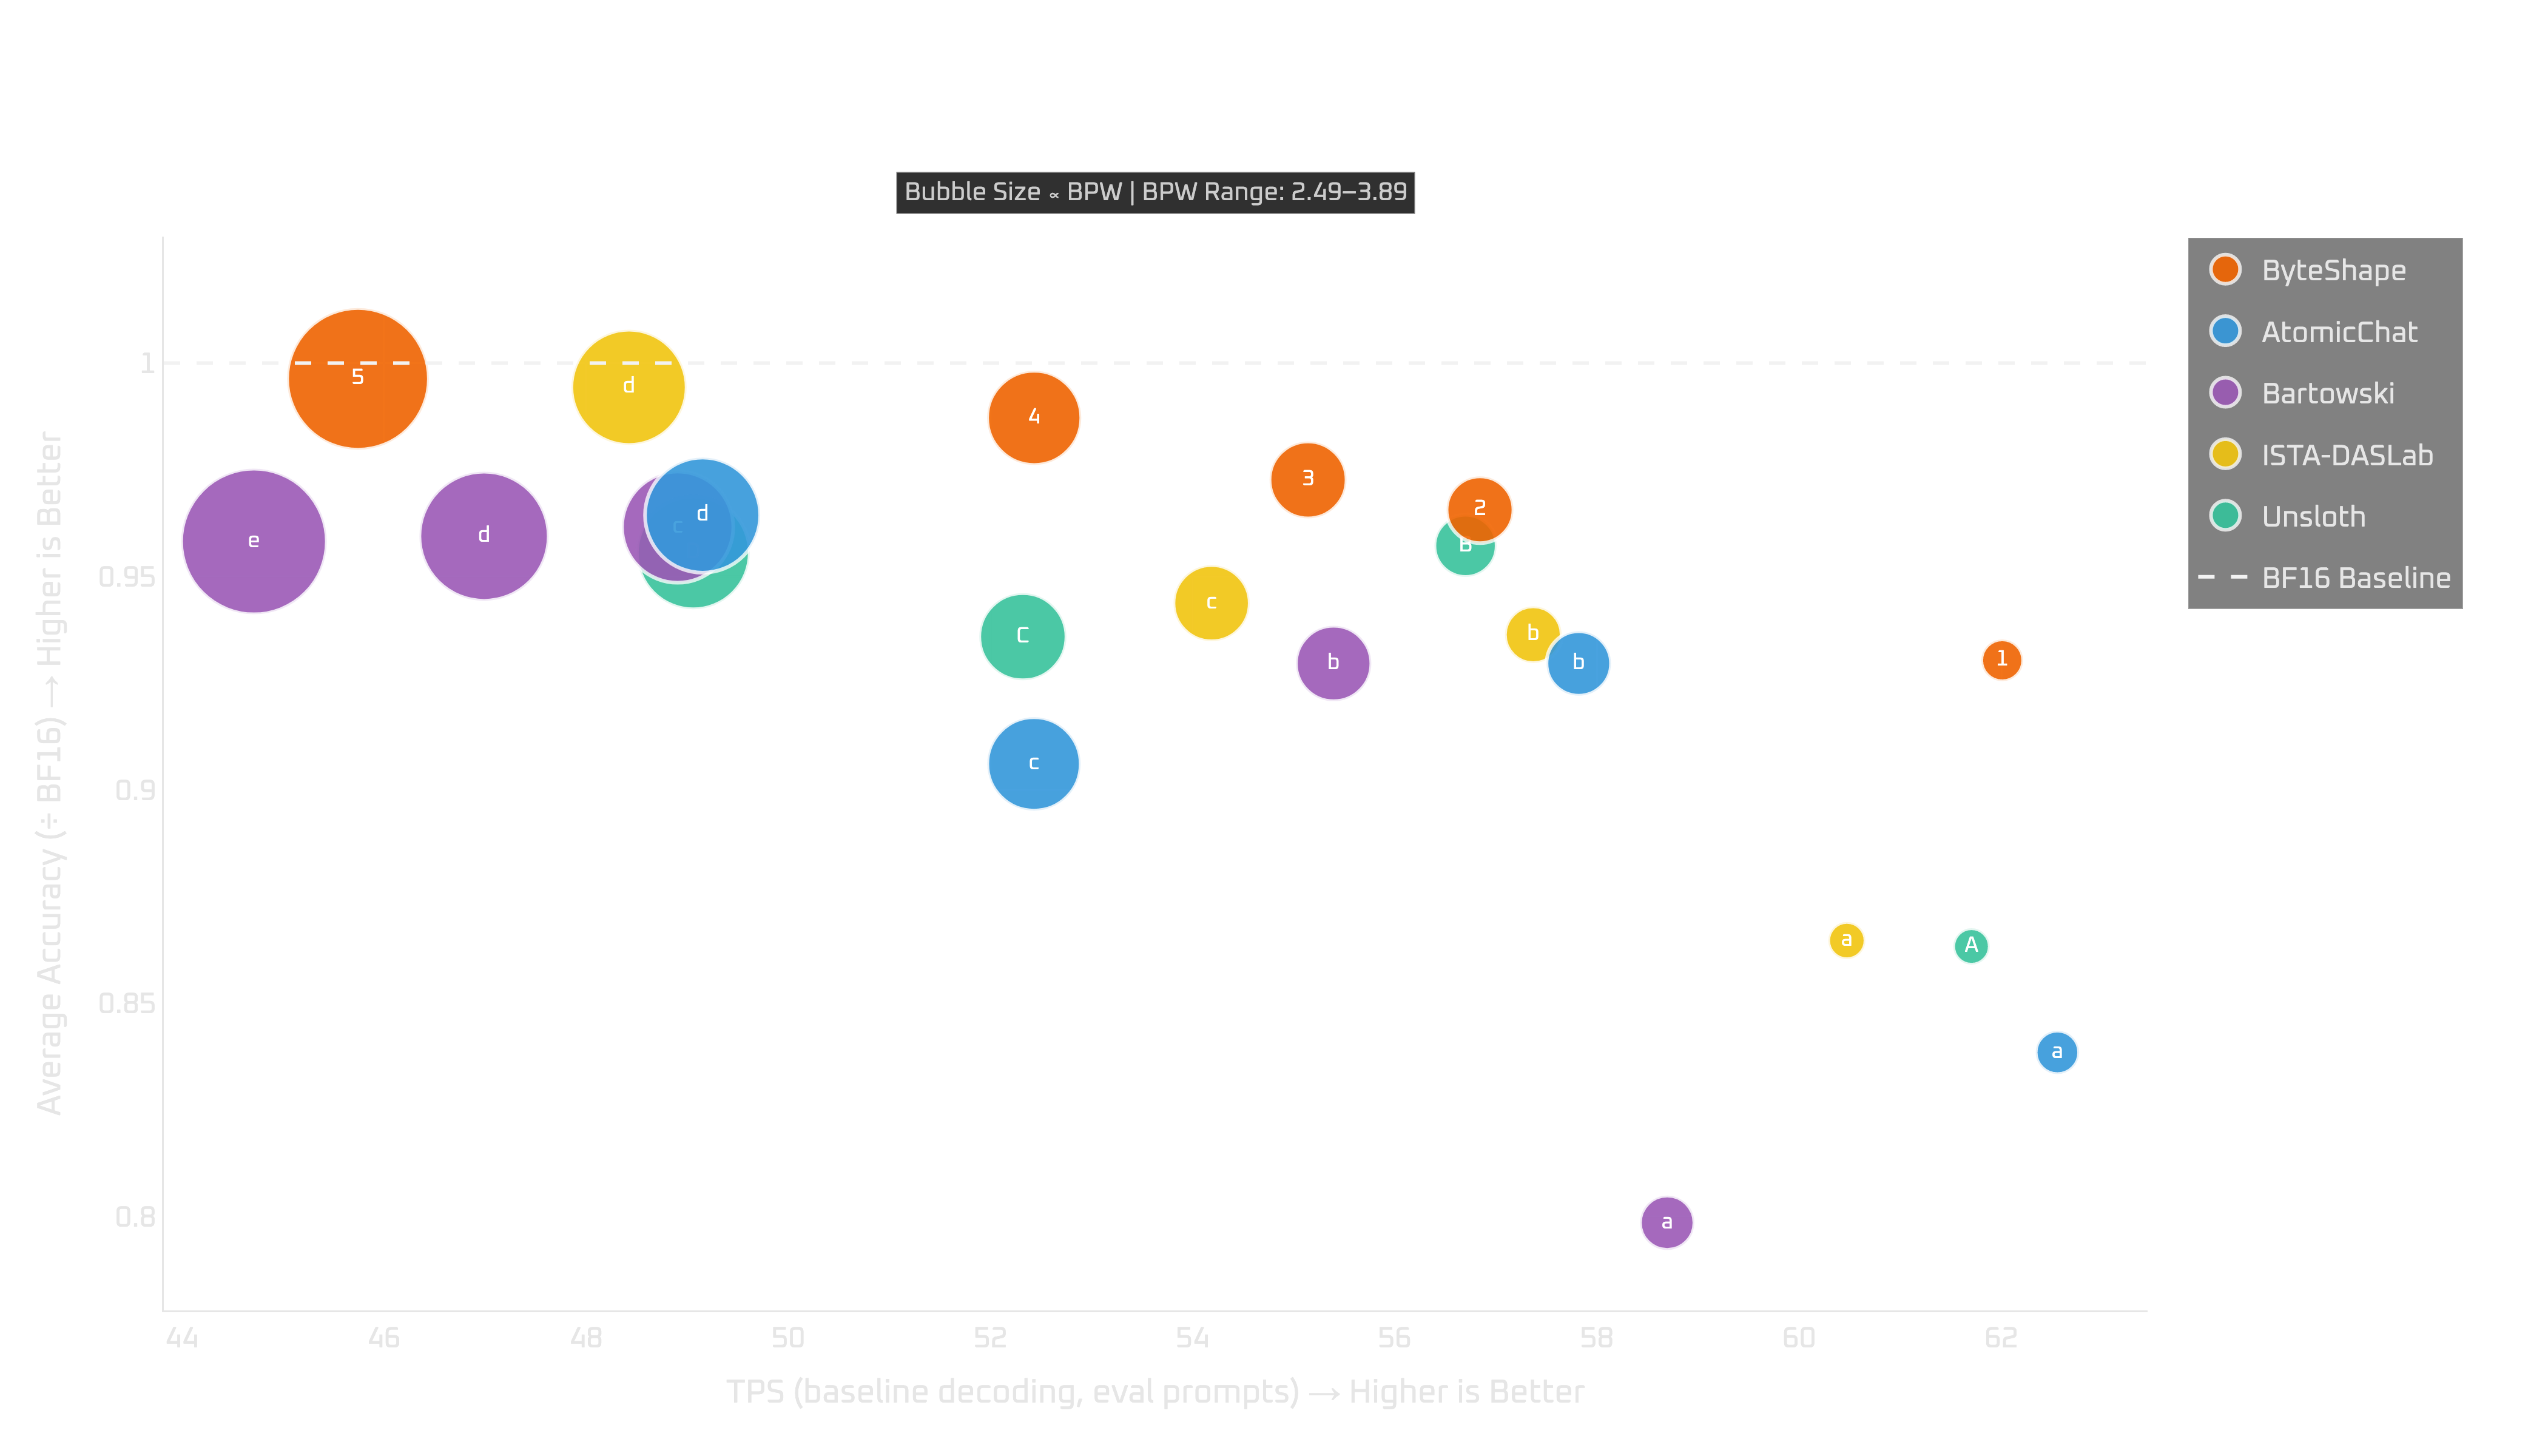
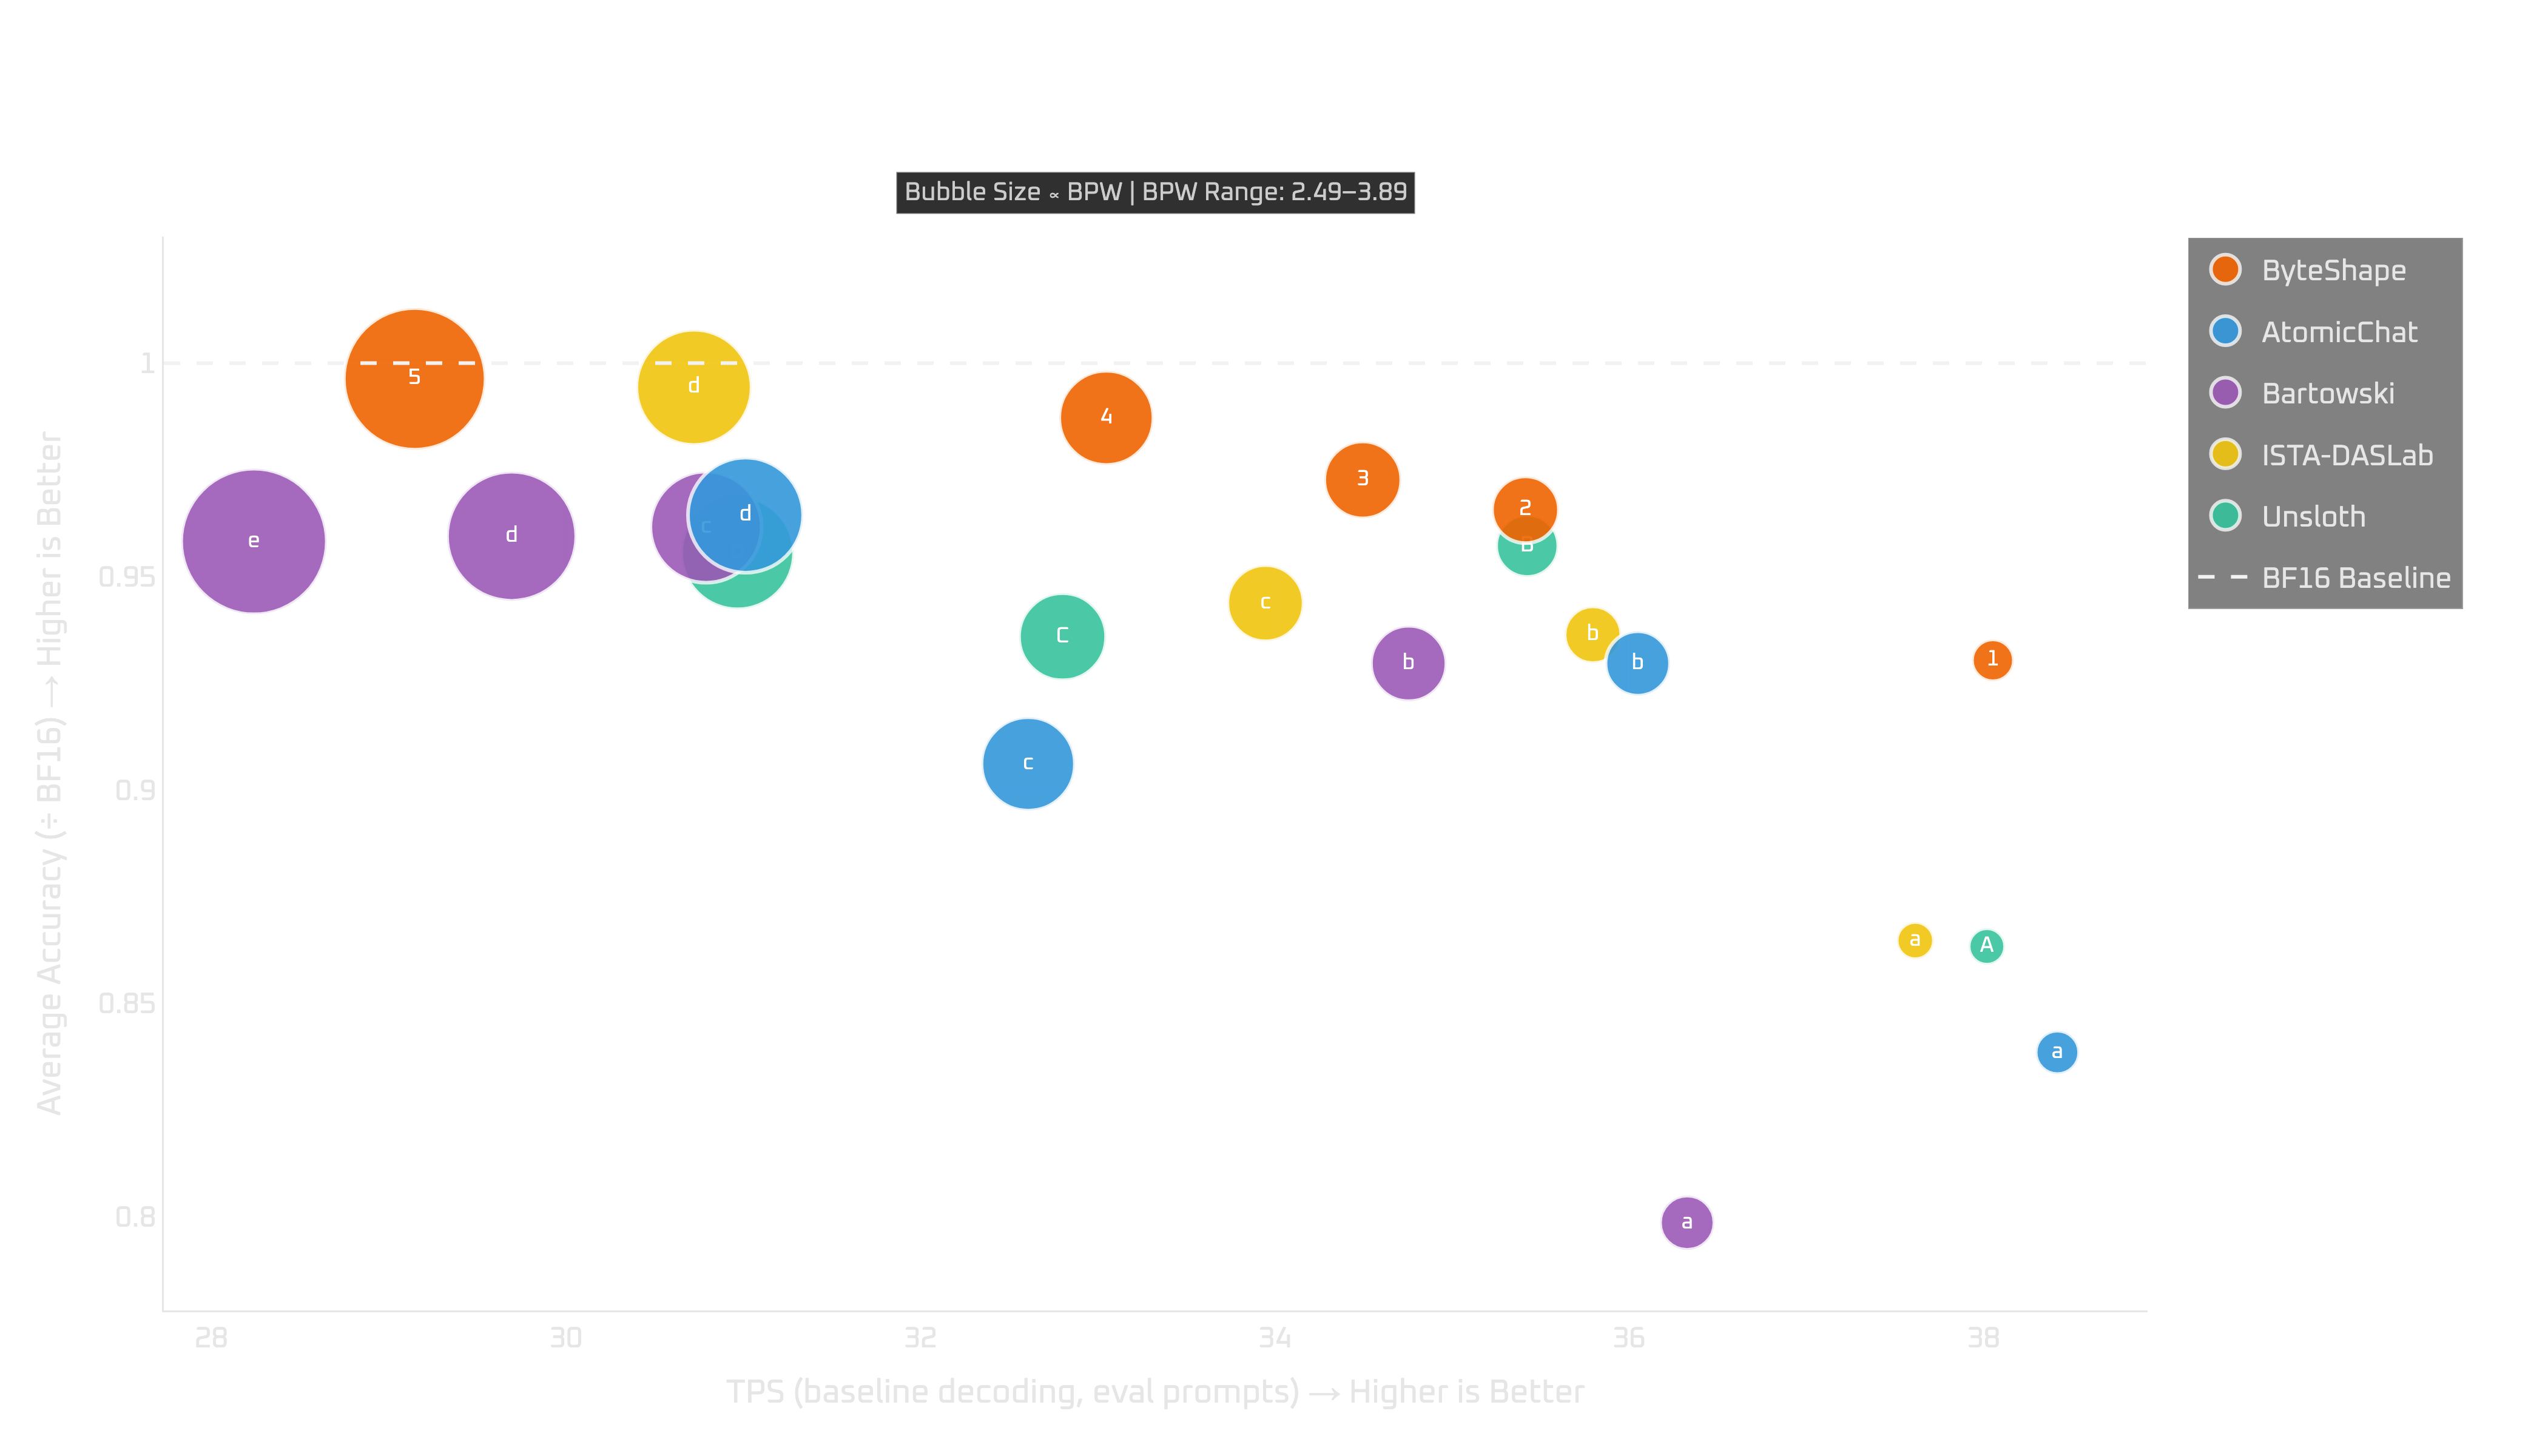
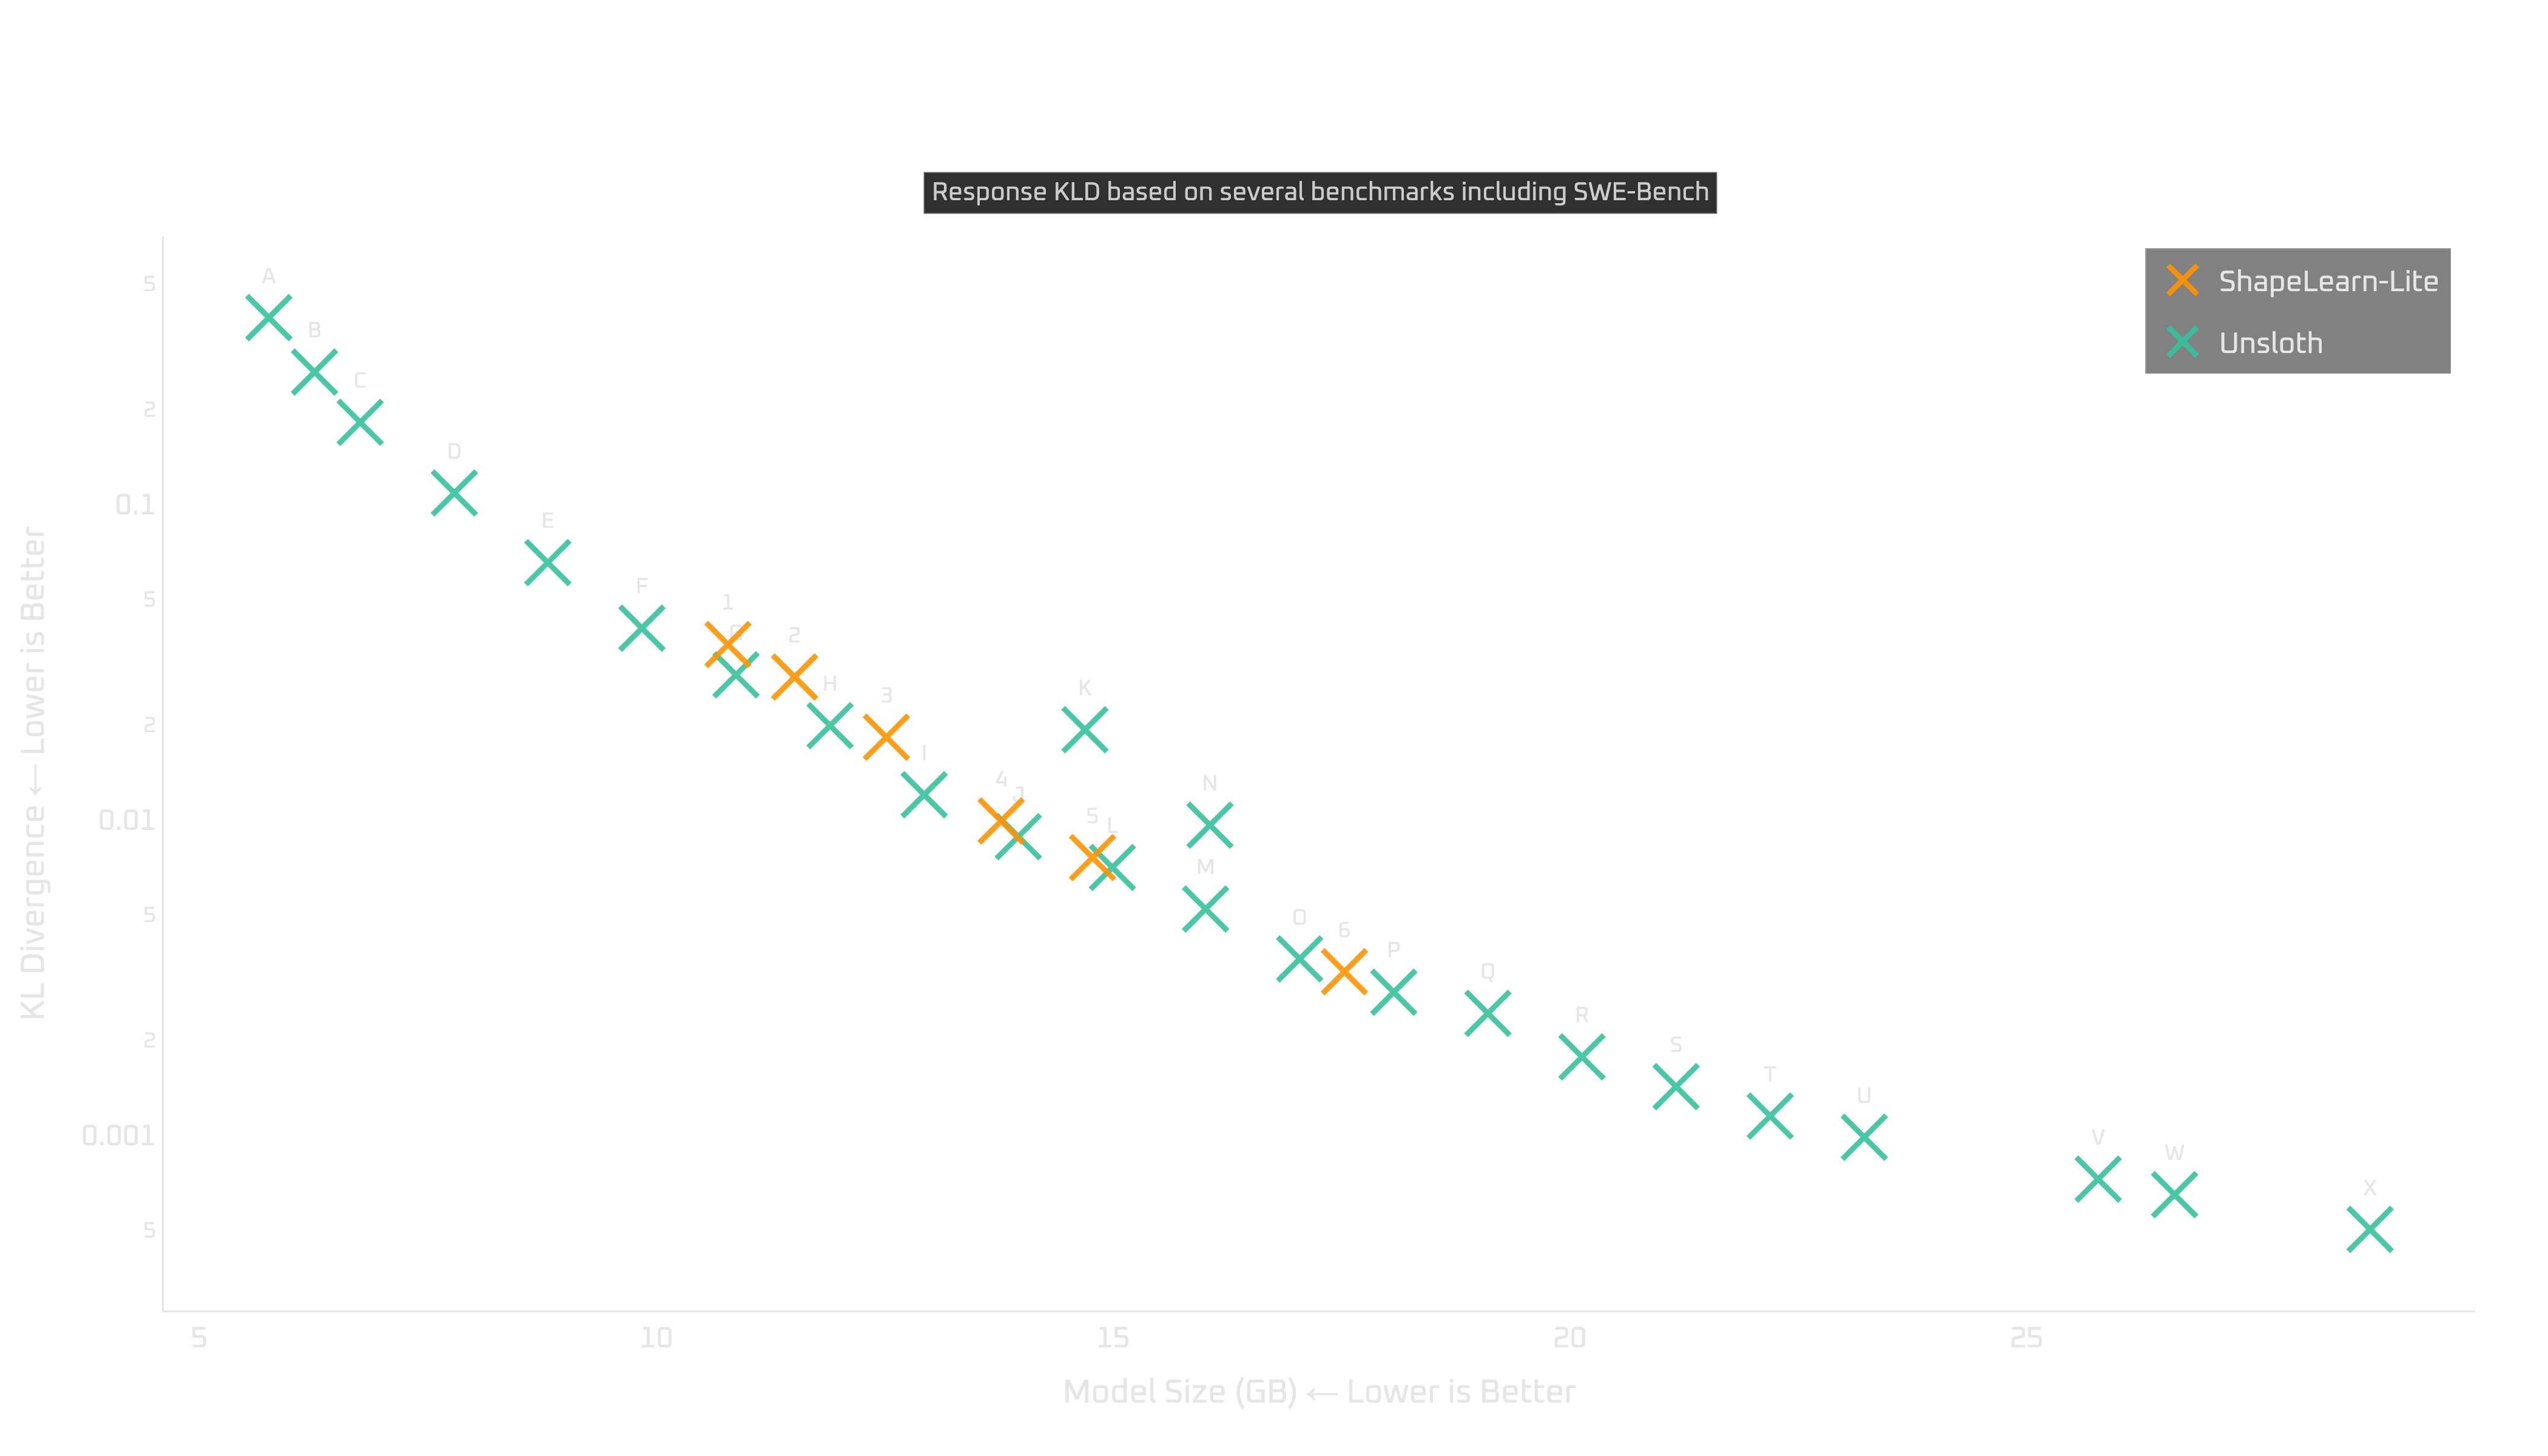
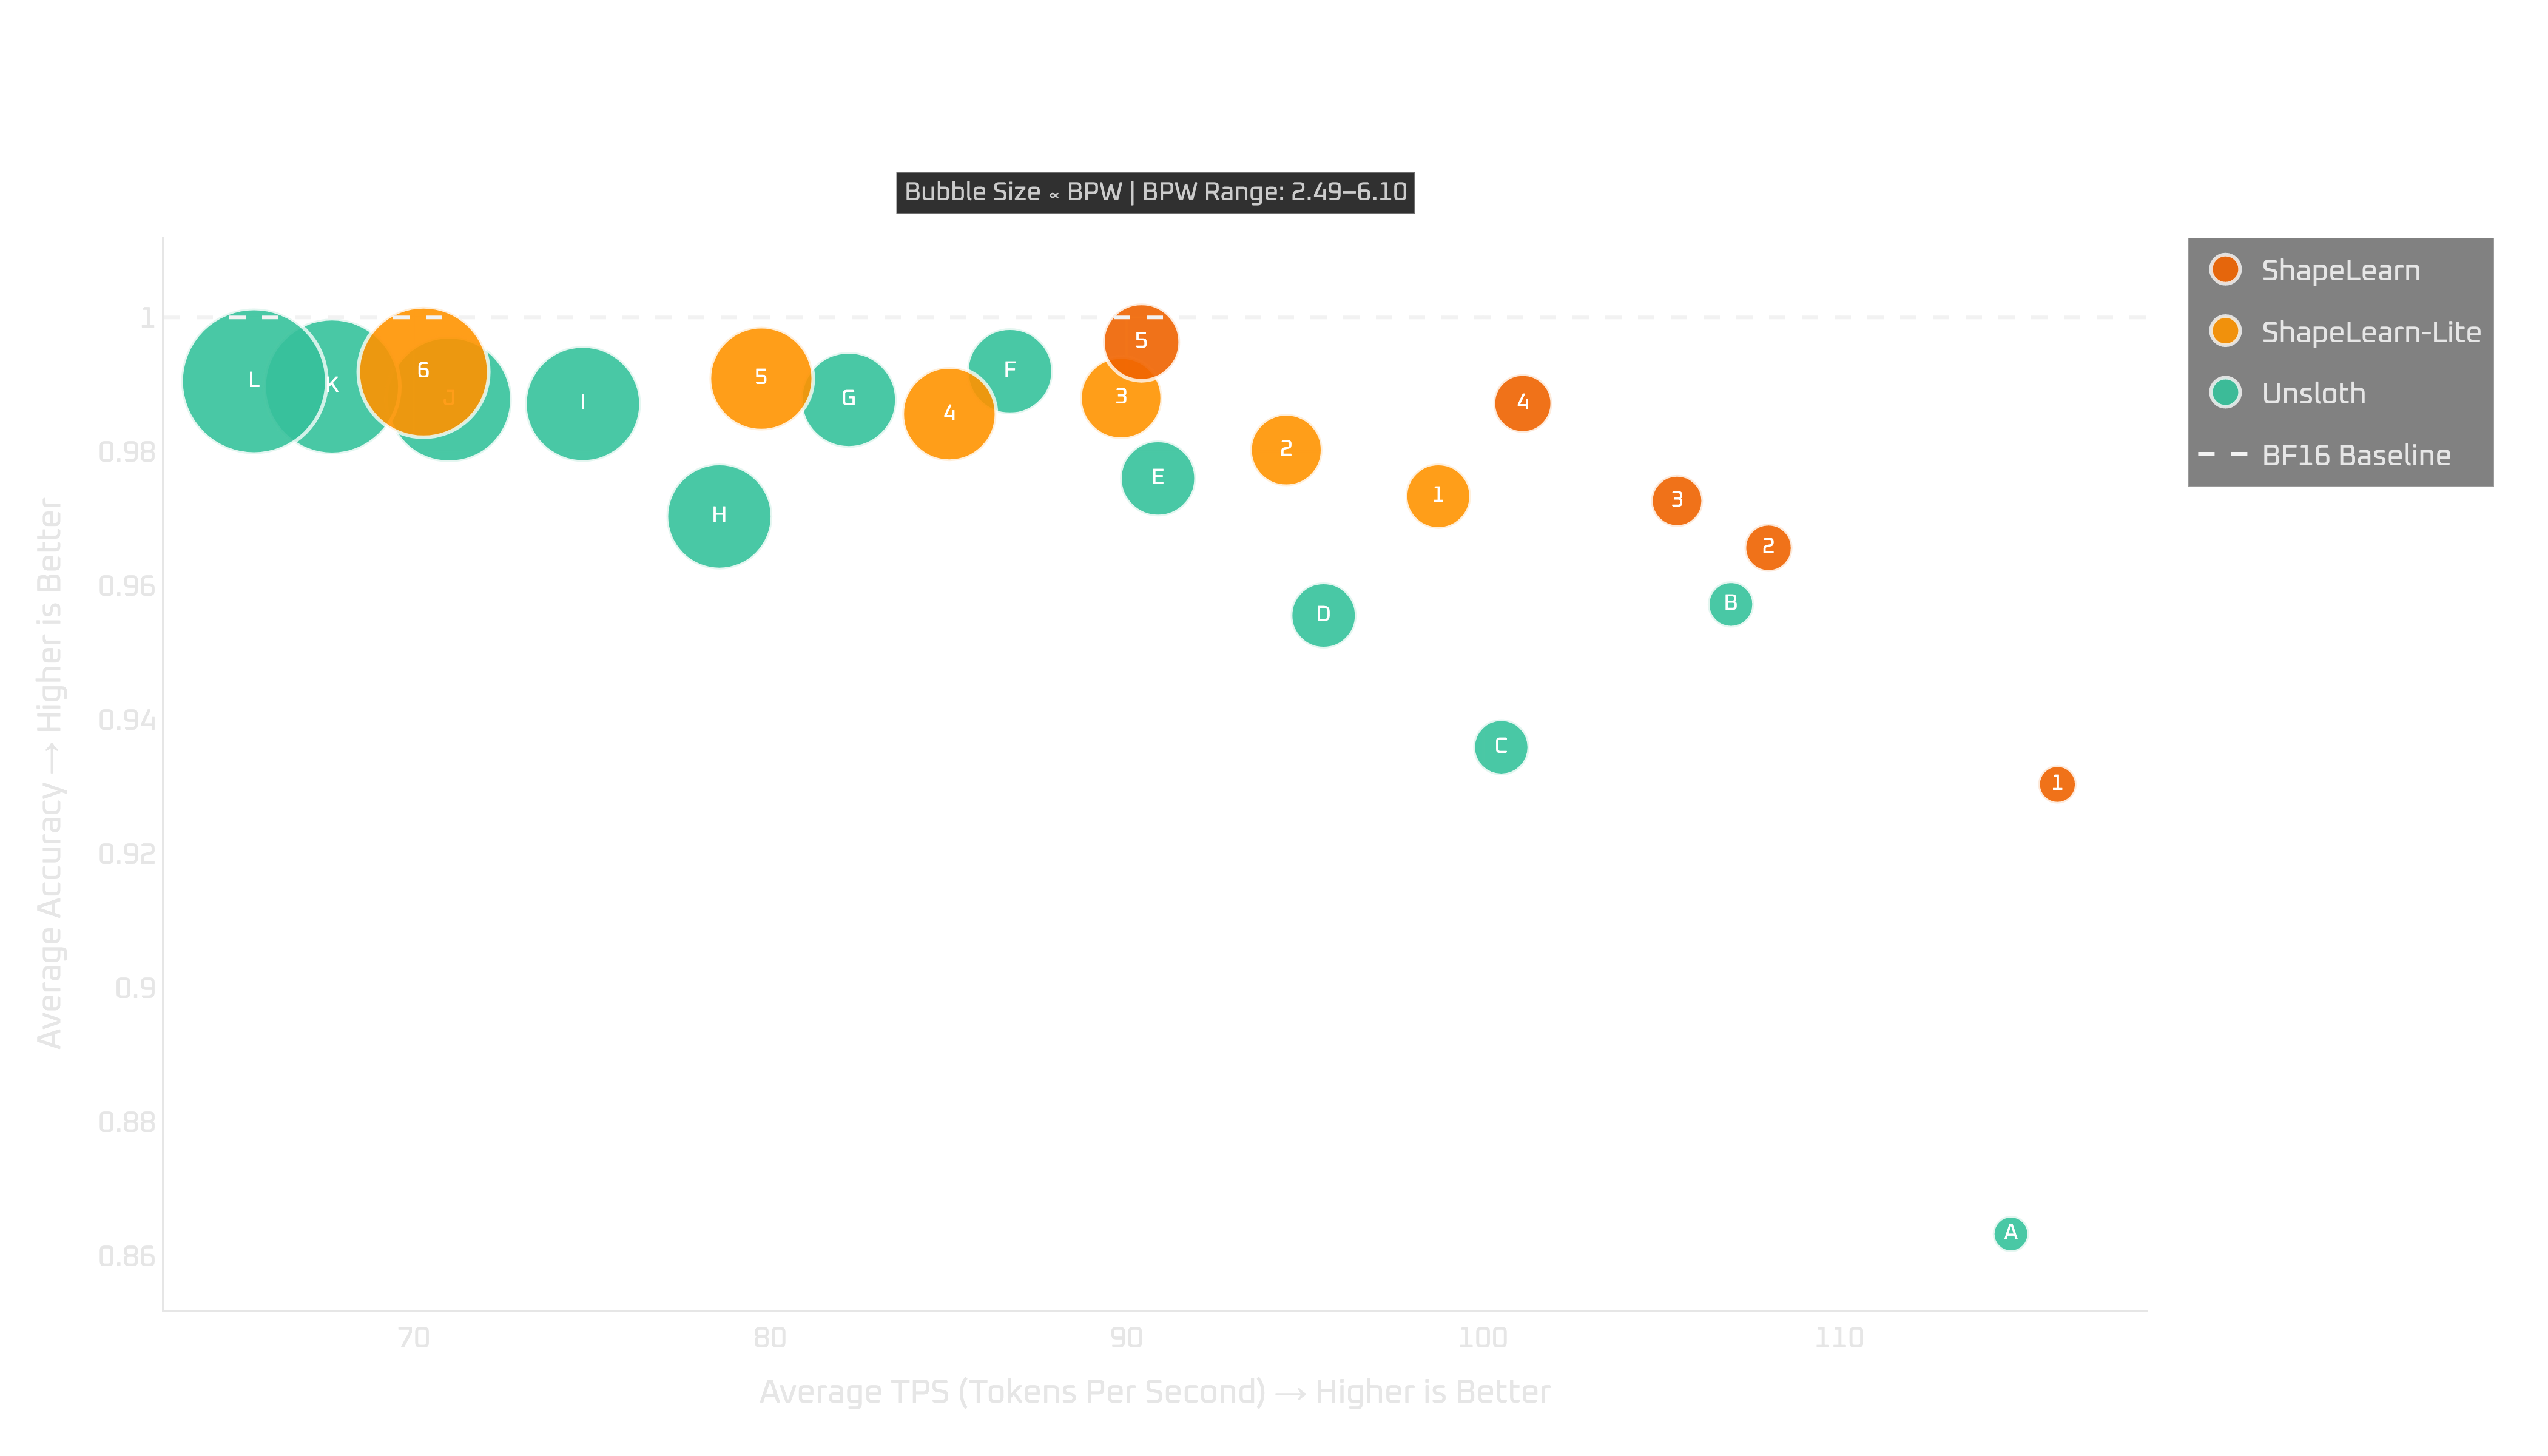
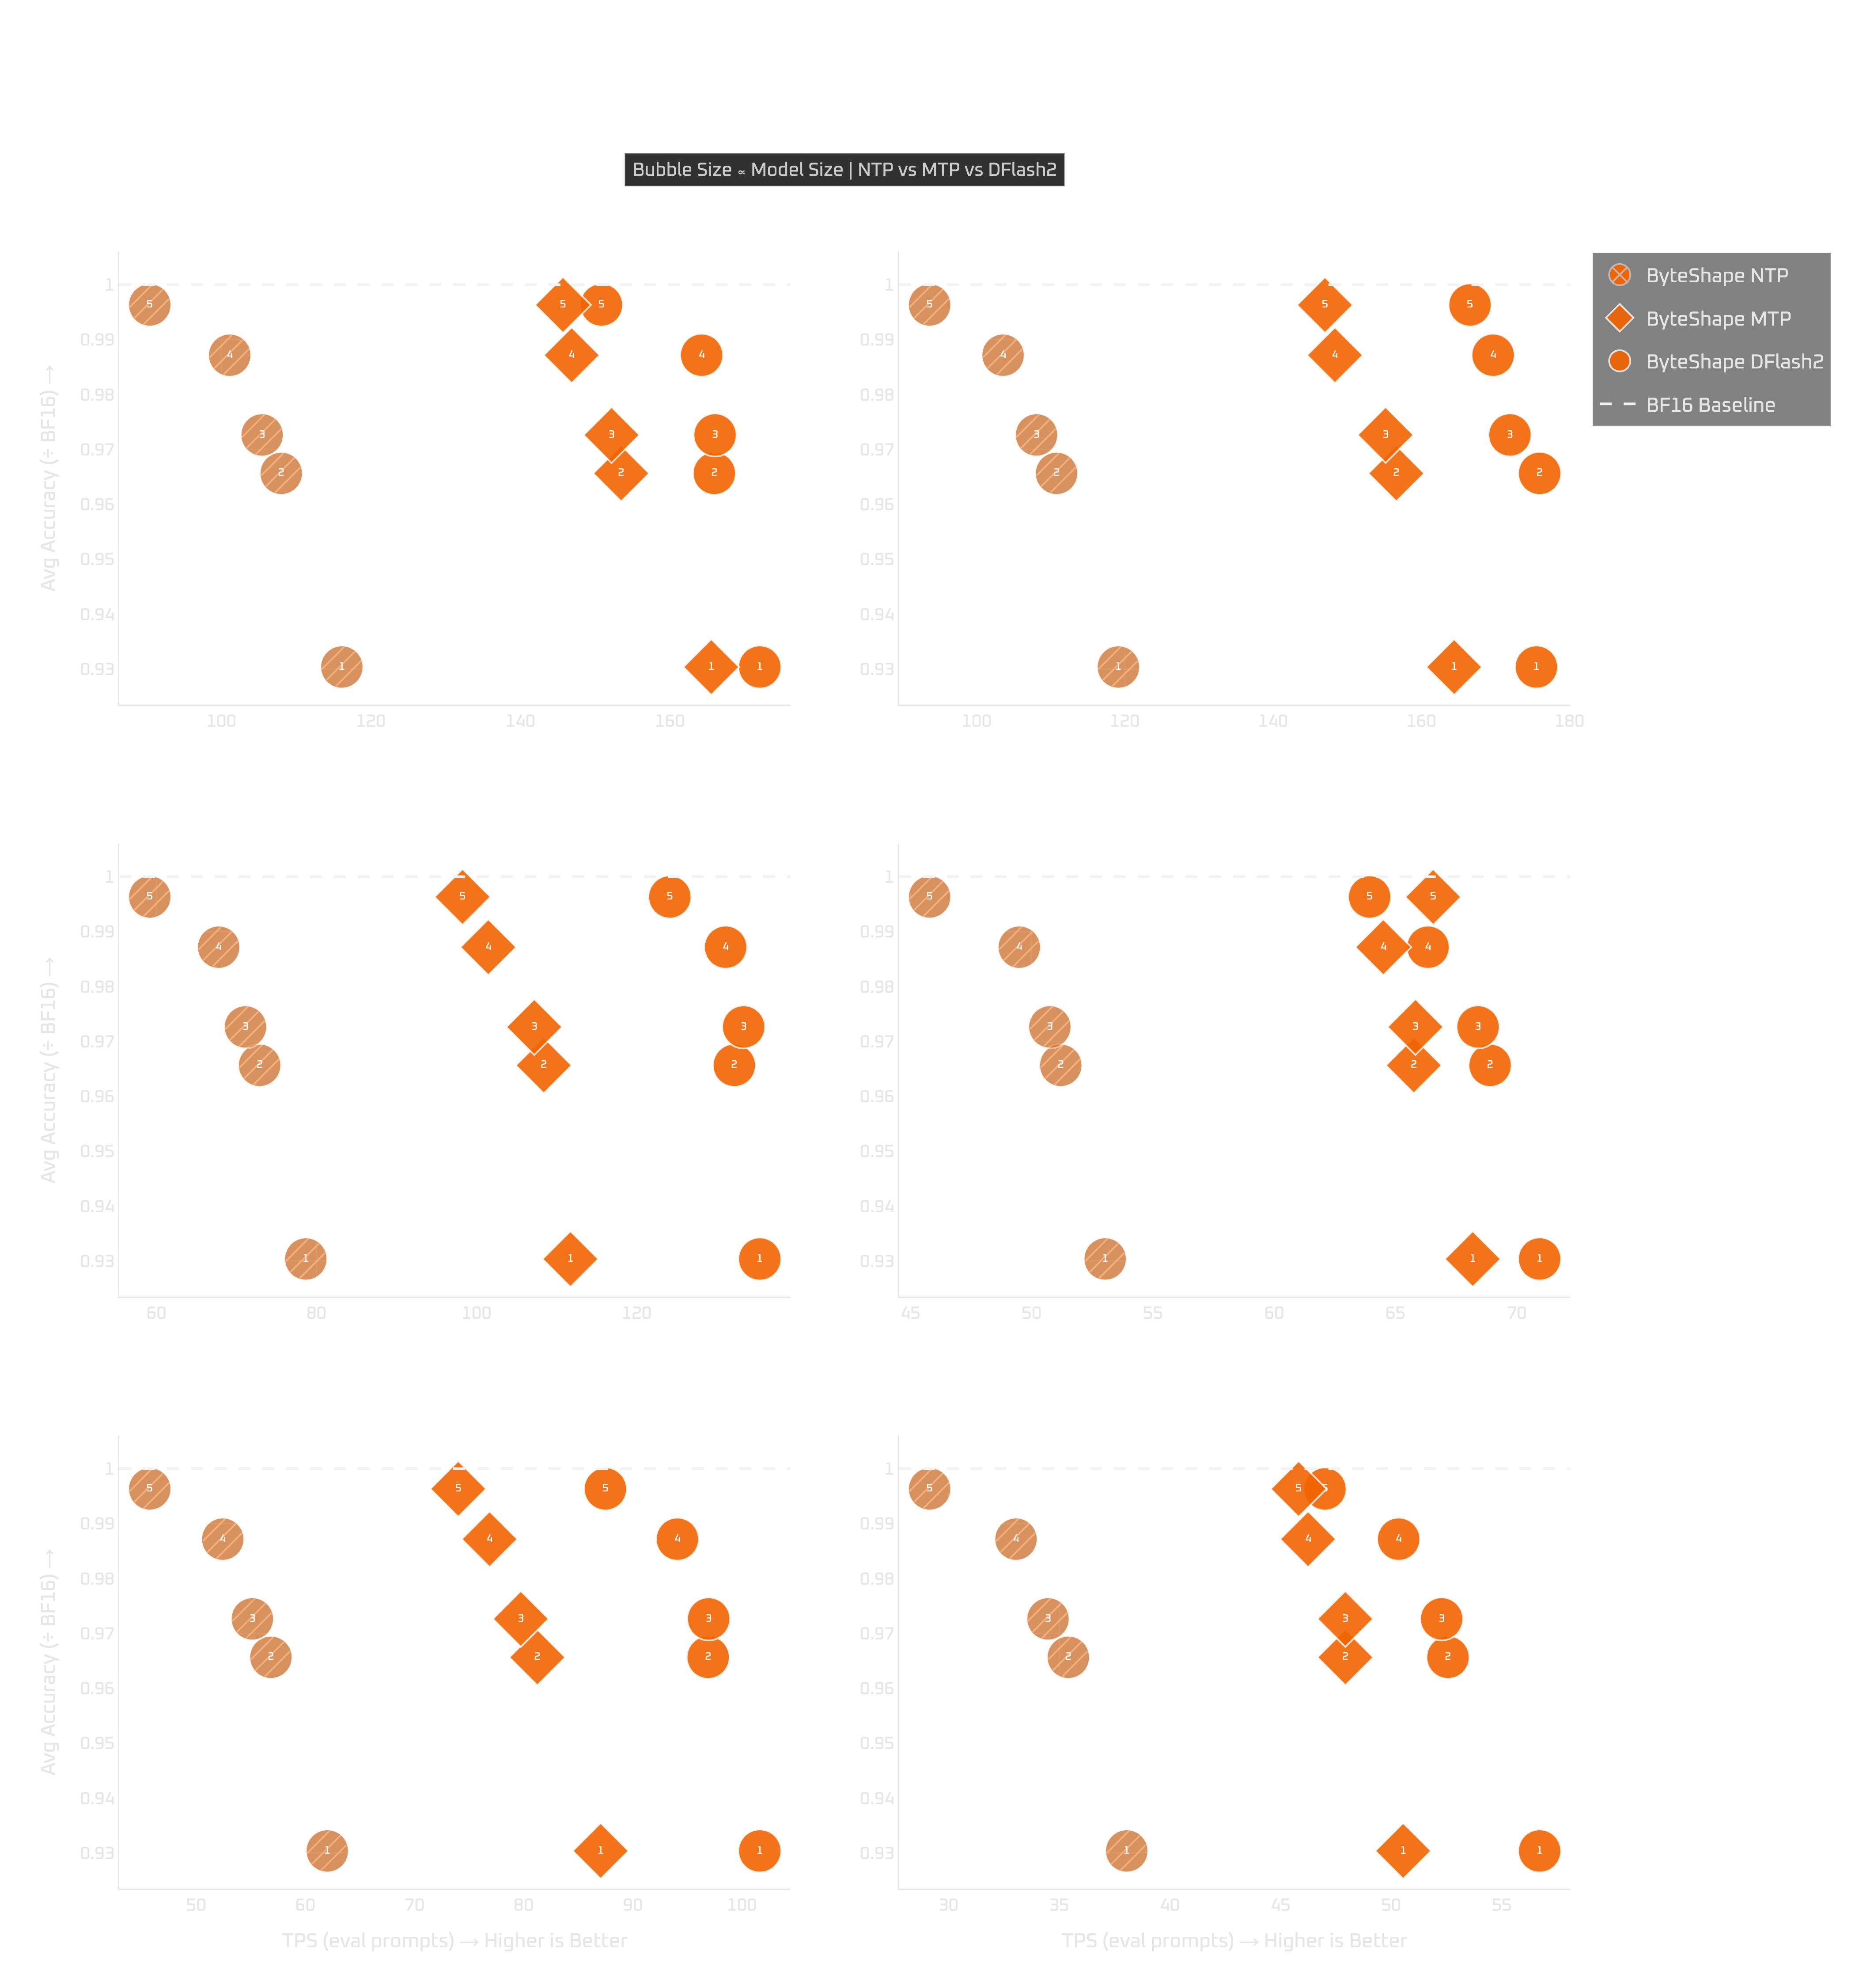
We were a little impatient. Qwen 3.8 27B was released on August 14, 2026. Four days later, on August 18, we published our first set of GGUFs. We called them ShapeLearn-Lite for a reason: they were produced using a much smaller optimization budget, fewer checks, and much less waiting. Now the full ShapeLearn models are done, and we have benchmarked them alongside the original Lite set and competing quants. The good news: ShapeLearn-Lite held up pretty well. We will come back to that later in “ShapeLearn-Lite, in retrospect” . The better news: the full ShapeLearn models are even better. Quick start with llama.cpp The MTP draft head is bundled in every GGUF. DFlash2 uses a separate 1.1 GB draft model. Both commands use GPU-5 . Swap the tag for any other model in the release. MTP Embedded draft. Works with image inputs. llama-server \ -hf byteshape/Qwen3.8-27B-GGUF:Qwen3.8-27B-IQ4_XS-3.84bpw \ --mmproj-auto \ --spec-type draft-mtp --spec-draft-n-max 3 DFlash2 External draft. Fastest option, text only.…