Menu

#Qwen

121 posts

Feed·
20 of 121 posts
GitHub - jaredpalmer/kev: tiny Jev-like family of decision models built on top of Qwen3.5 you can train and run on your own
🖼️
0

GitHub - jaredpalmer/kev: tiny Jev-like family of decision models built on top of Qwen3.5 you can train and run on your own

Hacker News·17 days ago
#lfUgZv2e

tiny Jev-like family of decision models built on top of Qwen3.5 you can train and run on your own - jaredpalmer/kev

15s
Read More
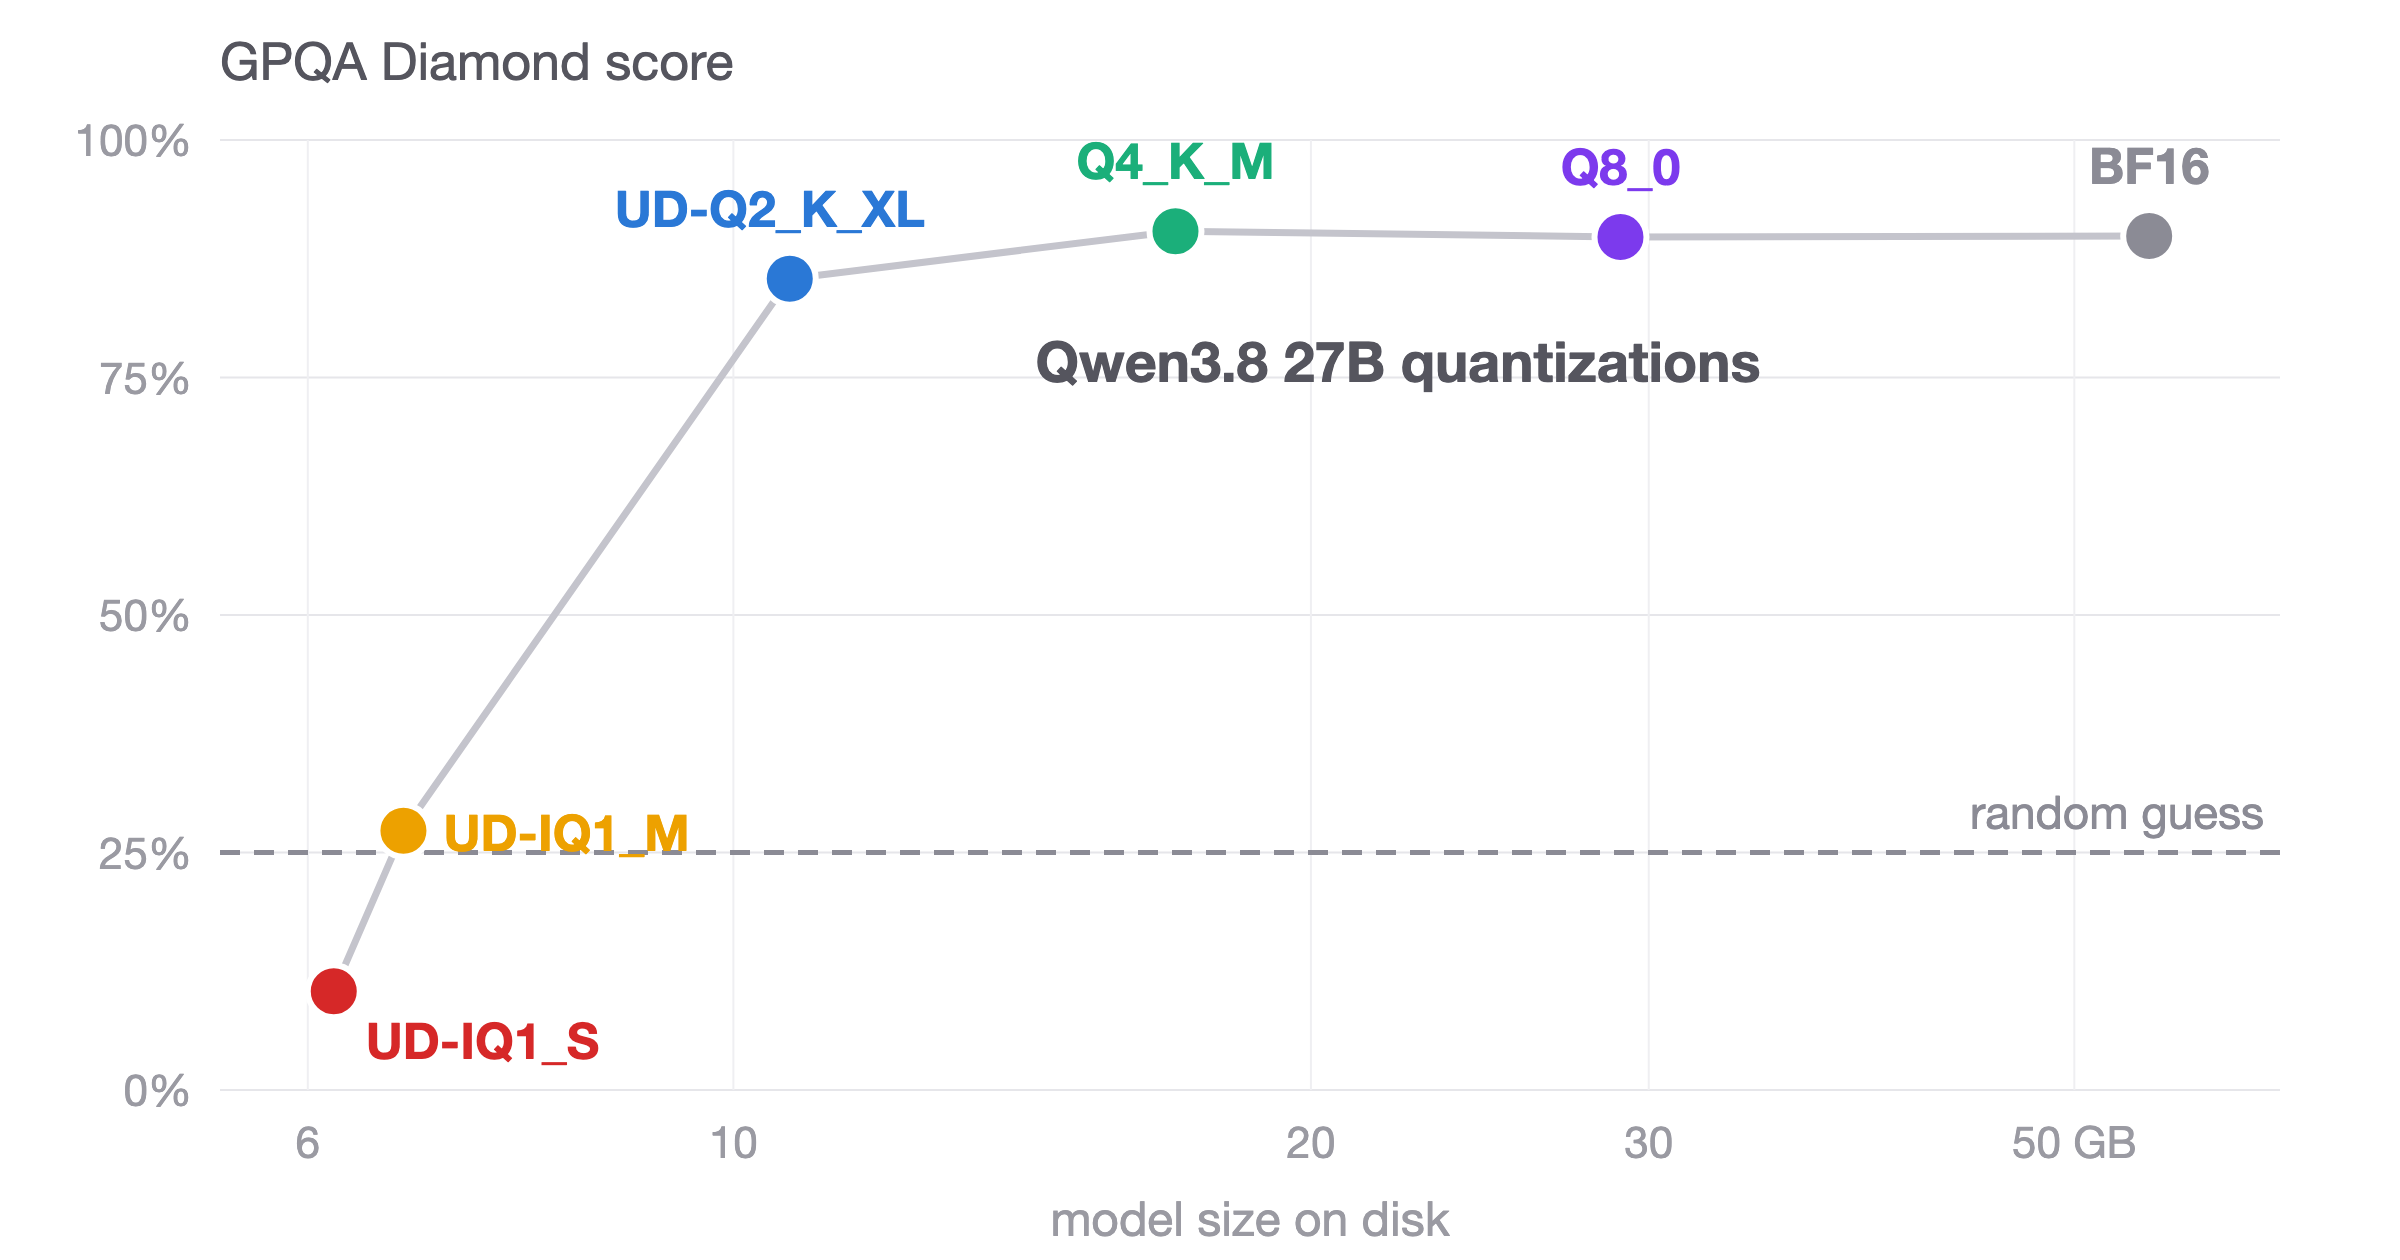
Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses
🖼️
0

Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses

Hacker News·30 days ago
#hwNfzXDZ

I test Unsloth GGUFs of Qwen3.8 27B (Q4_K_M, UD-Q2_K_XL, UD-IQ1_S) with llama.cpp on GPQA Diamond, IFBench, Terminal-Bench 2.1. Q4_K_M matches BF16 abd fits an RTX 4090.

15s
Read More
Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
🖼️
802

Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things

Hacker News·about 2 months ago
#DSU7ejnw

Friday’s big release was Qwen 3.8 27B, an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba’s Qwen research lab. I’ve been looking forward to this one: 27B is an …

15s
Read More
Qwen-AgentWorld: Language World Models for General Agents
🖼️
198

Qwen-AgentWorld: Language World Models for General Agents

Hacker News·4 months ago
#GiQCcLUt

A world model predicts environment dynamics based on current observations and actions, serving as a core cognitive mechanism for reasoning and planning.…

15s
Read More
Ask HN: Has anyone replaced Claude/GPT with a local model for daily coding?
📰
0

Ask HN: Has anyone replaced Claude/GPT with a local model for daily coding?

Hacker News·4 months ago
#sCYBSa0J
#news#models#opus#model#local#qwen

I have! I care about data privacy and LLMs being free. I'm using the Pi coding harness but containerized and sandboxed, to make sure it's running completely offline.…

15s
Read More
Rio-3.5-Open-397B ≈ 0.6 x Nex-N2_pro + 0.4 x Qwen
📰
0

Rio-3.5-Open-397B ≈ 0.6 x Nex-N2_pro + 0.4 x Qwen

Hacker News·4 months ago
#zORVlvm2
#github#model#qwen#evidence#time#photo

prefeitura-rio/Rio-3.5-Open-397B is presented as an original 397B model trained by IplanRIO. It is not. Its weights are a direct element-wise merge of our model, Nex, with the official Qwen3.5-397B...

15s
Read More
How to Migrate from OpenAI to Asiatek AI in 5 Minutes
🖼️
0

How to Migrate from OpenAI to Asiatek AI in 5 Minutes

DEV Community: tutorial·q409605362·4 months ago
#FvYs64HT
#dev#qwen#openai#plus#southeast#code

Learn how to seamlessly migrate your OpenAI API calls to Asiatek AI with zero code changes. Singapore data centers, Qwen from $0.08/M tokens, DeepSeek with 128K context.

15s
Read More
Gemma 4 12B: Encoder-Free Coding on a 16GB Laptop
🖼️
0

Gemma 4 12B: Encoder-Free Coding on a 16GB Laptop

DEV Community: machinelearning·Max Quimby·4 months ago
#WyrUXDAL
#dev#model#coding#gemma#encoder#qwen

Google's Gemma 4 12B ditches vision encoders, scores 72% on LiveCodeBench, and runs on 16GB. Here's why researchers are swapping Qwen for it.

15s
Read More
On-device LLM on iPhone: which runtime is fastest? MLX vs llama.cpp vs LiteRT-LM vs CoreML
🖼️
0

On-device LLM on iPhone: which runtime is fastest? MLX vs llama.cpp vs LiteRT-LM vs CoreML

DEV Community: machinelearning·Daisuke Majima·4 months ago
#sbJ7uuTv
#dev#litert#coreml#gemma#memory#qwen

I want to run an LLM on iPhone. But there are several runtimes and it's not obvious which to...

15s
Read More