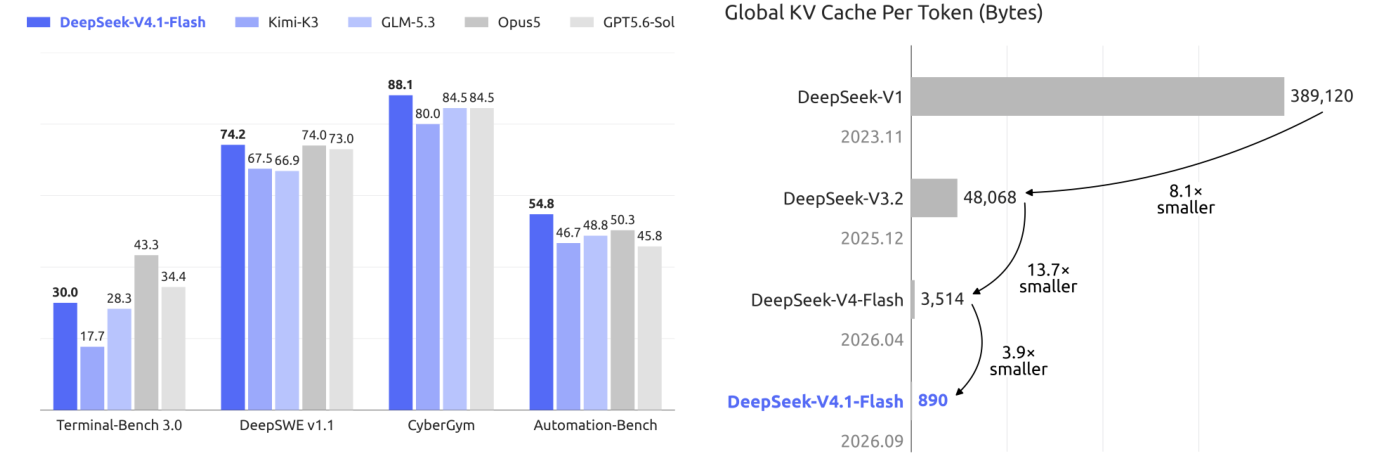
A deep dive into the DeepSeek-V4.1 Flash technical report: CED, CSA2, HSI, Single-Pass mHC, Engram and FP4 KV Cache — how the KV cache was compressed to just 890 bytes per token.
As large language model (LLM) inference workloads grow in complexity, a single monolithic serving process starts to hit its limits. Prefill and decode stages…
We built a custom technology stack to run fast large language models on Cloudflare’s infrastructure. This post explores the engineering trade-offs and technical optimizations required to make high-performance AI inference accessible.