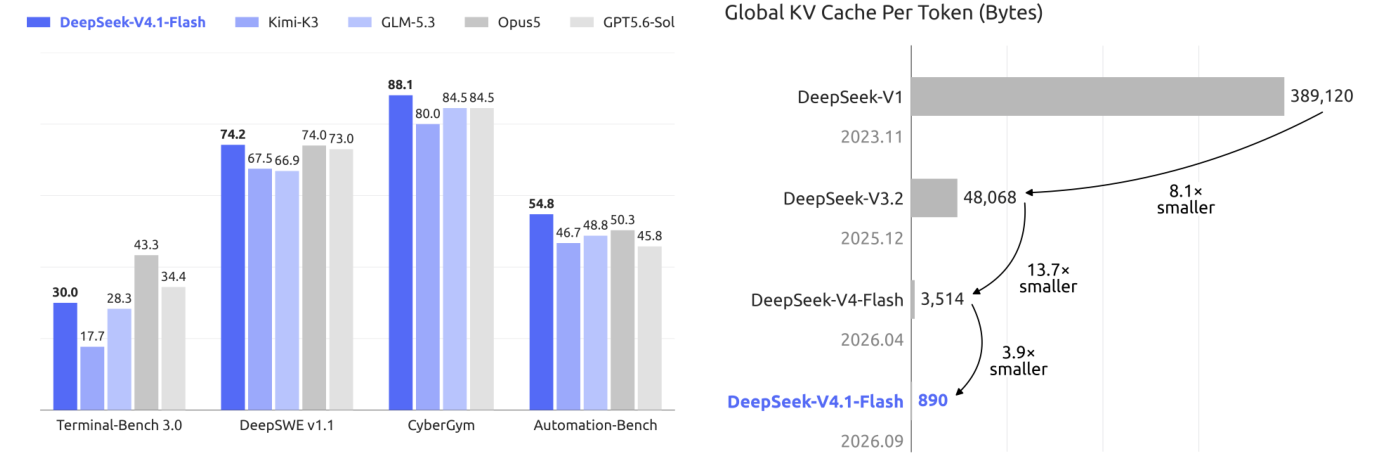
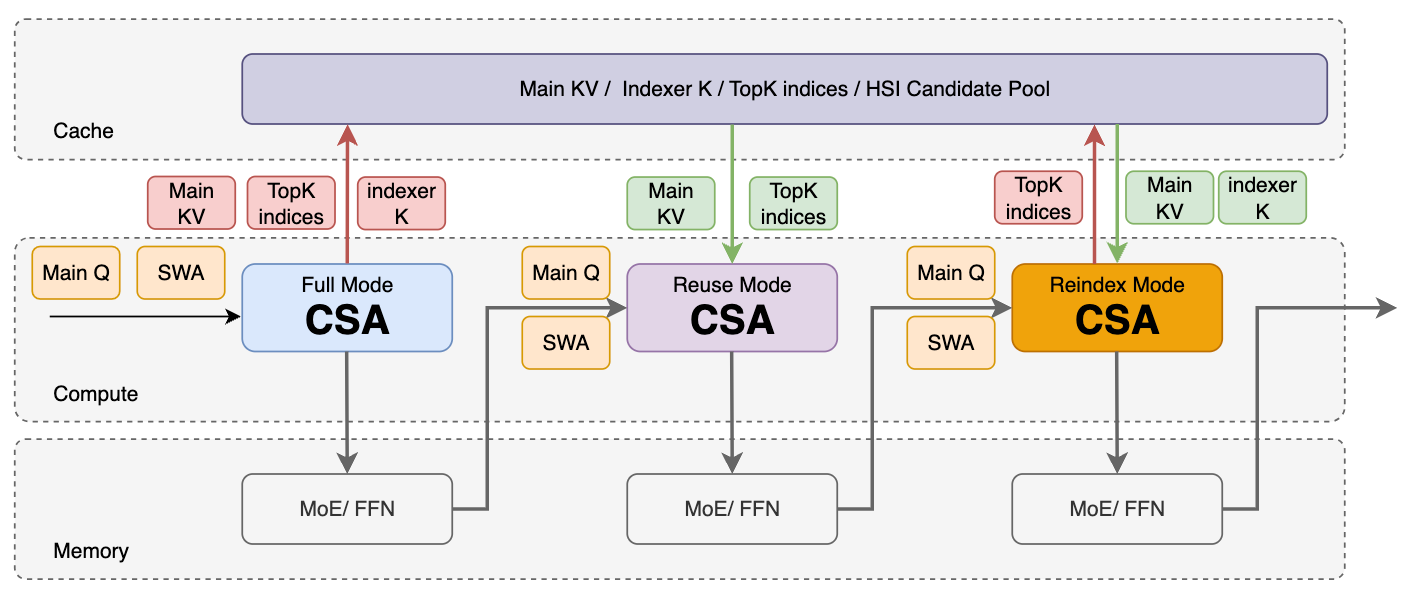
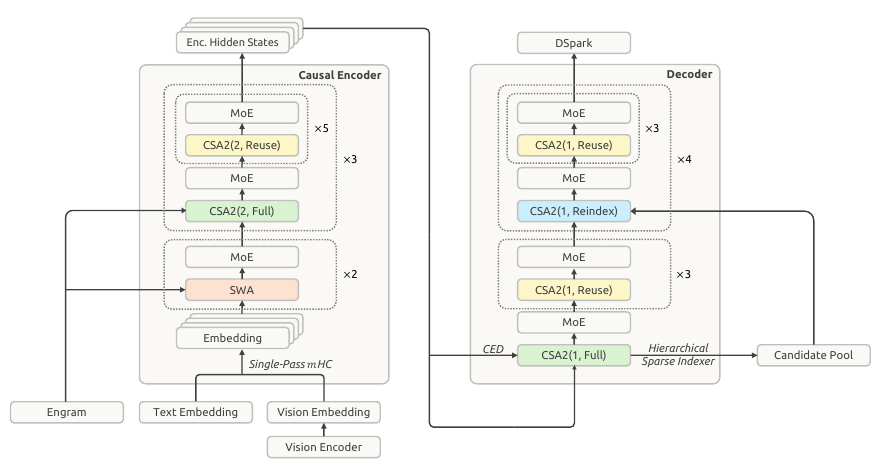
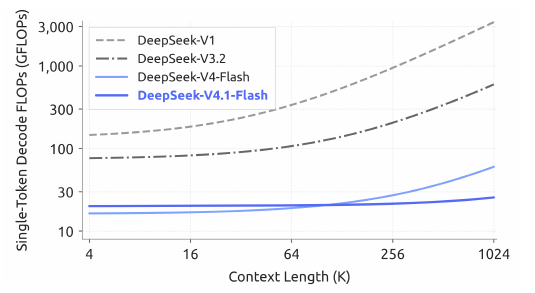
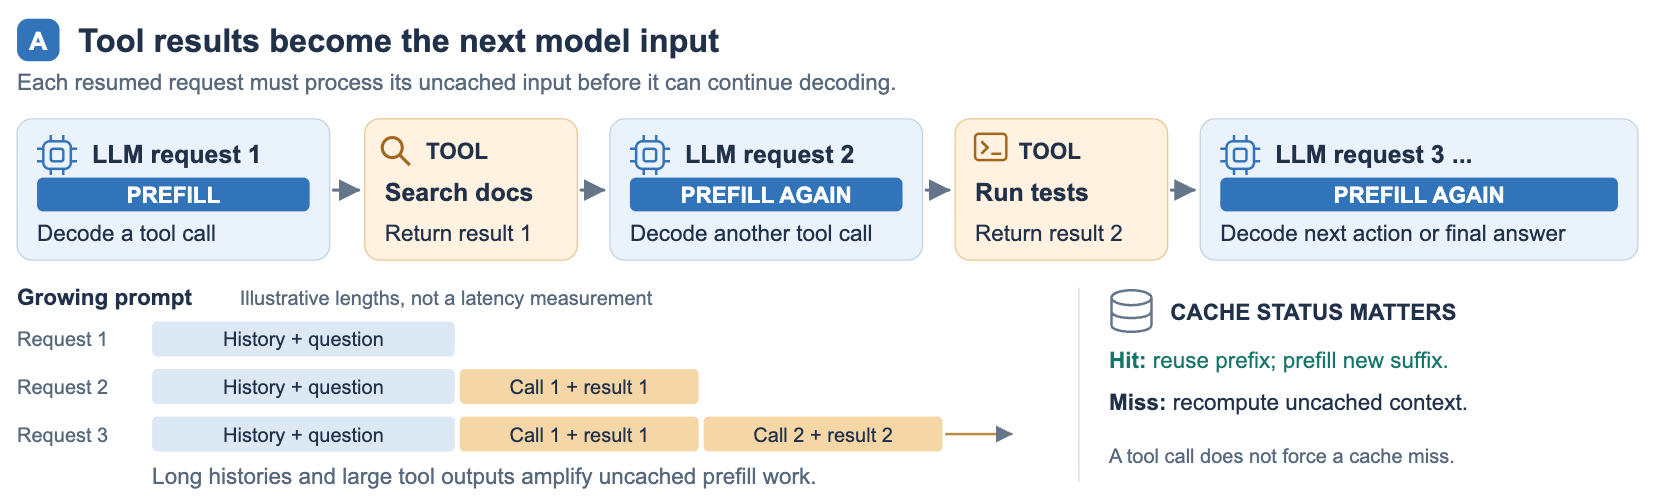
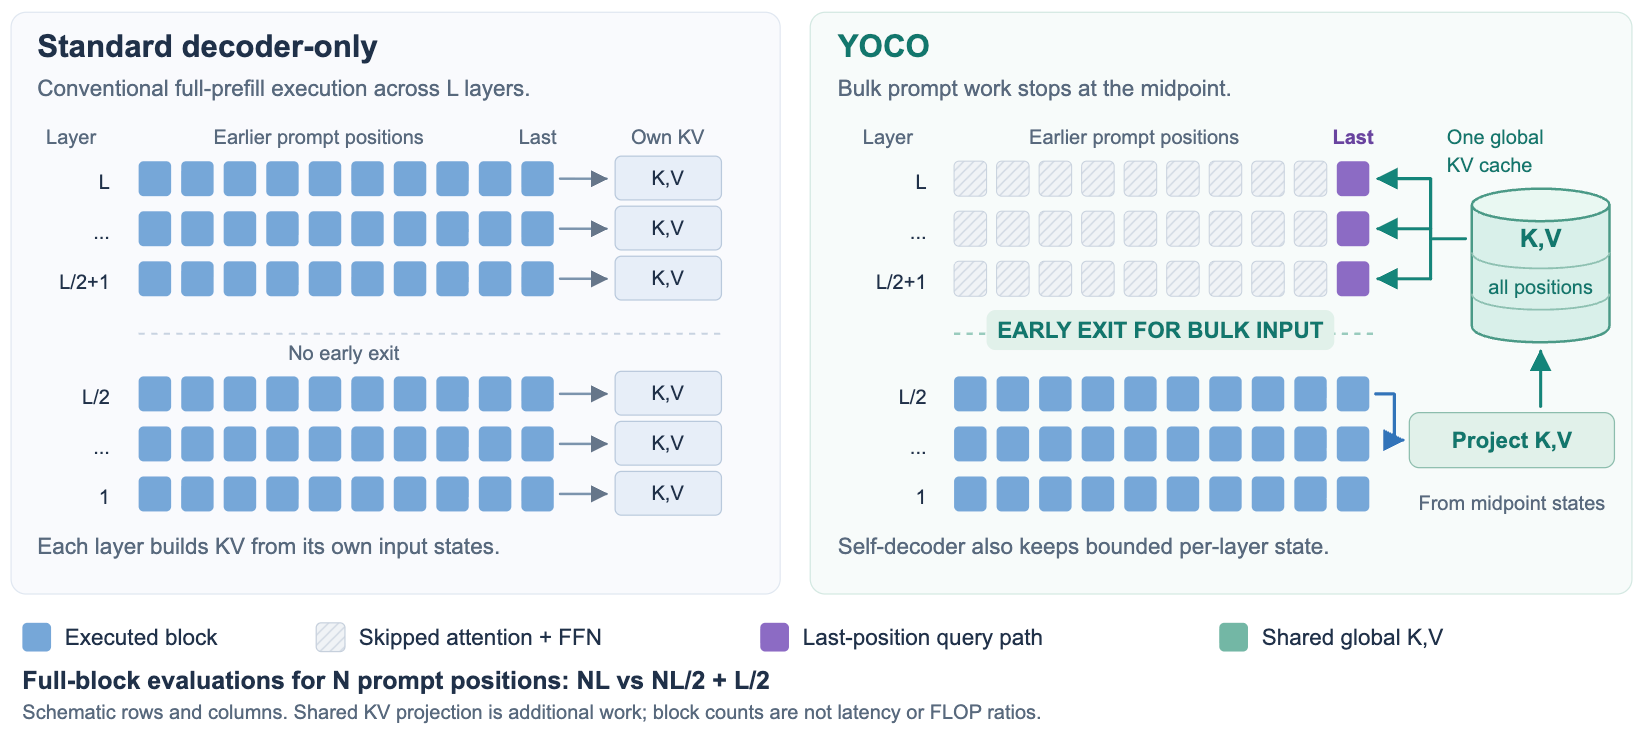
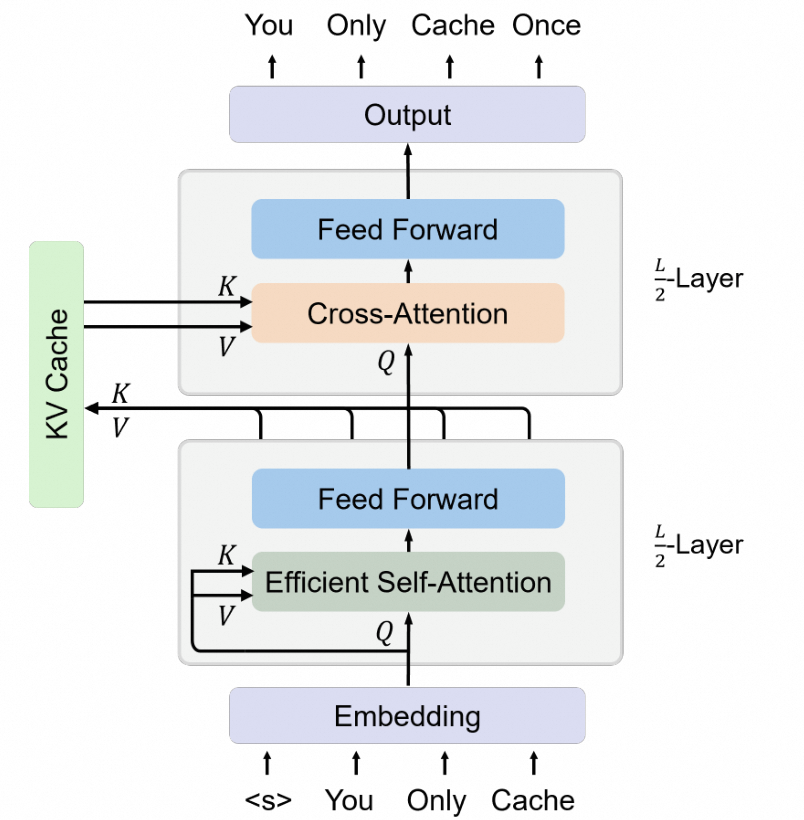
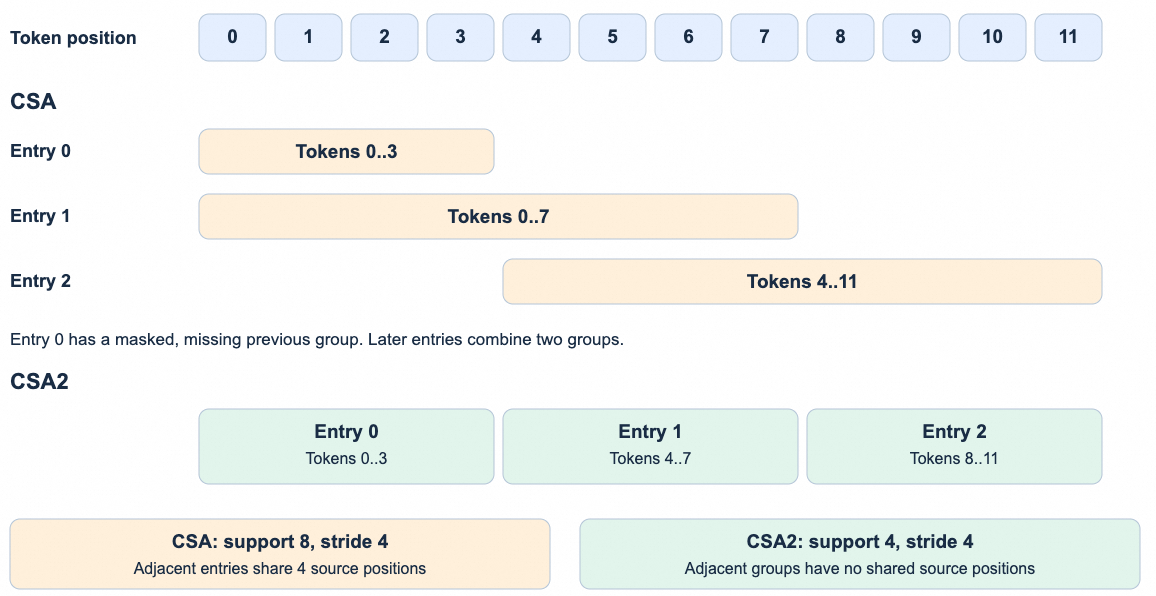
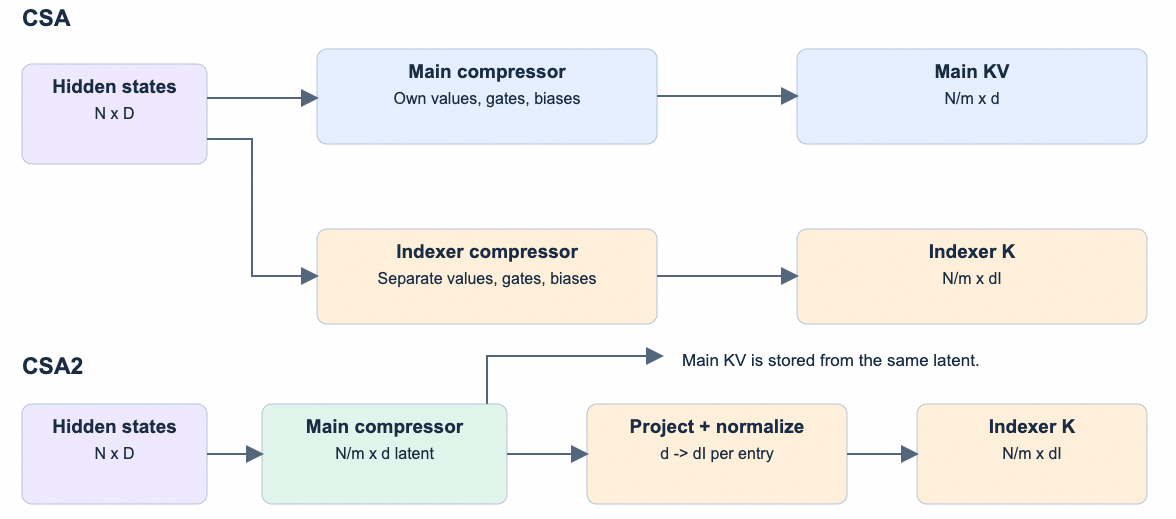
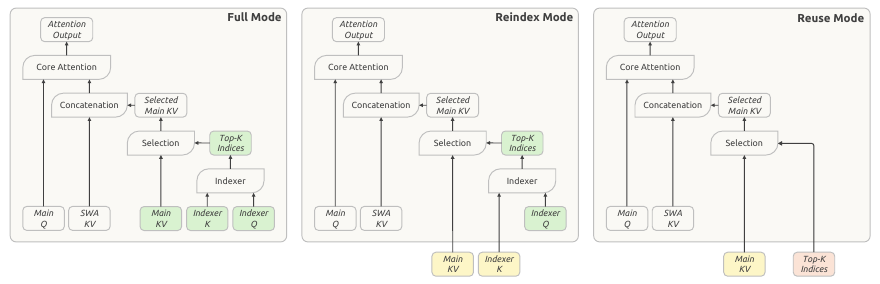
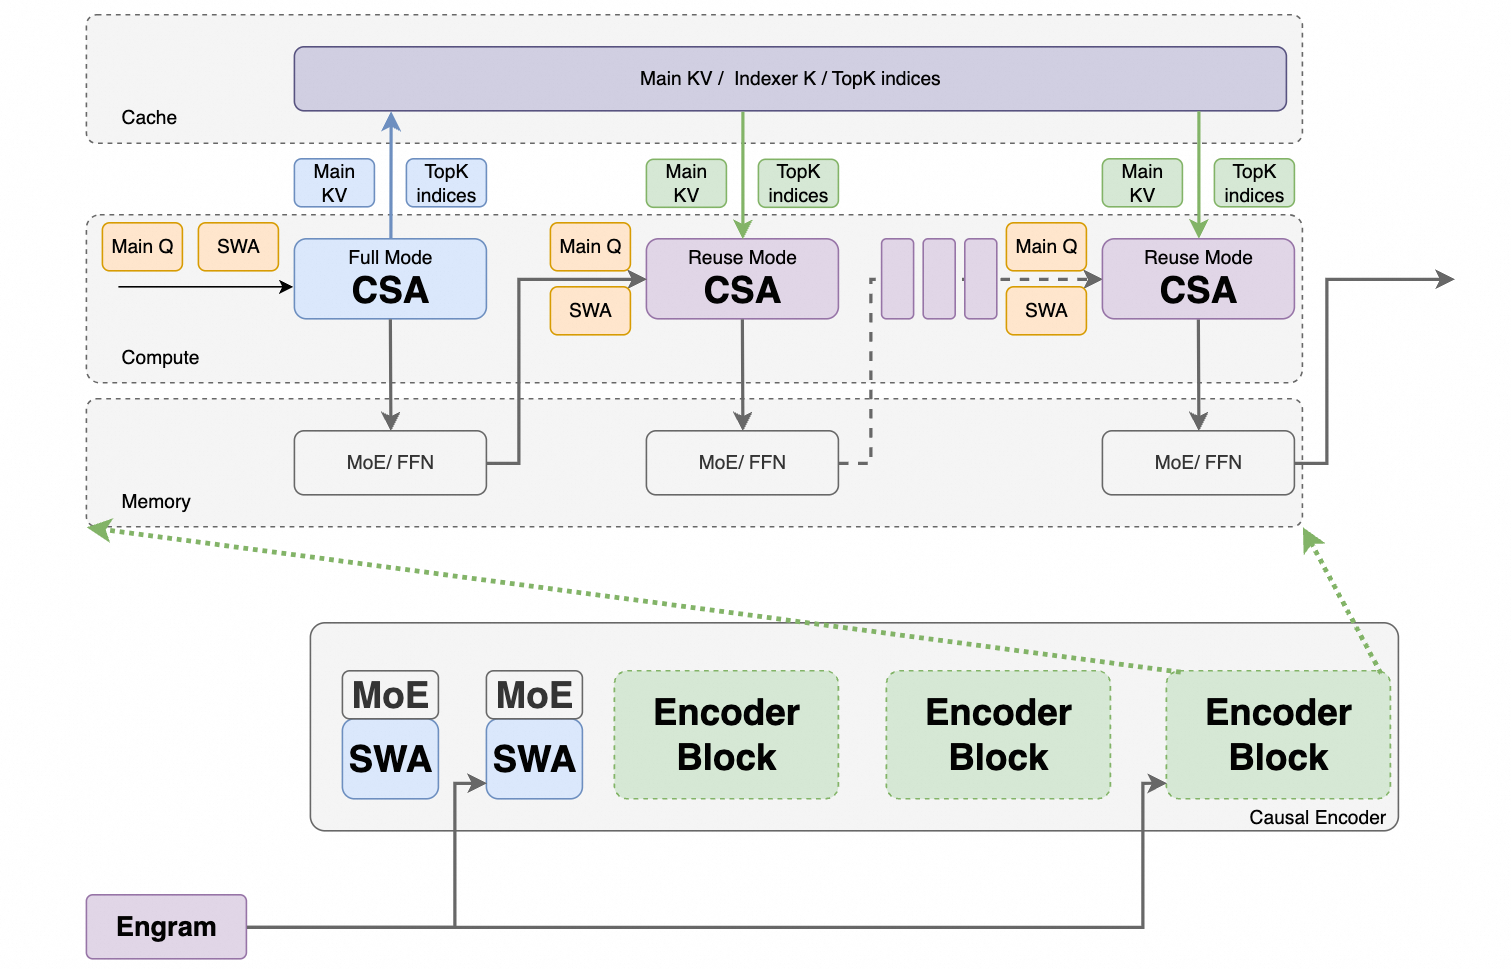
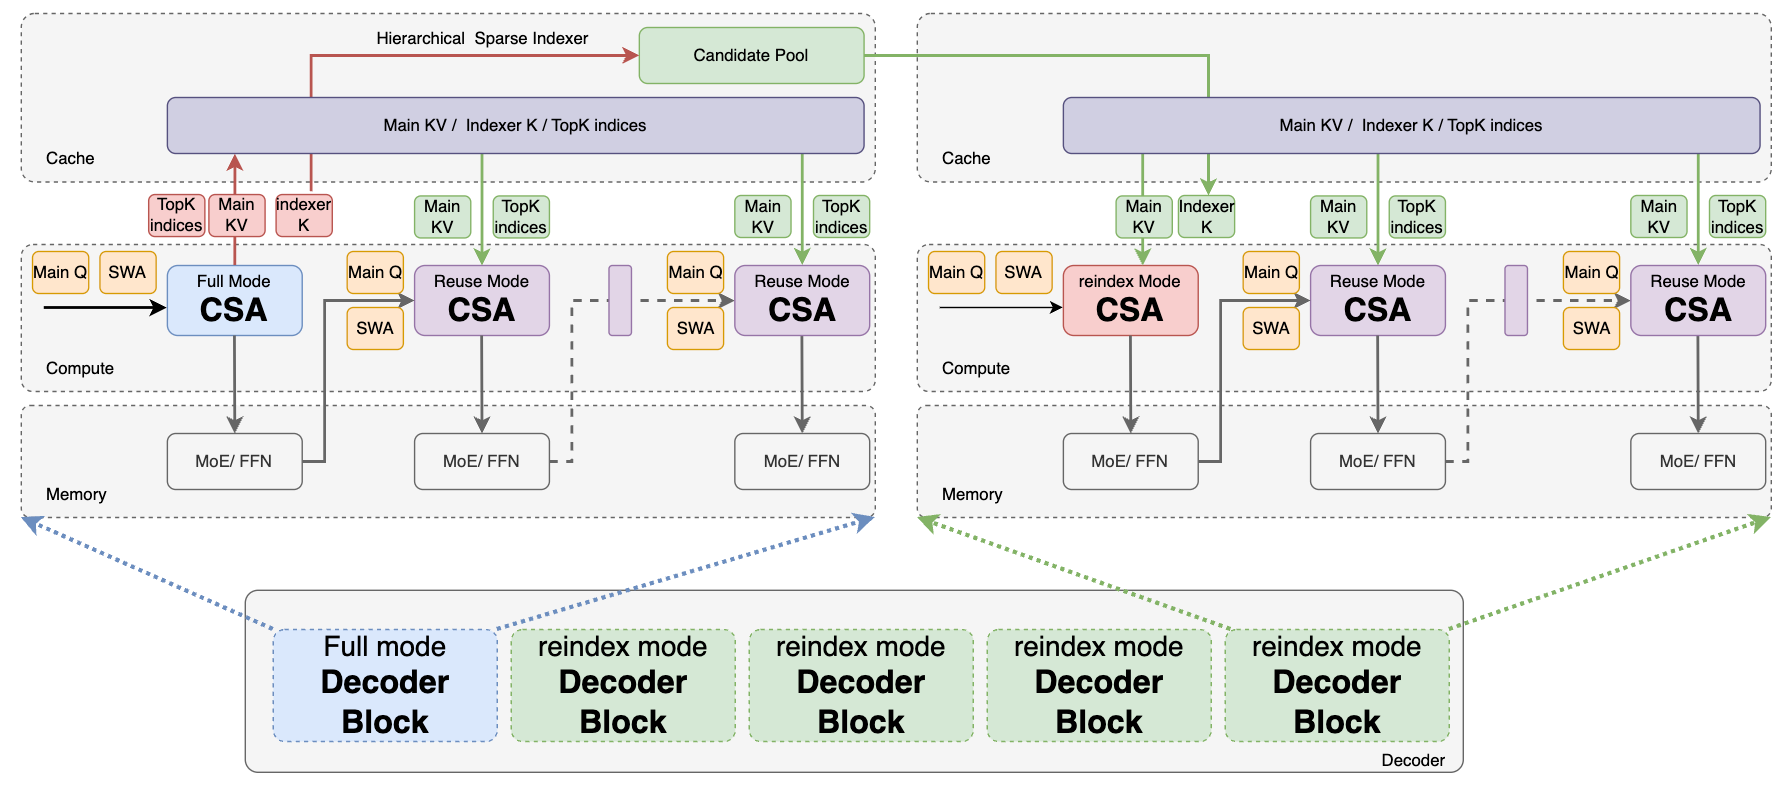
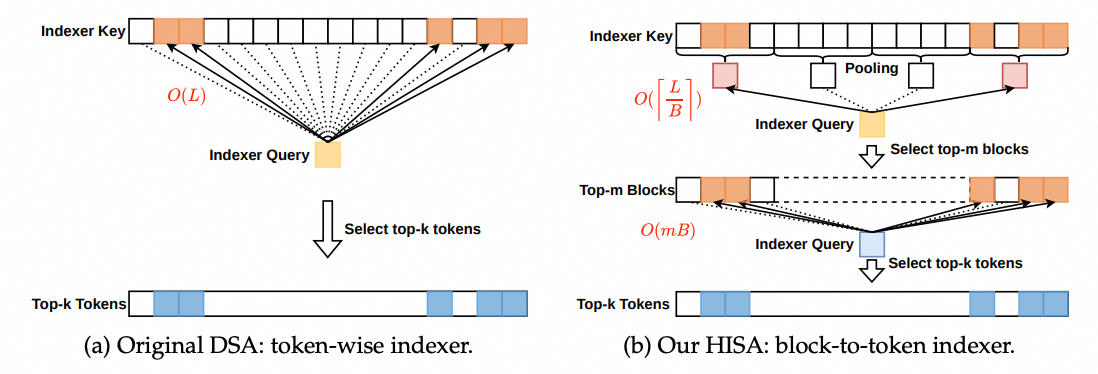
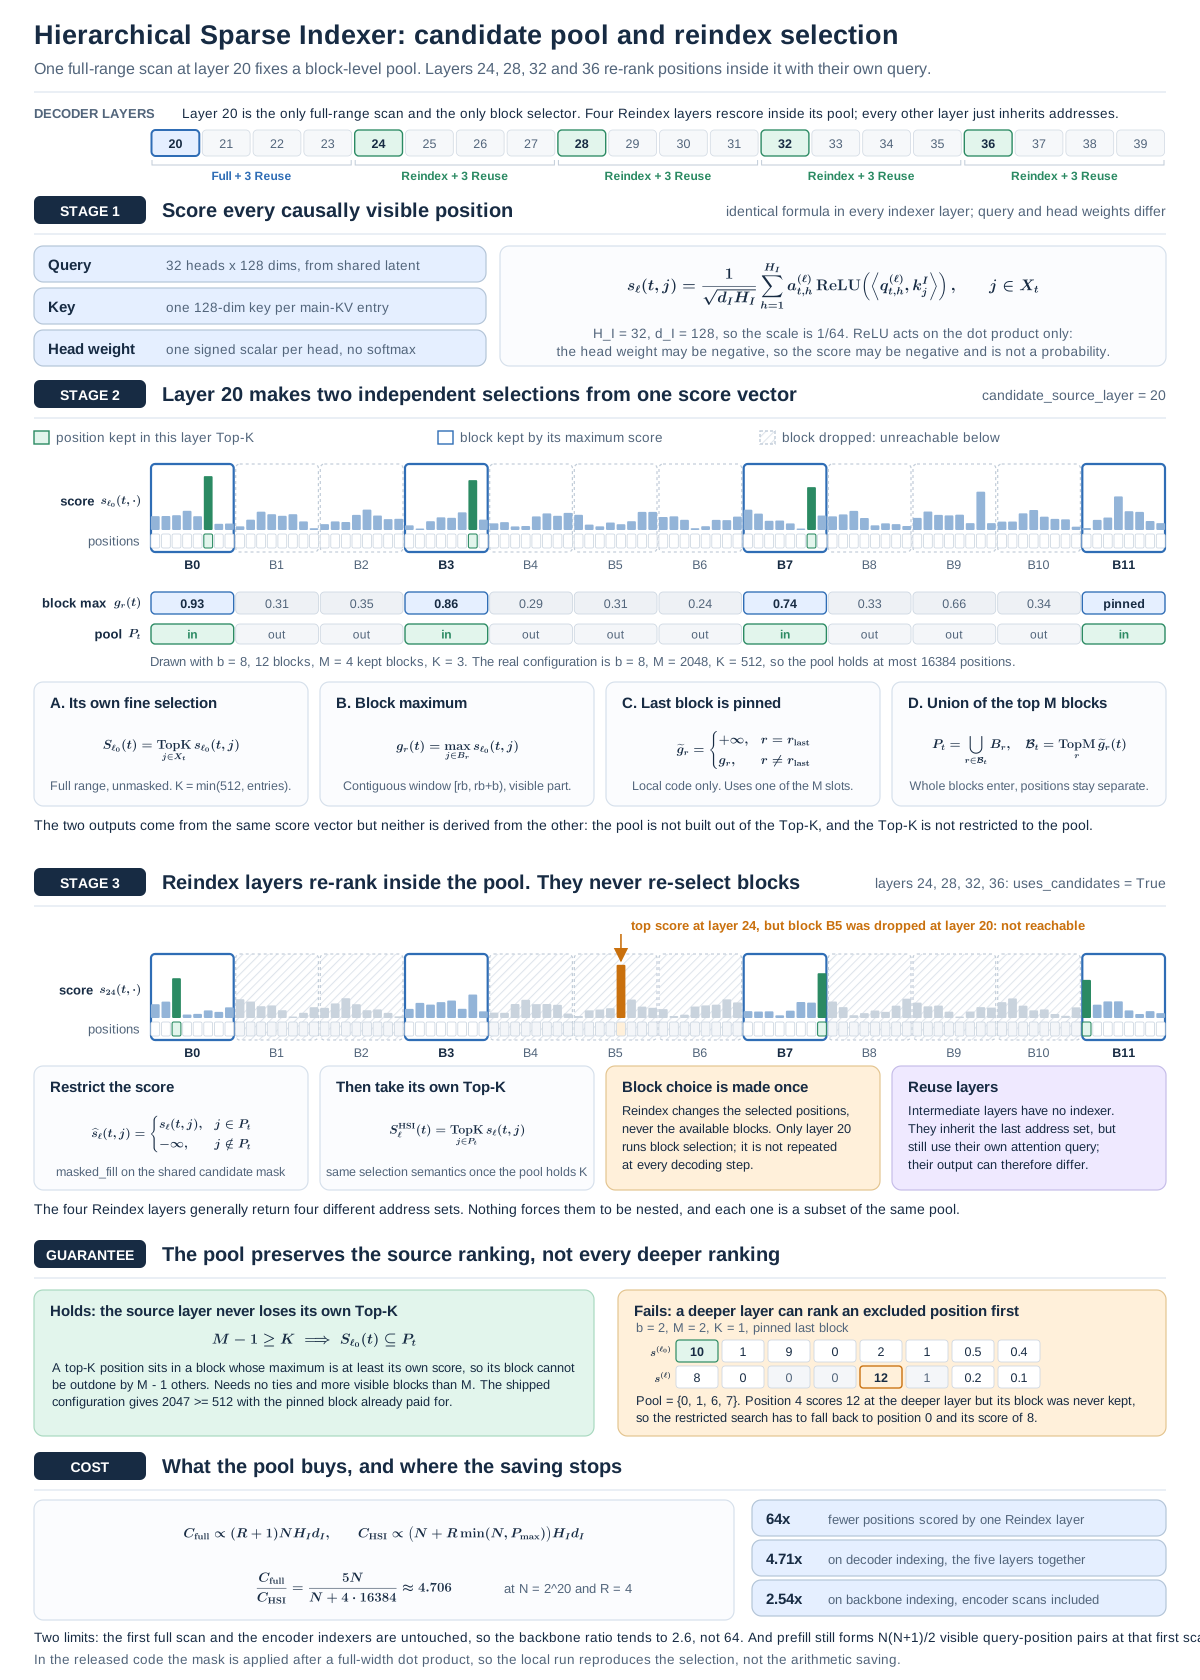
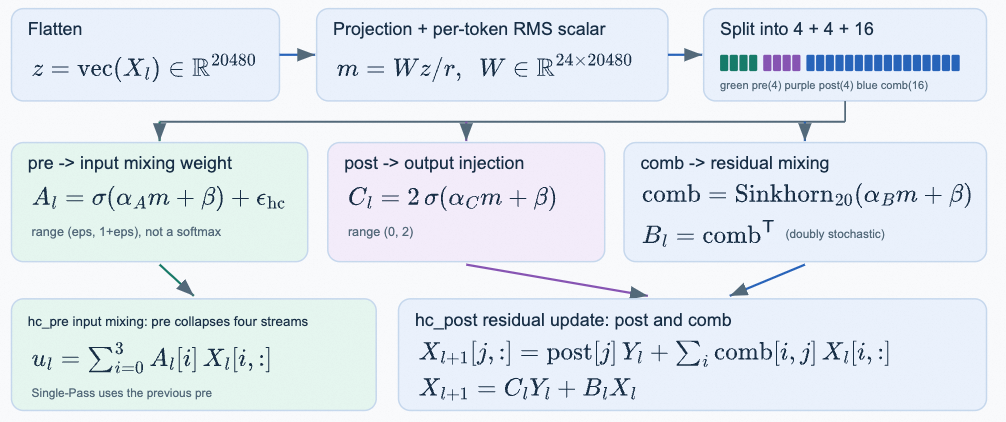
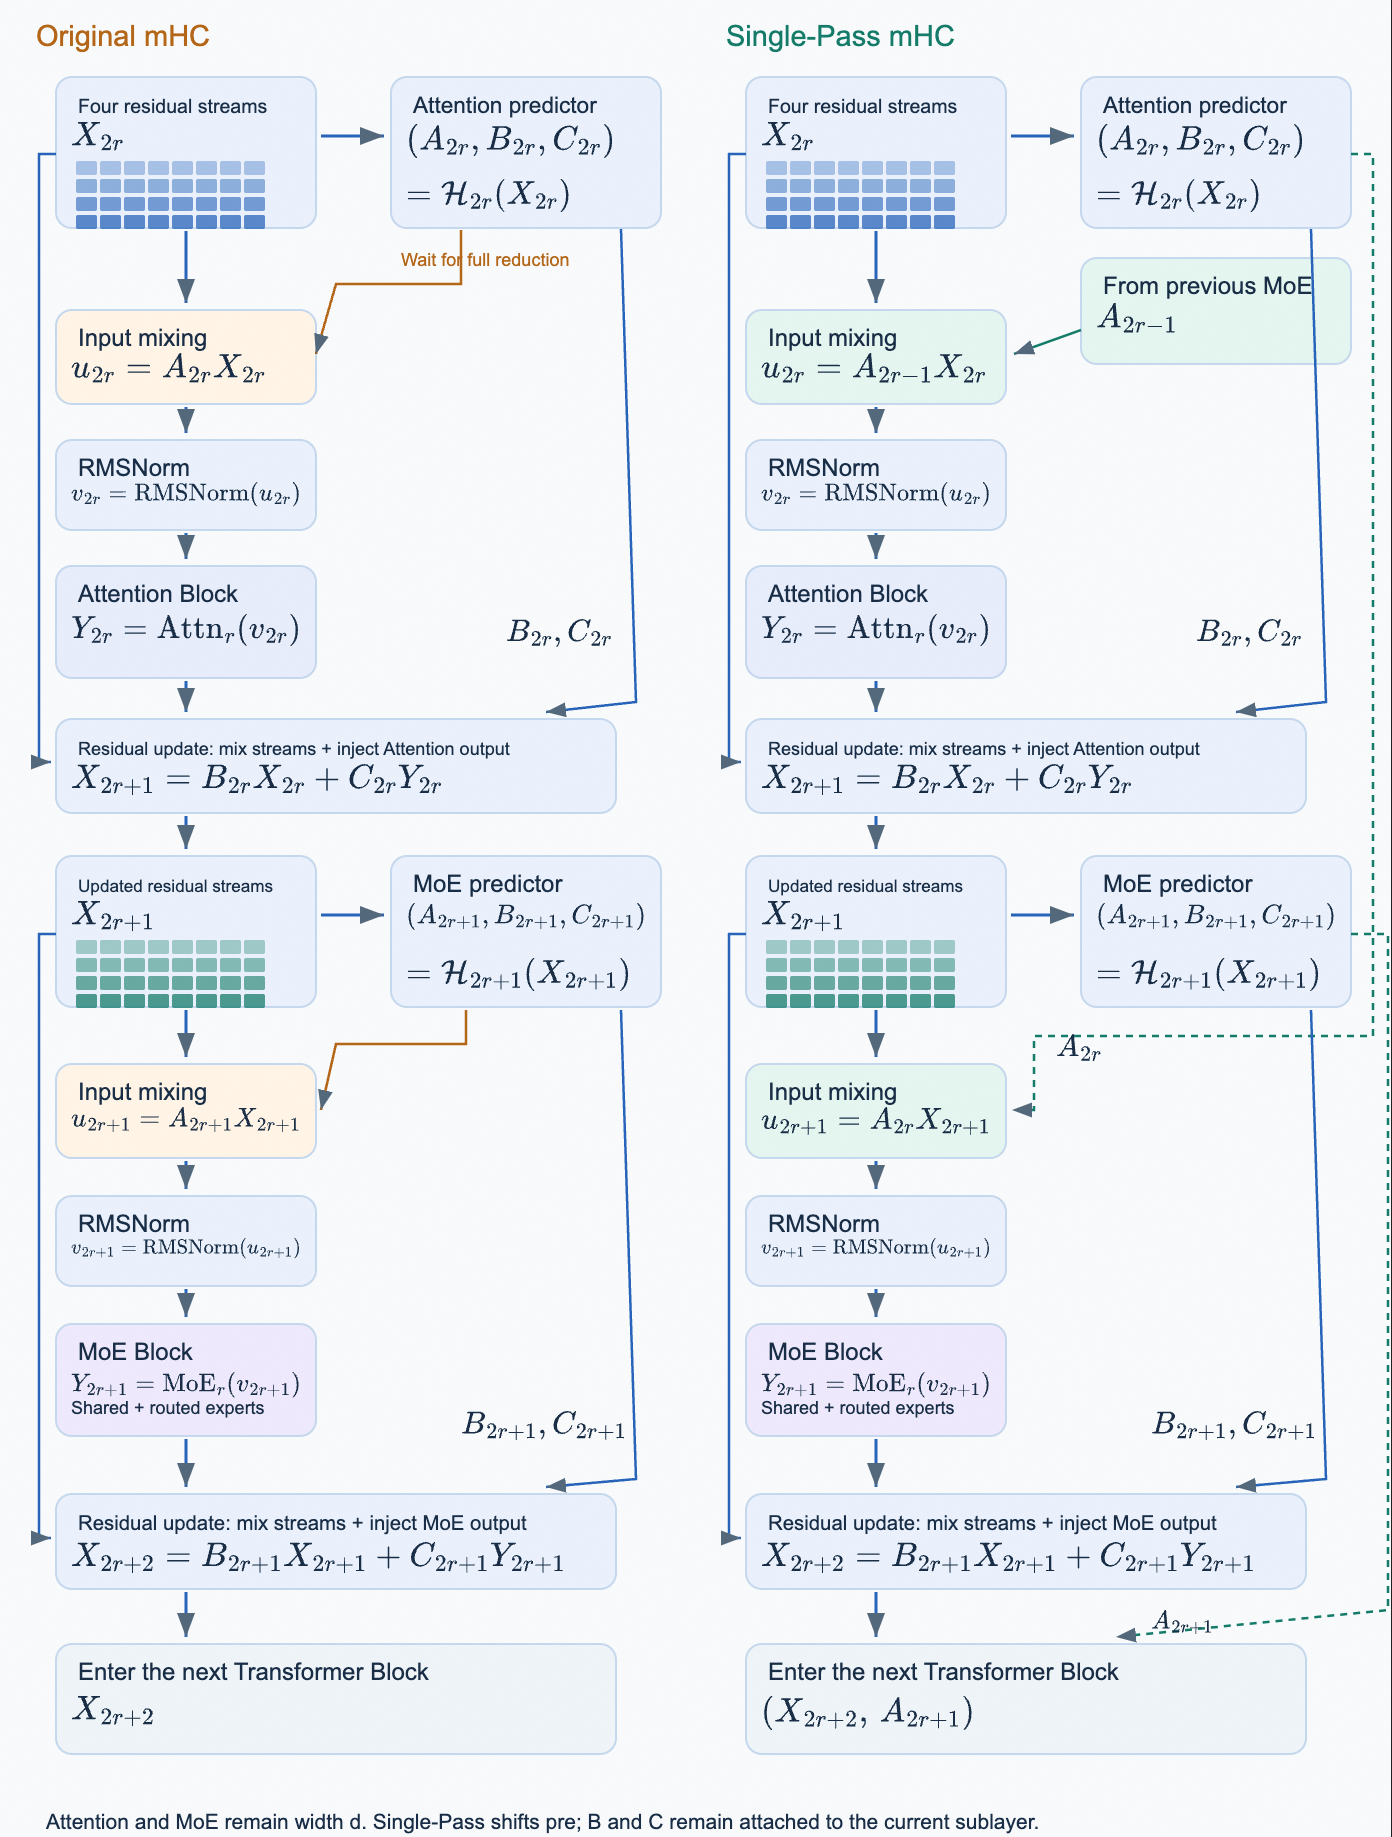
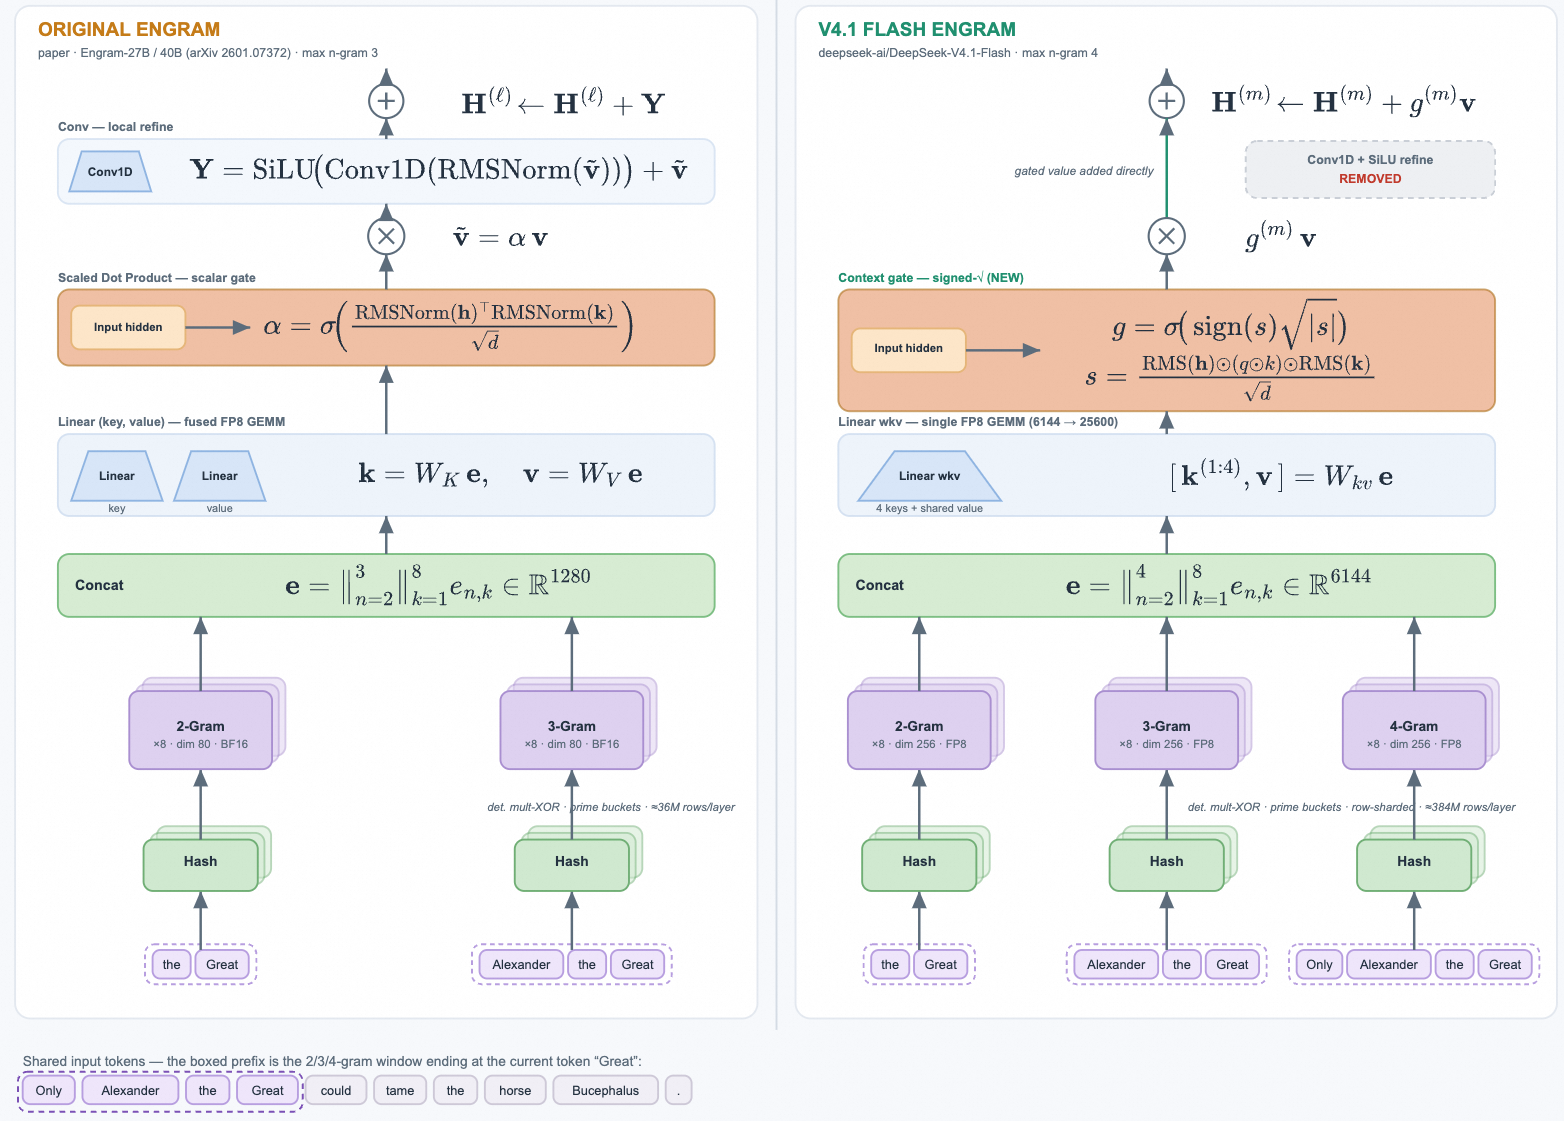
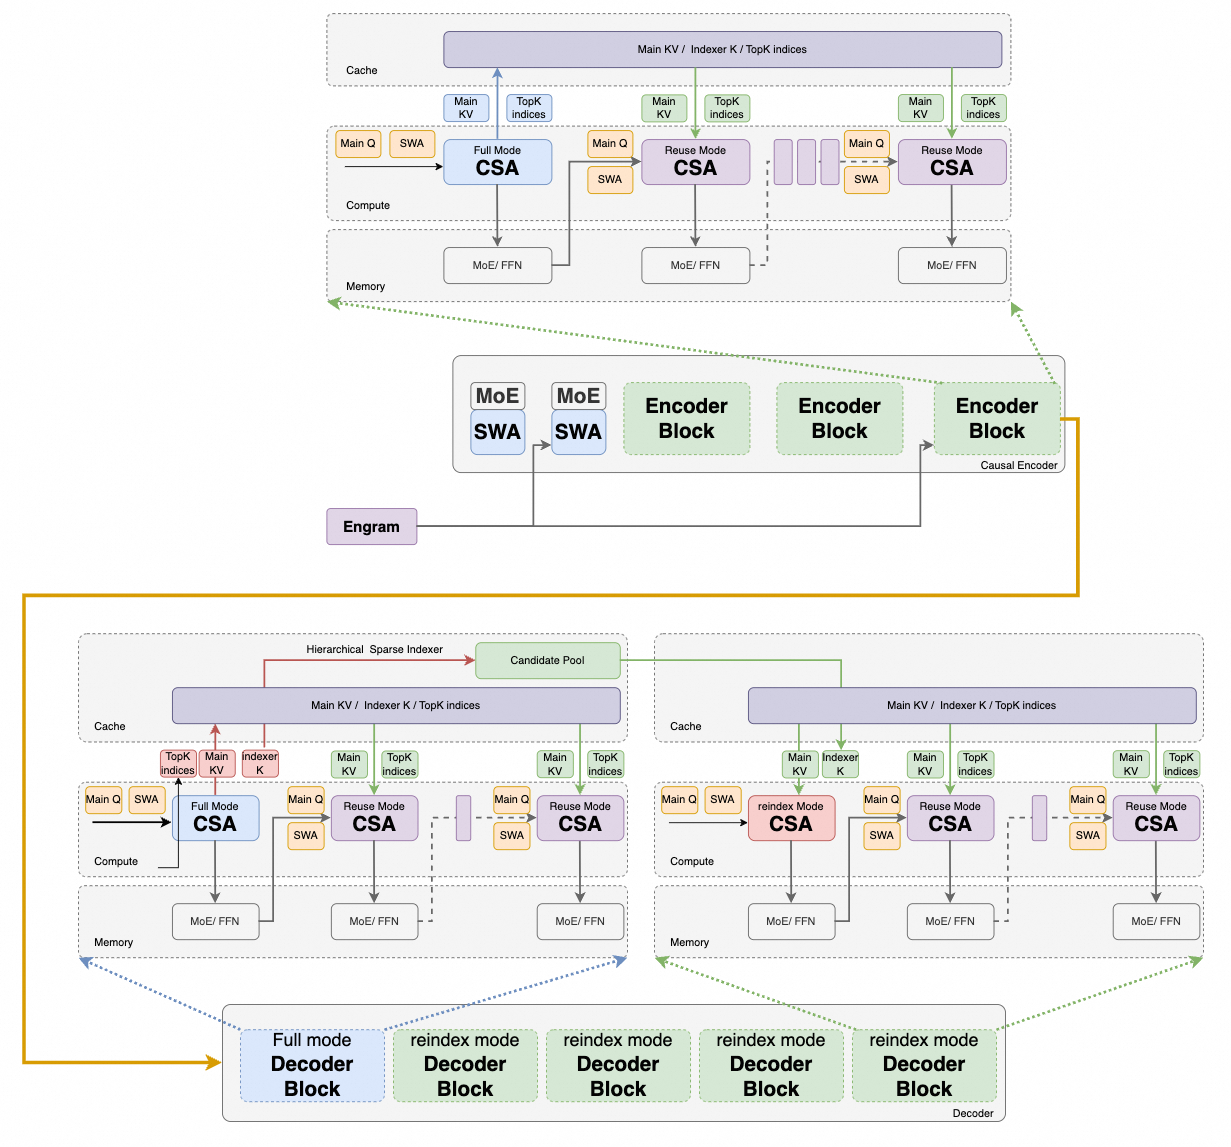
TL;DR When DeepSeek-V4.1 Flash was released, I thought it might just be a post-training iteration version... but after using it for a while, I found it reached nearly 420 Tokens/s in speed, and then Cui said all DeepSeek-V4 Pro models would be taken offline... suddenly I felt this was no small matter... until the Technical Report 《DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression》 [1] was fully released, only then did I realize it should be called DeepSeek-V5 Flash... As the paper title states, the purpose of DeepSeek-V4.1 Flash is to push KVCache compression to the extreme. The main reason is that Long-horizon Agent Workflows cause the Context to grow longer and longer, while various tool calls bring heavy prefill computation pressure. The storage pressure of KVCache in HBM and external SSD is very high, all of which are reasons that make Scaling impossible.…