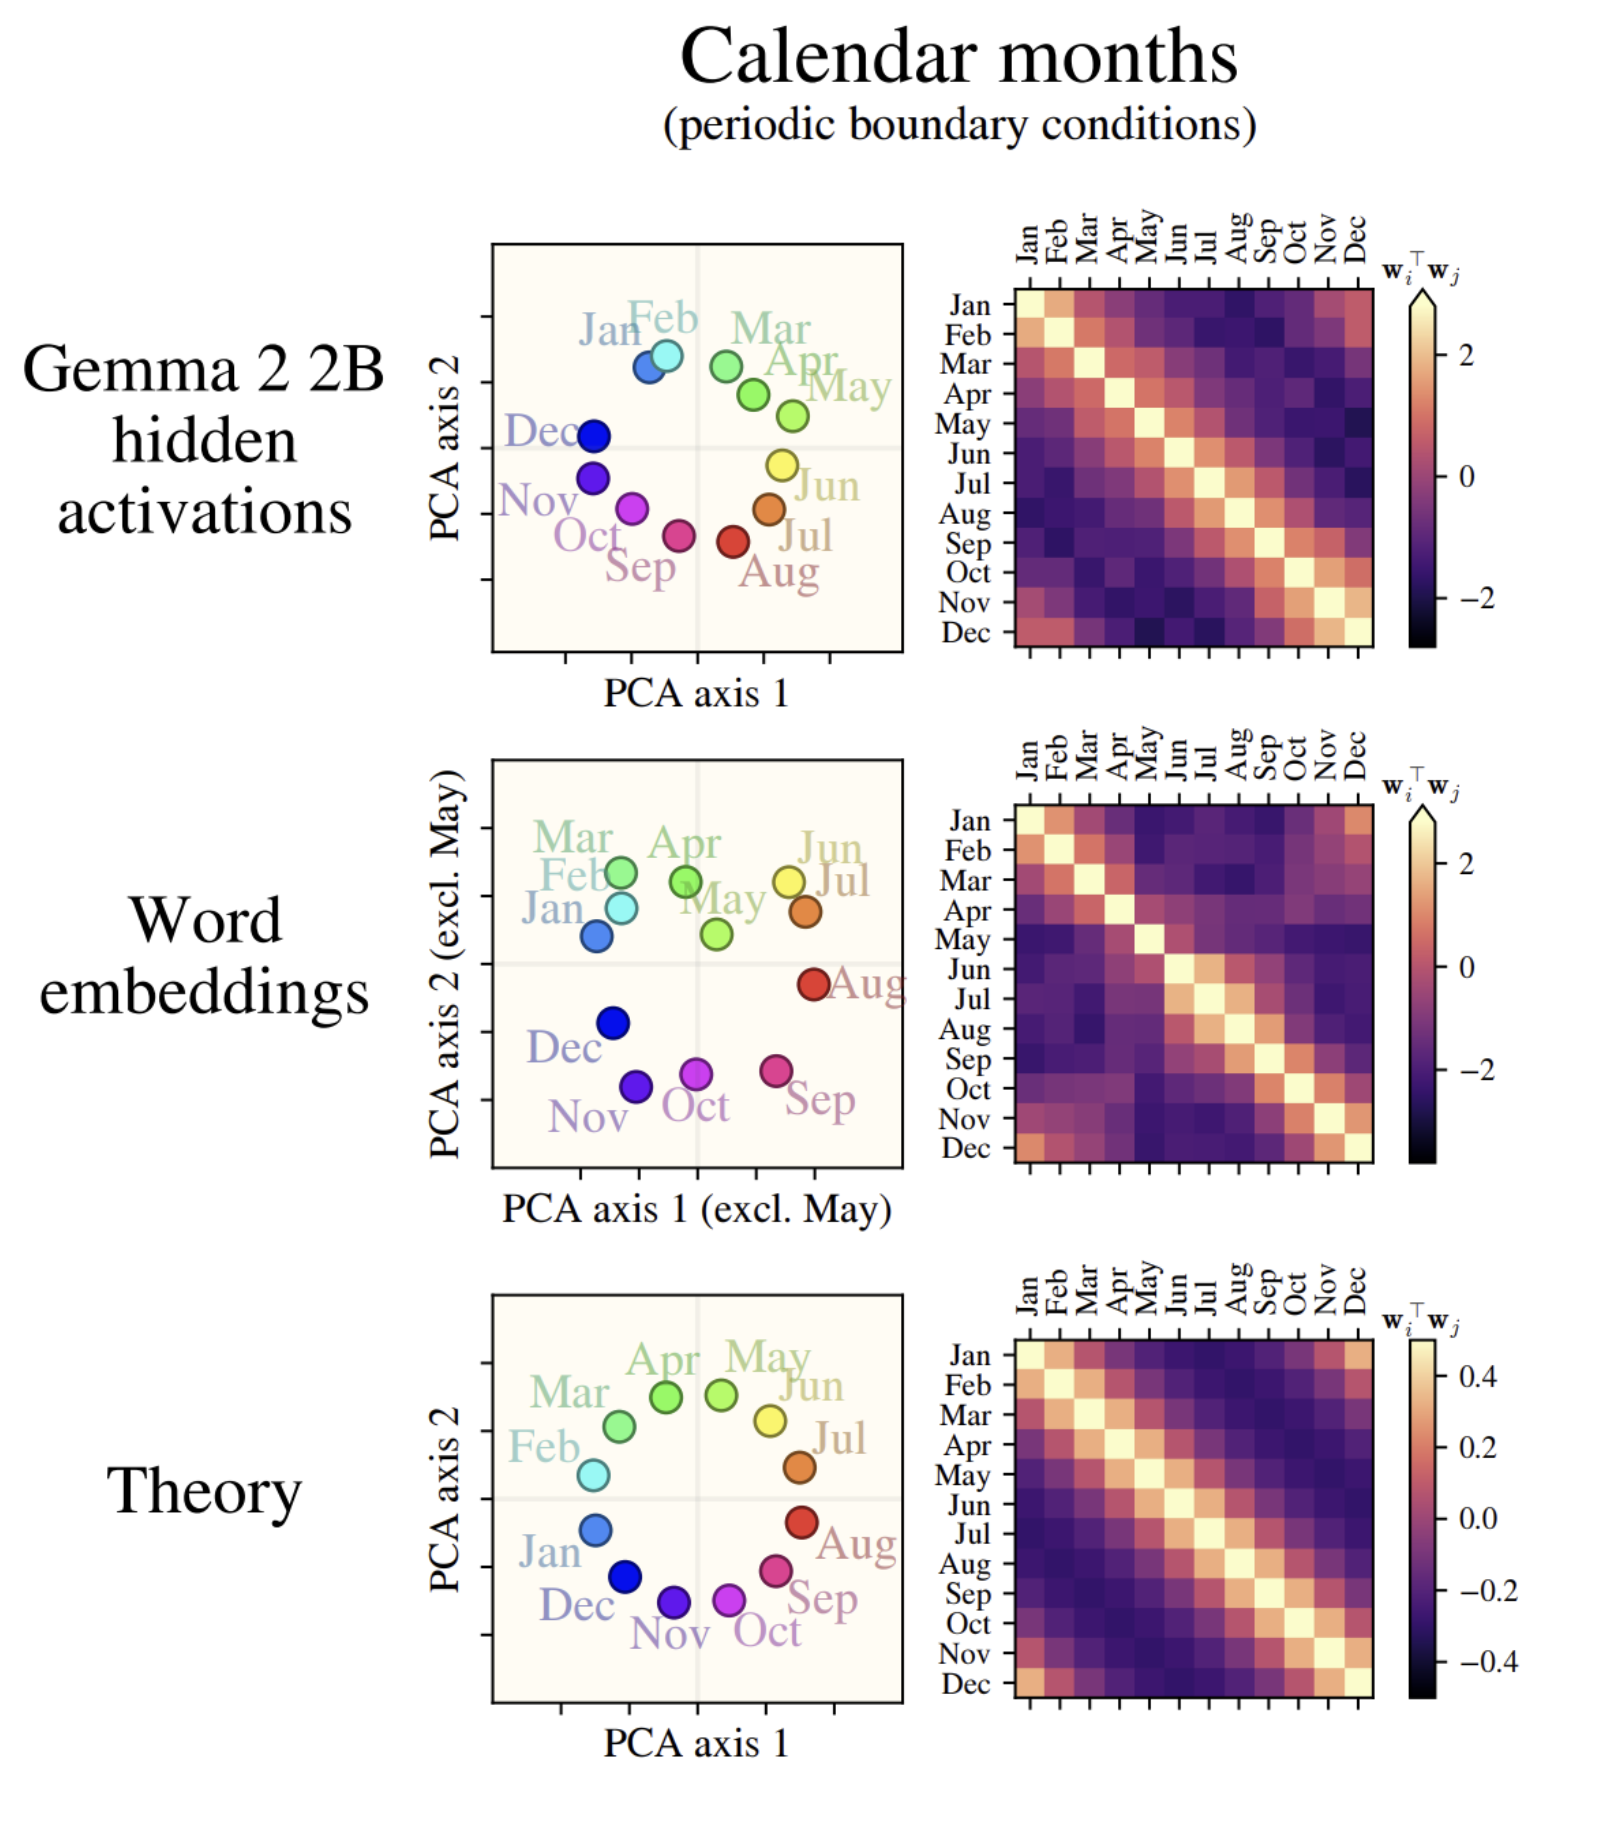
My longtime labmate-turned-student/friend1 Dhruva Karkada recently wrote a sick paper on data statistics which deservedly went viral on Twitter, in part beca...
I'm trying to understand the intuition behind Word2Vec training using a neural network. In Word2Vec (CBOW or Skip-gram), we often hear that the weight matrices learned during training contain the vector representations (embeddings) of words.…