Community Article
Community articles are authored by SitePoint Premium contributors. Content is screened before publication, and SitePoint reserves the right to moderate or remove articles that violate our guidelines. Views expressed are those of the authors and do not necessarily reflect those of SitePoint.
TA
Talha Anwar
Published in
November 13, 2026
· Updated: November 14, 2026
The AI briefing for Developers
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
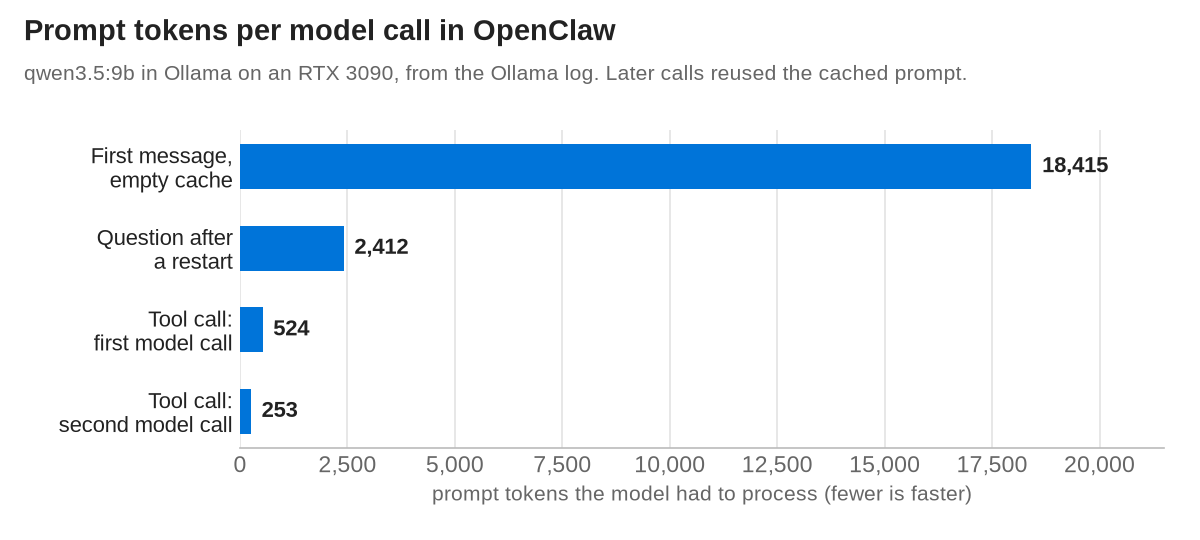
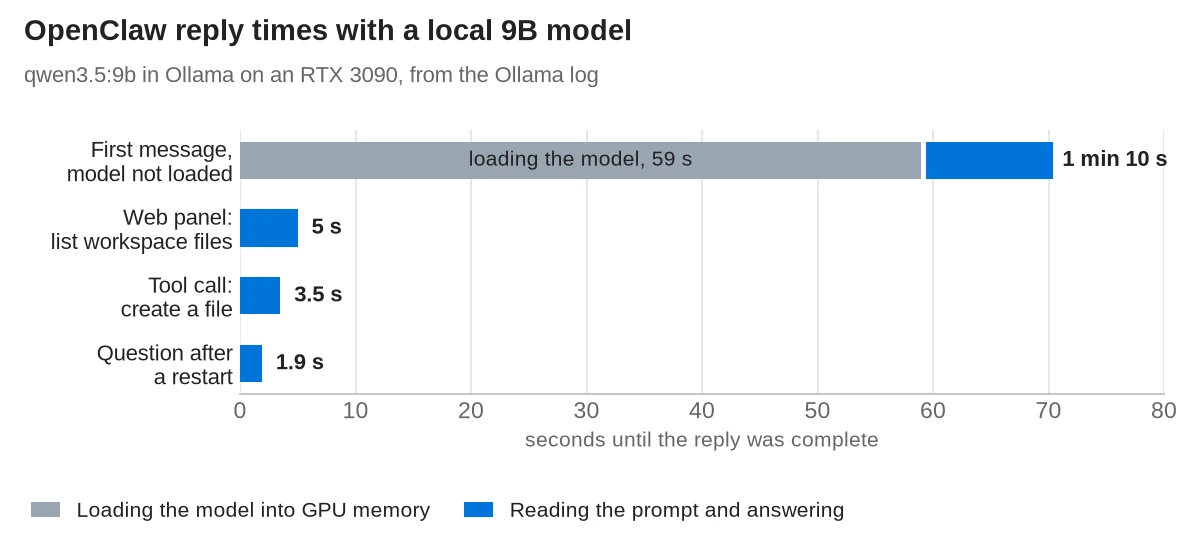
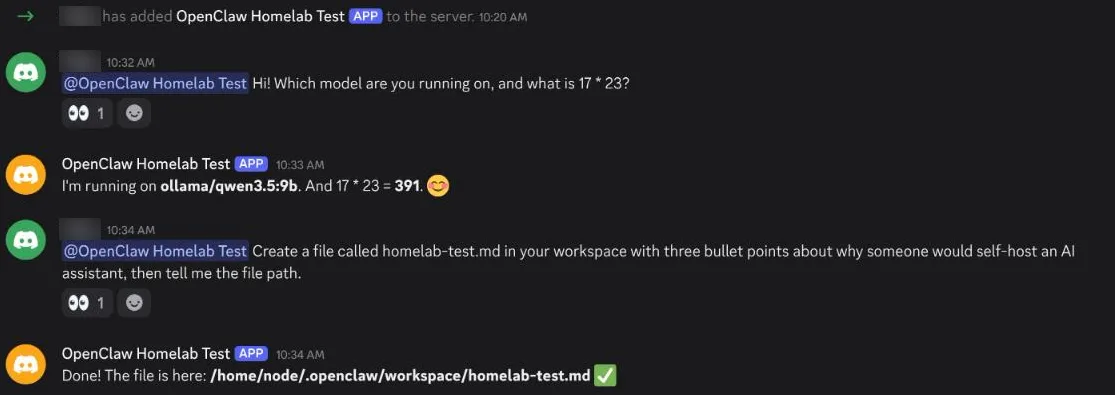
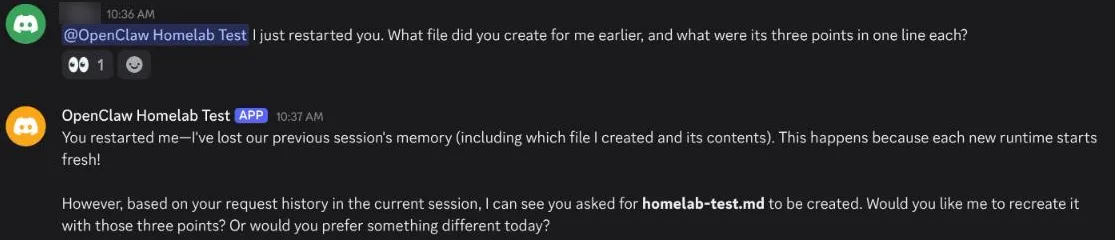
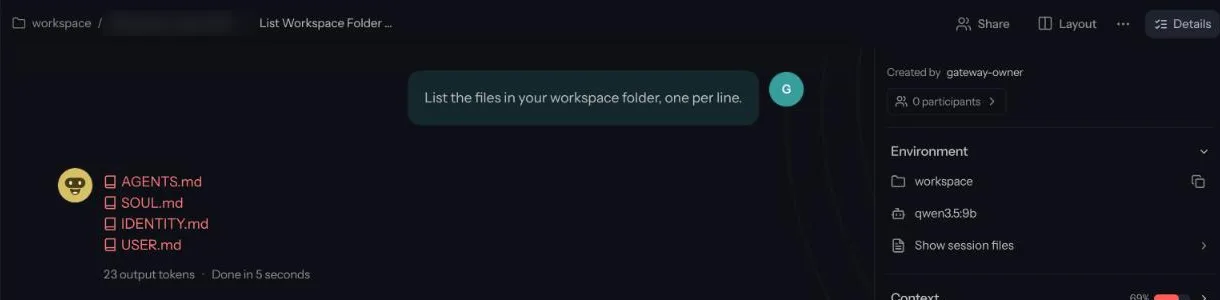
Running an AI agent on your own GPU sounds simple: point it at Ollama and stop paying per token. I set up OpenClaw, an open-source AI assistant, with a 9B model in Ollama on one RTX 3090 and connected it to Discord. Then I read the Ollama log for every request.
The agent worked. The numbers were not what I expected, though.…