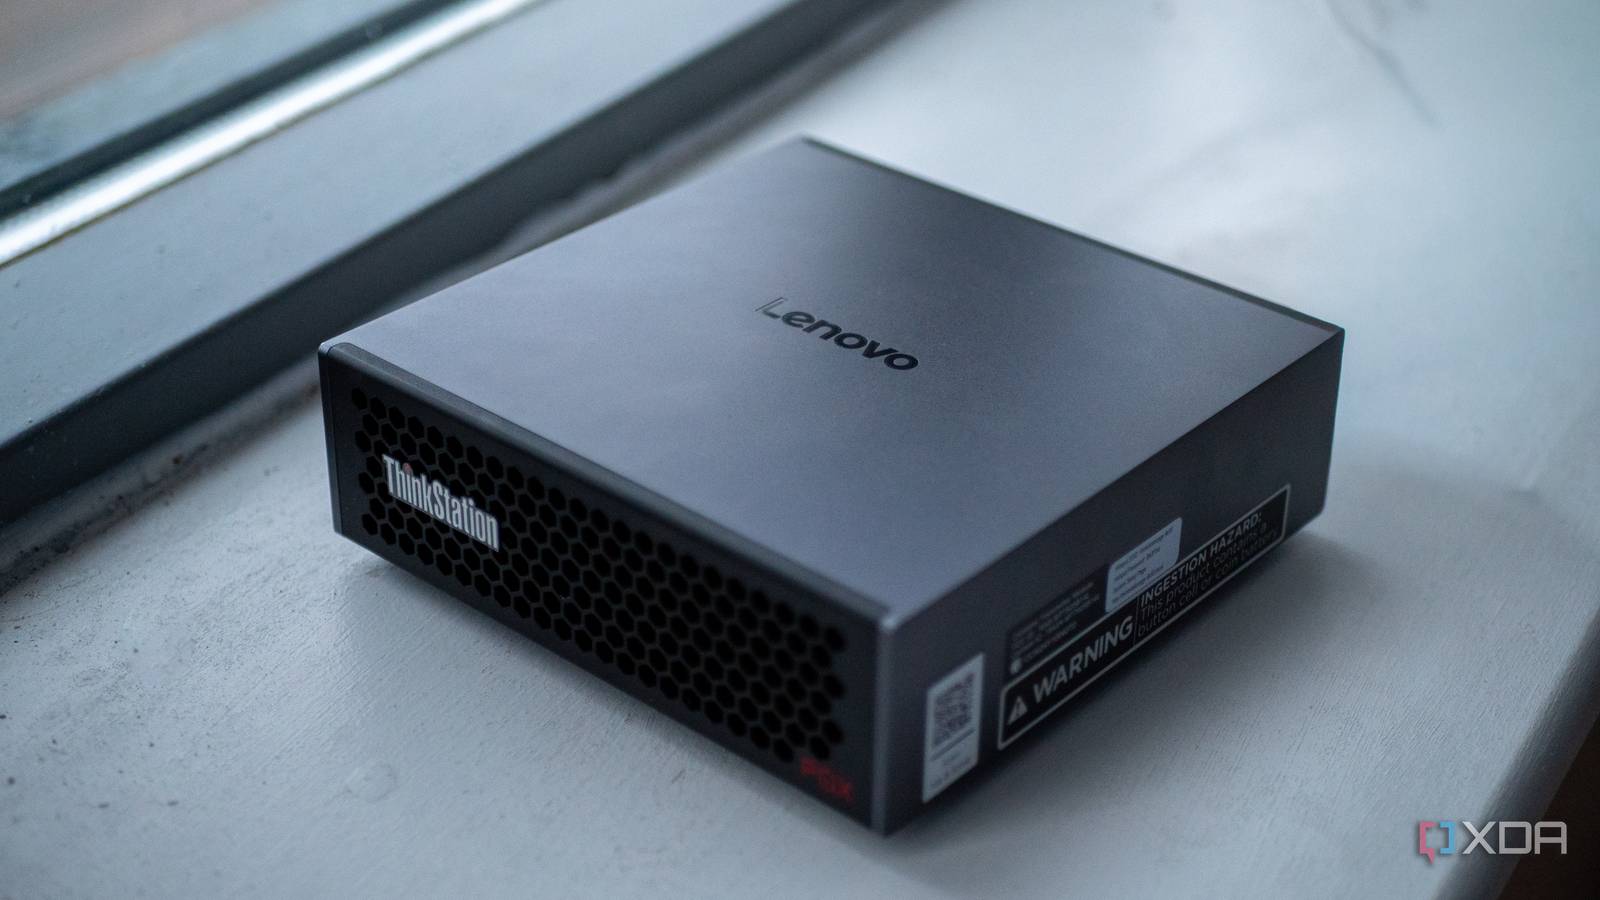
Qwen 3.8 27B was one of the most highly-anticipated open-weights releases that I've seen in a long time, and like many others, I immediately got to work testing it out and playing with it when it dropped. I'm running it on a single Lenovo ThinkStation PGX , the compact workstation built on Nvidia's GB10 Grace Blackwell chip, packing 128 GB of unified memory and 273 GB/s of bandwidth. Out of the box, it manages a fairly dull 15 to 30 tokens a second, but with an SGLang, NVFP4, and DFlash2 speculative-decoding setup that's become the standard recipe for this hardware, it can reach around 50 tokens a second on code and reasoning. One of my tests, though, proved just how incredible local models have become. There are reasons to believe the hype when it comes to the Qwen models; I've had consistently good experiences with Qwen 3.6 27B , and Qwen 3.8 27B is, so far, more of the same but better.…