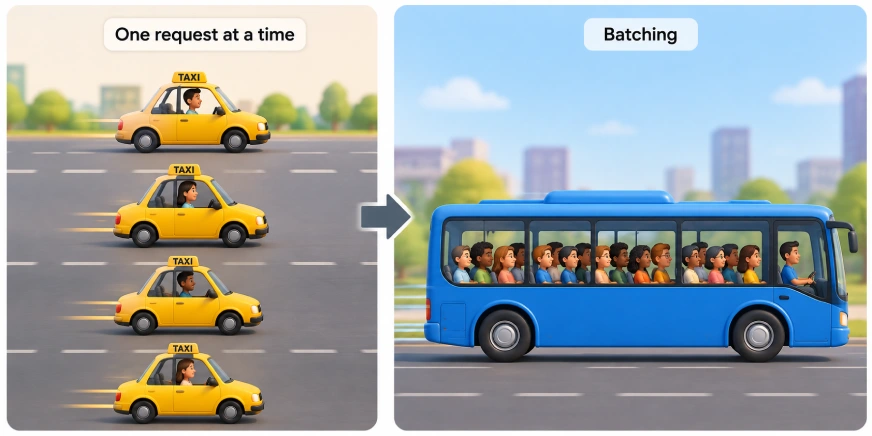
Imagine four people booking a ride to the same destination. If each person takes a separate taxi, four vehicles make the same trip. But if they travel together in a bus, everyone reaches the destination in a single trip. The bus carries more people at once and makes better use of the resources.
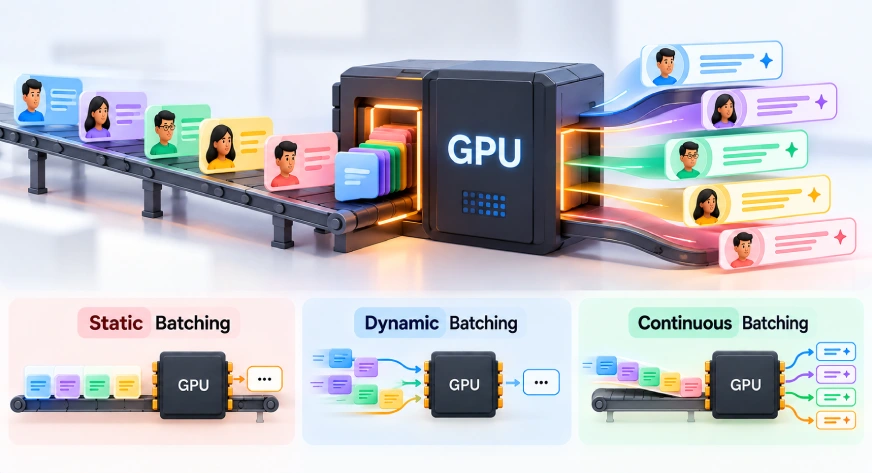
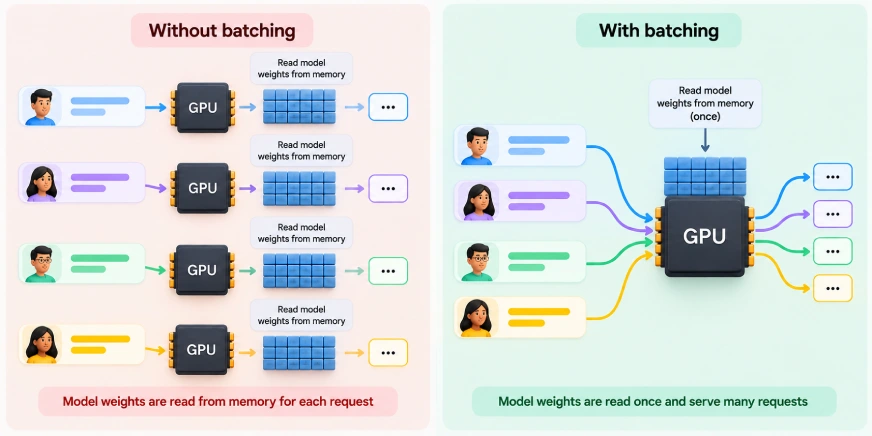
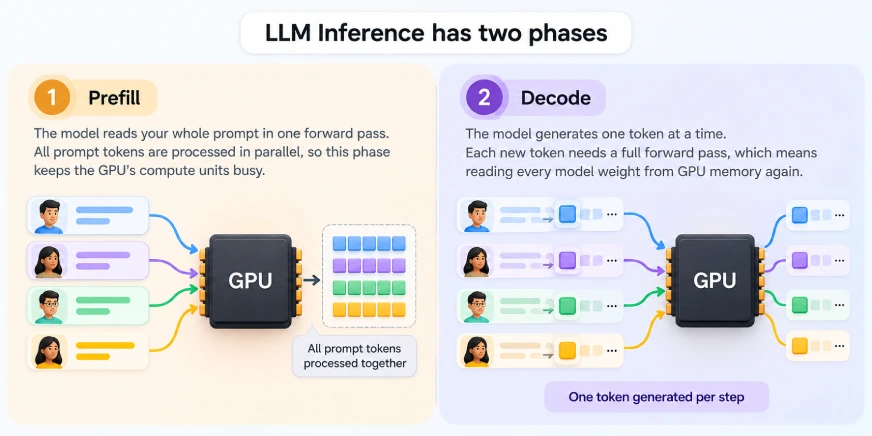
Batching in AI works in a similar way. Instead of processing one request at a time, a server groups multiple requests together so the GPU can process them more efficiently. This helps serve more users while making better use of expensive computing resources. But how those requests are grouped and scheduled also affects how quickly users get responses and how much it costs to serve them.
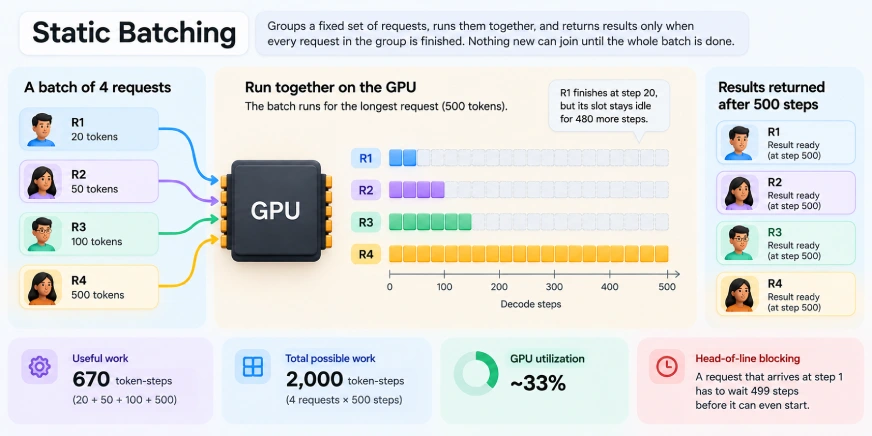
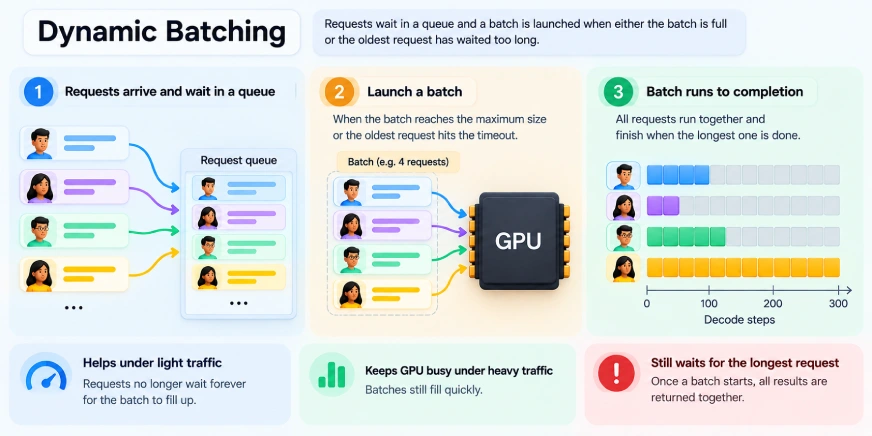
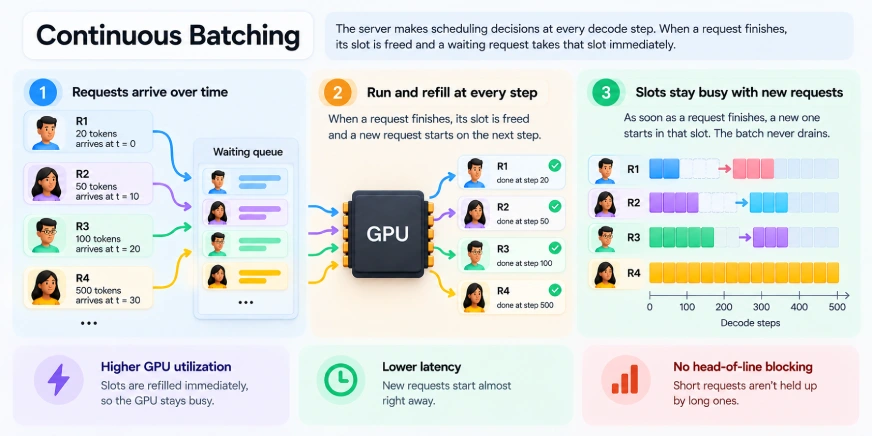
There are three common approaches to batching: static batching, dynamic batching, and continuous batching.…