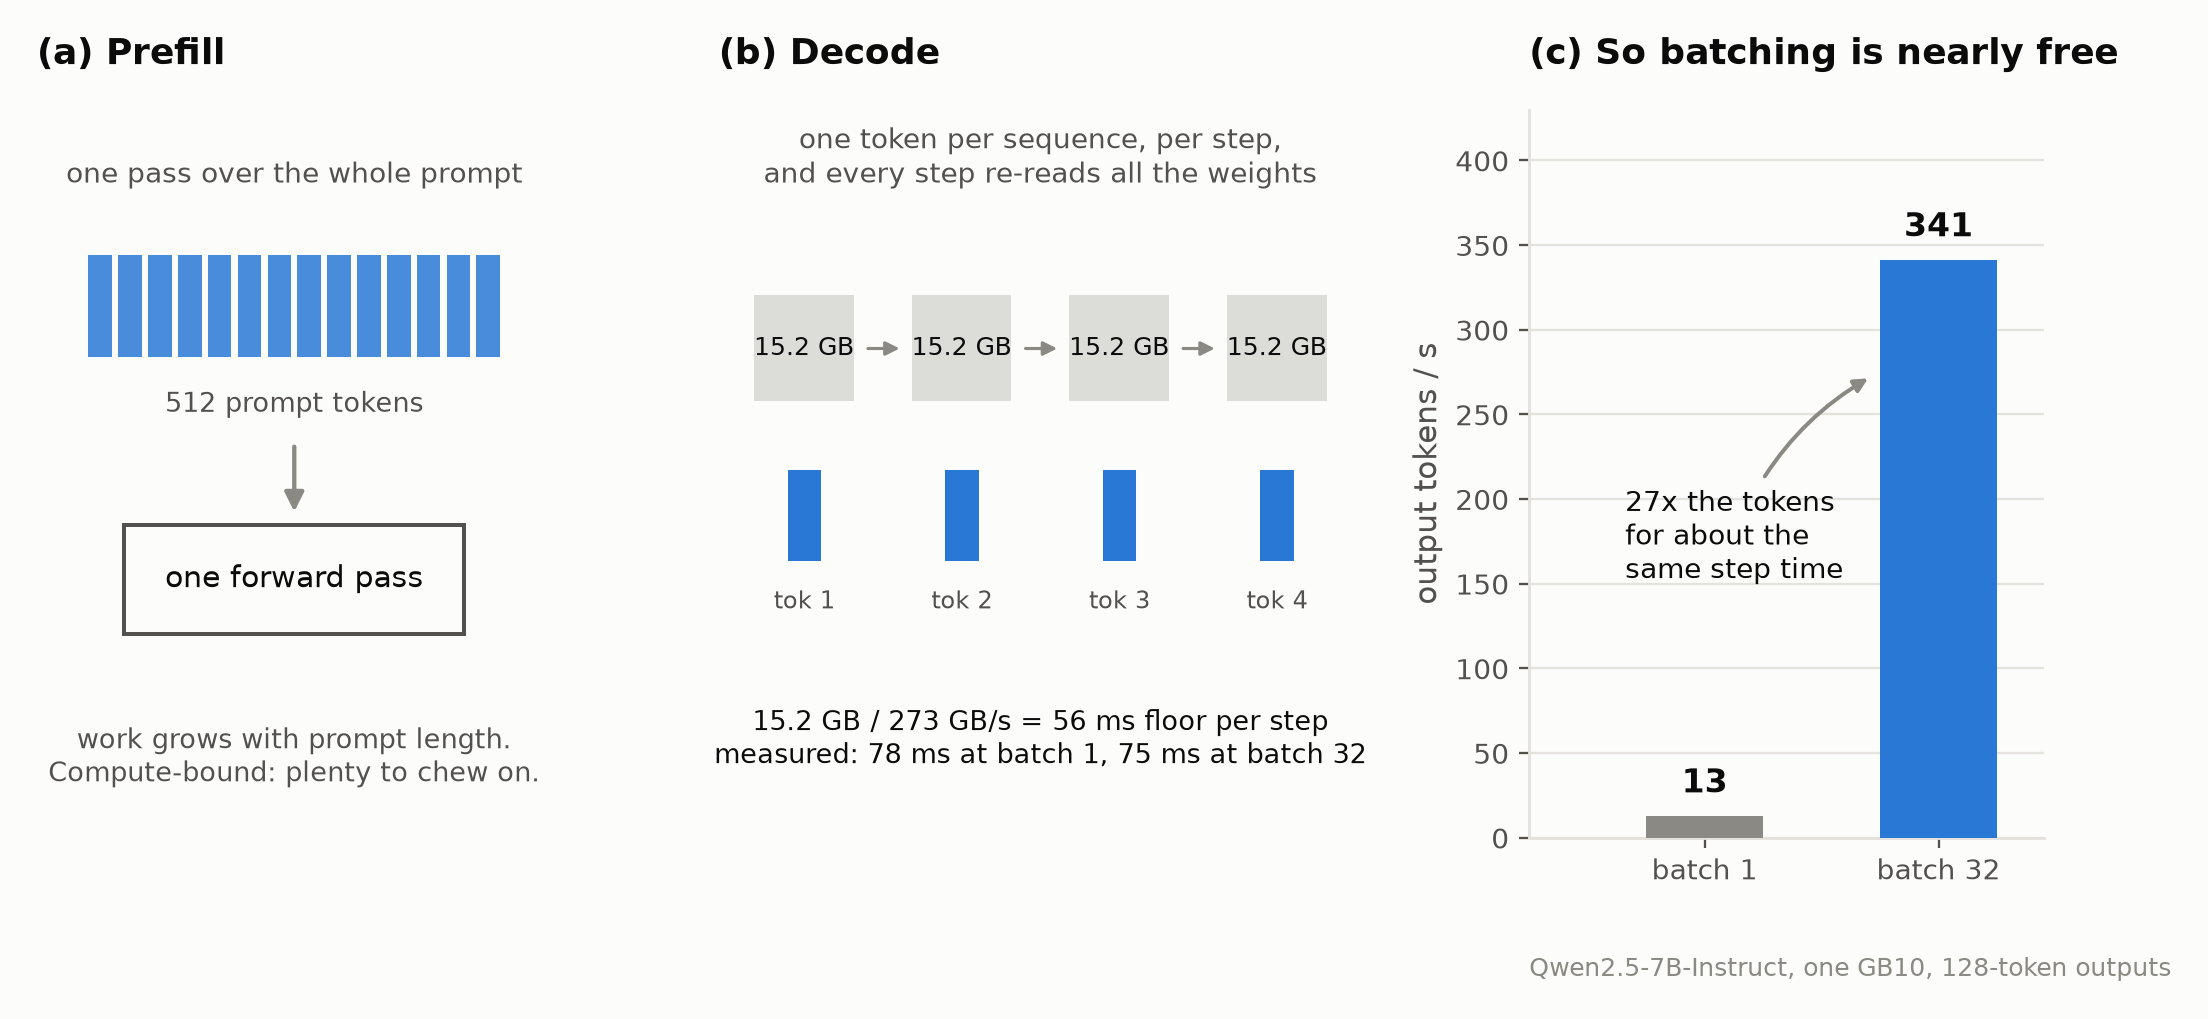
🖼️00Read later0Read MoreContinuous Batching Gave 1.00× at Zero Variance and 2.91× on Chat-Like TrafficTowards Data Science·Nhu Hoang·7 days ago#SzQGieOW#towardsdatascience#science#batching#continuous#requests+5 more🧰Tag tools✨Add tagFor anyone running an inference server: a zero-variance control, five traffic traces, and an engine-vs-scheduler split show where the gains come from.15s
🖼️00Read later0Read MoreBatching in ReactDEV Community: frontend·Boula Akladyous·14 days ago#J7uAnU6o#devtofrontend#devto#dev#react#updates+6 more🧰Tag tools✨Add tagView the full articleCreate a free account to read full articles inline — no redirect to the original site.Create accountLog in
📰00Read later0Read MoreBatching is the feature: serving PyTorch at low trafficDEV Community: pytorch·Taylor Parker·20 days ago#eMw3fDQK#devtopytorch#devto#dev#batching#traffic+6 more🧰Tag tools✨Add tagAt low traffic, a model server is mostly idle. The obvious optimization — batching — is also the one...15s
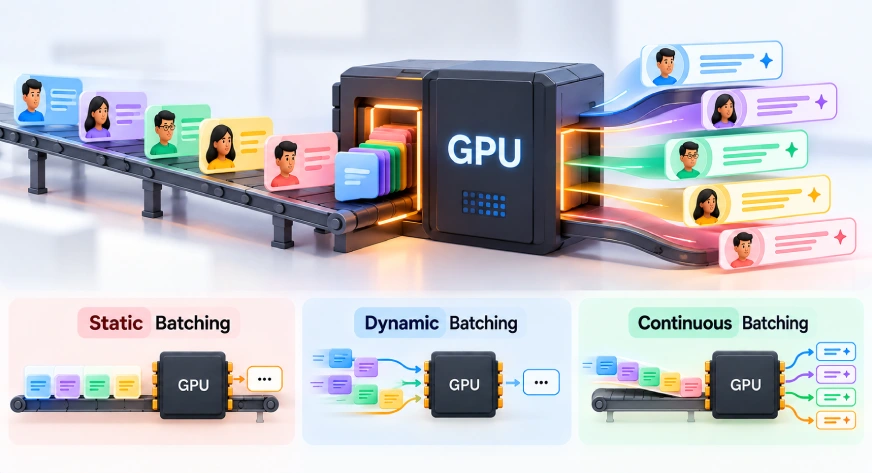
🖼️00Read later0Read MoreLLM Batching Explained: Static vs Dynamic vs Continuous BatchingAnalytics Vidhya·Soumil Jain·25 days ago#BKR6l3v2#analyticsvidhyacom#analyticsvidhya#batching#requests#batch+5 more🧰Tag tools✨Add tagLearn how LLM batching works and compare static, dynamic, and continuous batching to understand GPU utilization, inference speed, and serving costs.15s
🖼️00Read later0Read MoreLLM Inference Optimization: Batching, Quantization, and Speculative DecodingDEV Community·Yash Pritwani·6 months ago#U35igHHW#technique#for#webdev#model#latency+5 more🧰Tag tools✨Add tagFrom Dev.to - webdev: LLM Inference Optimization: Batching, Quantization, and Speculative Decoding15s