Introduction
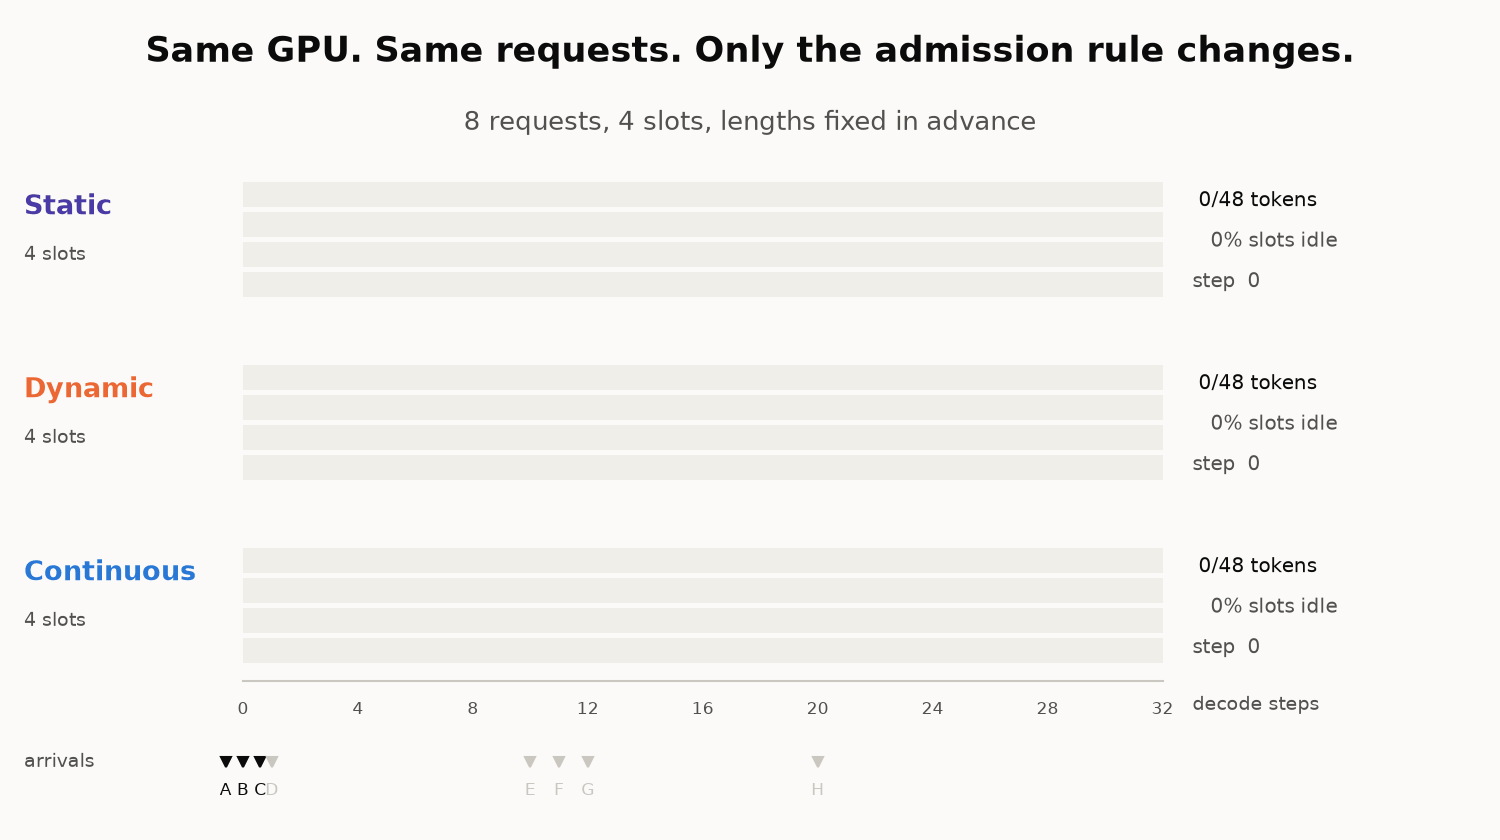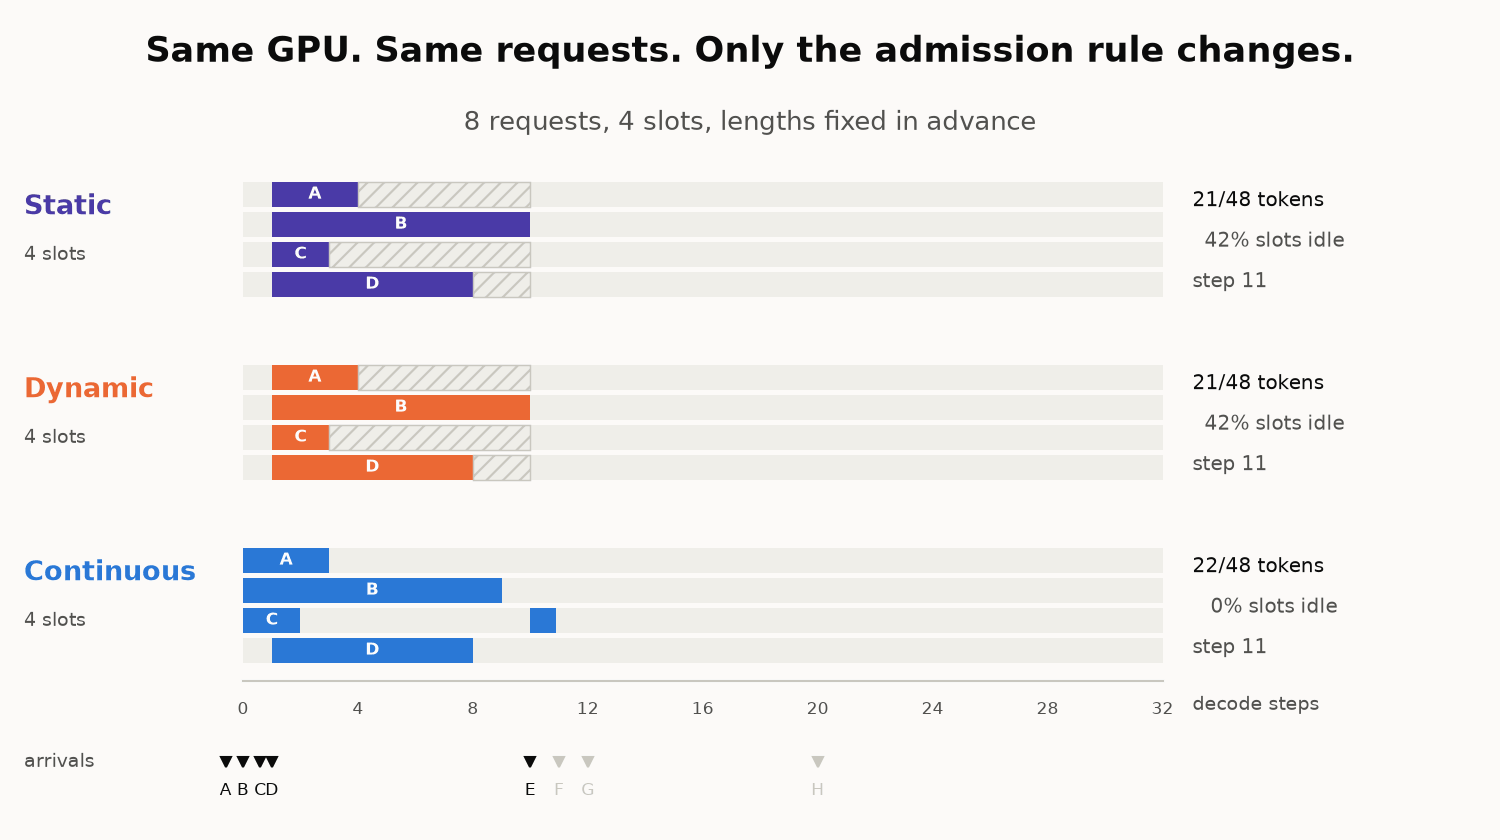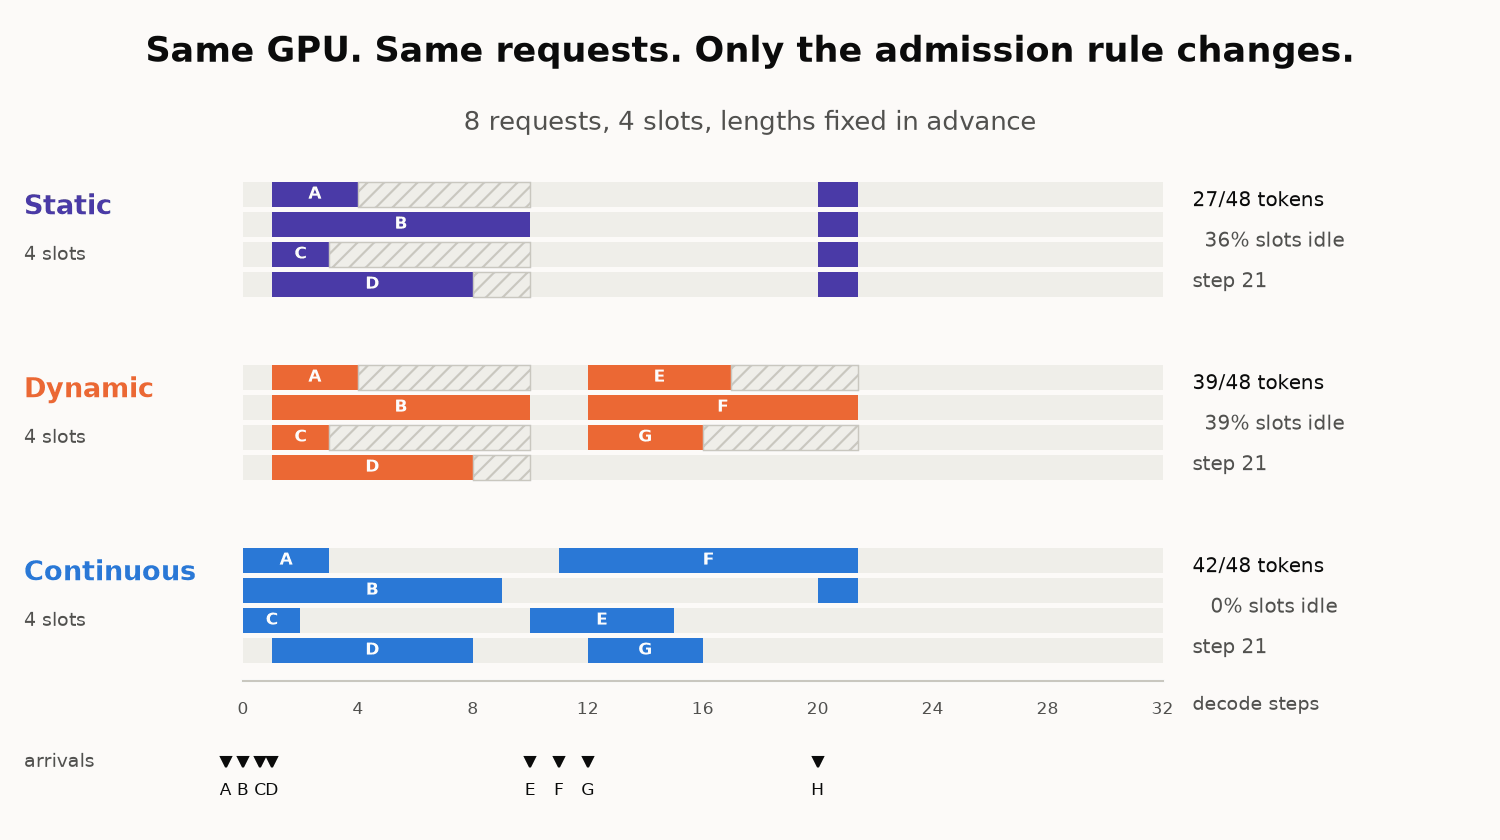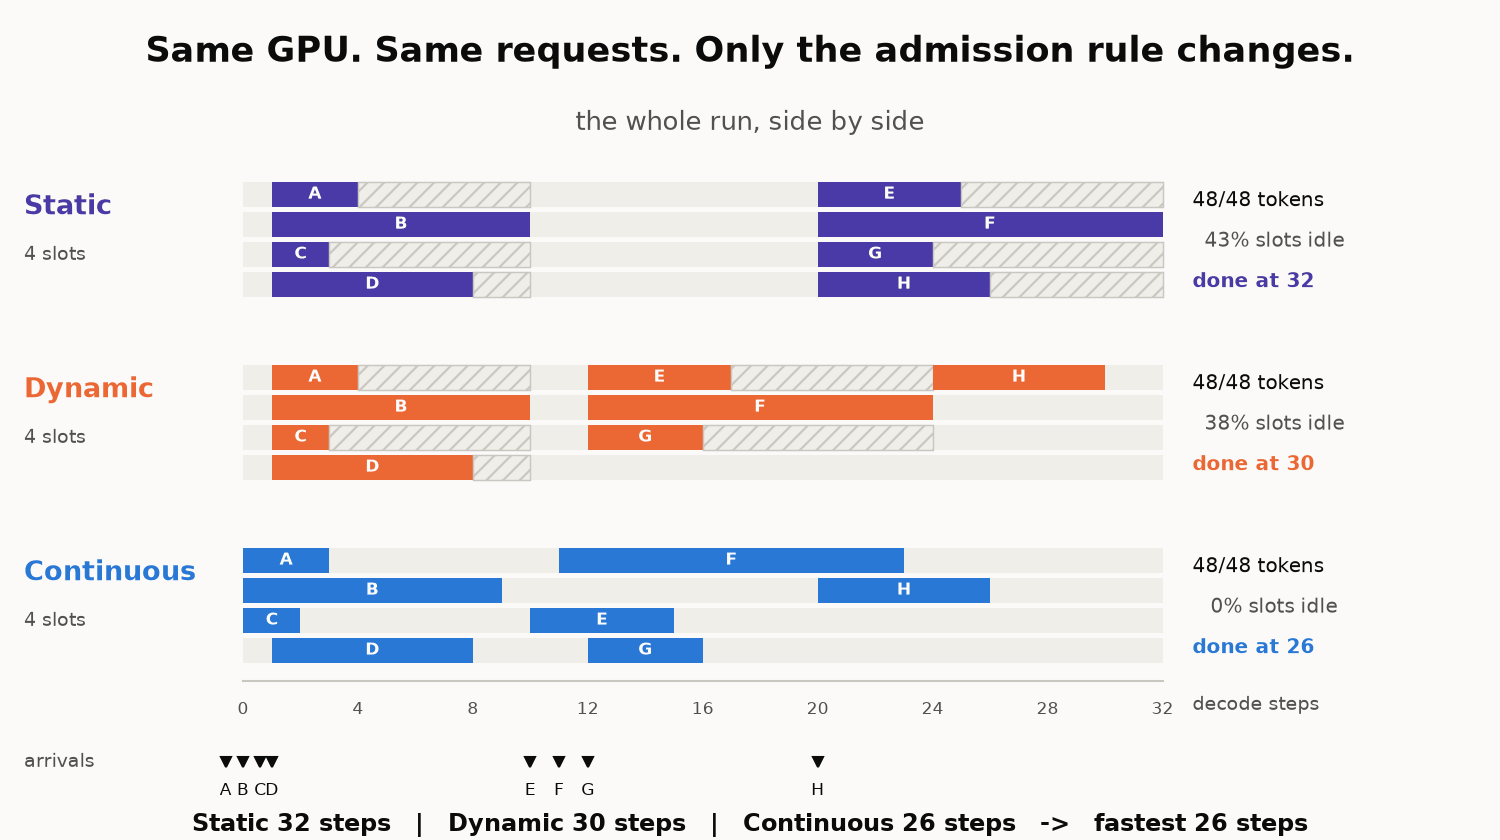
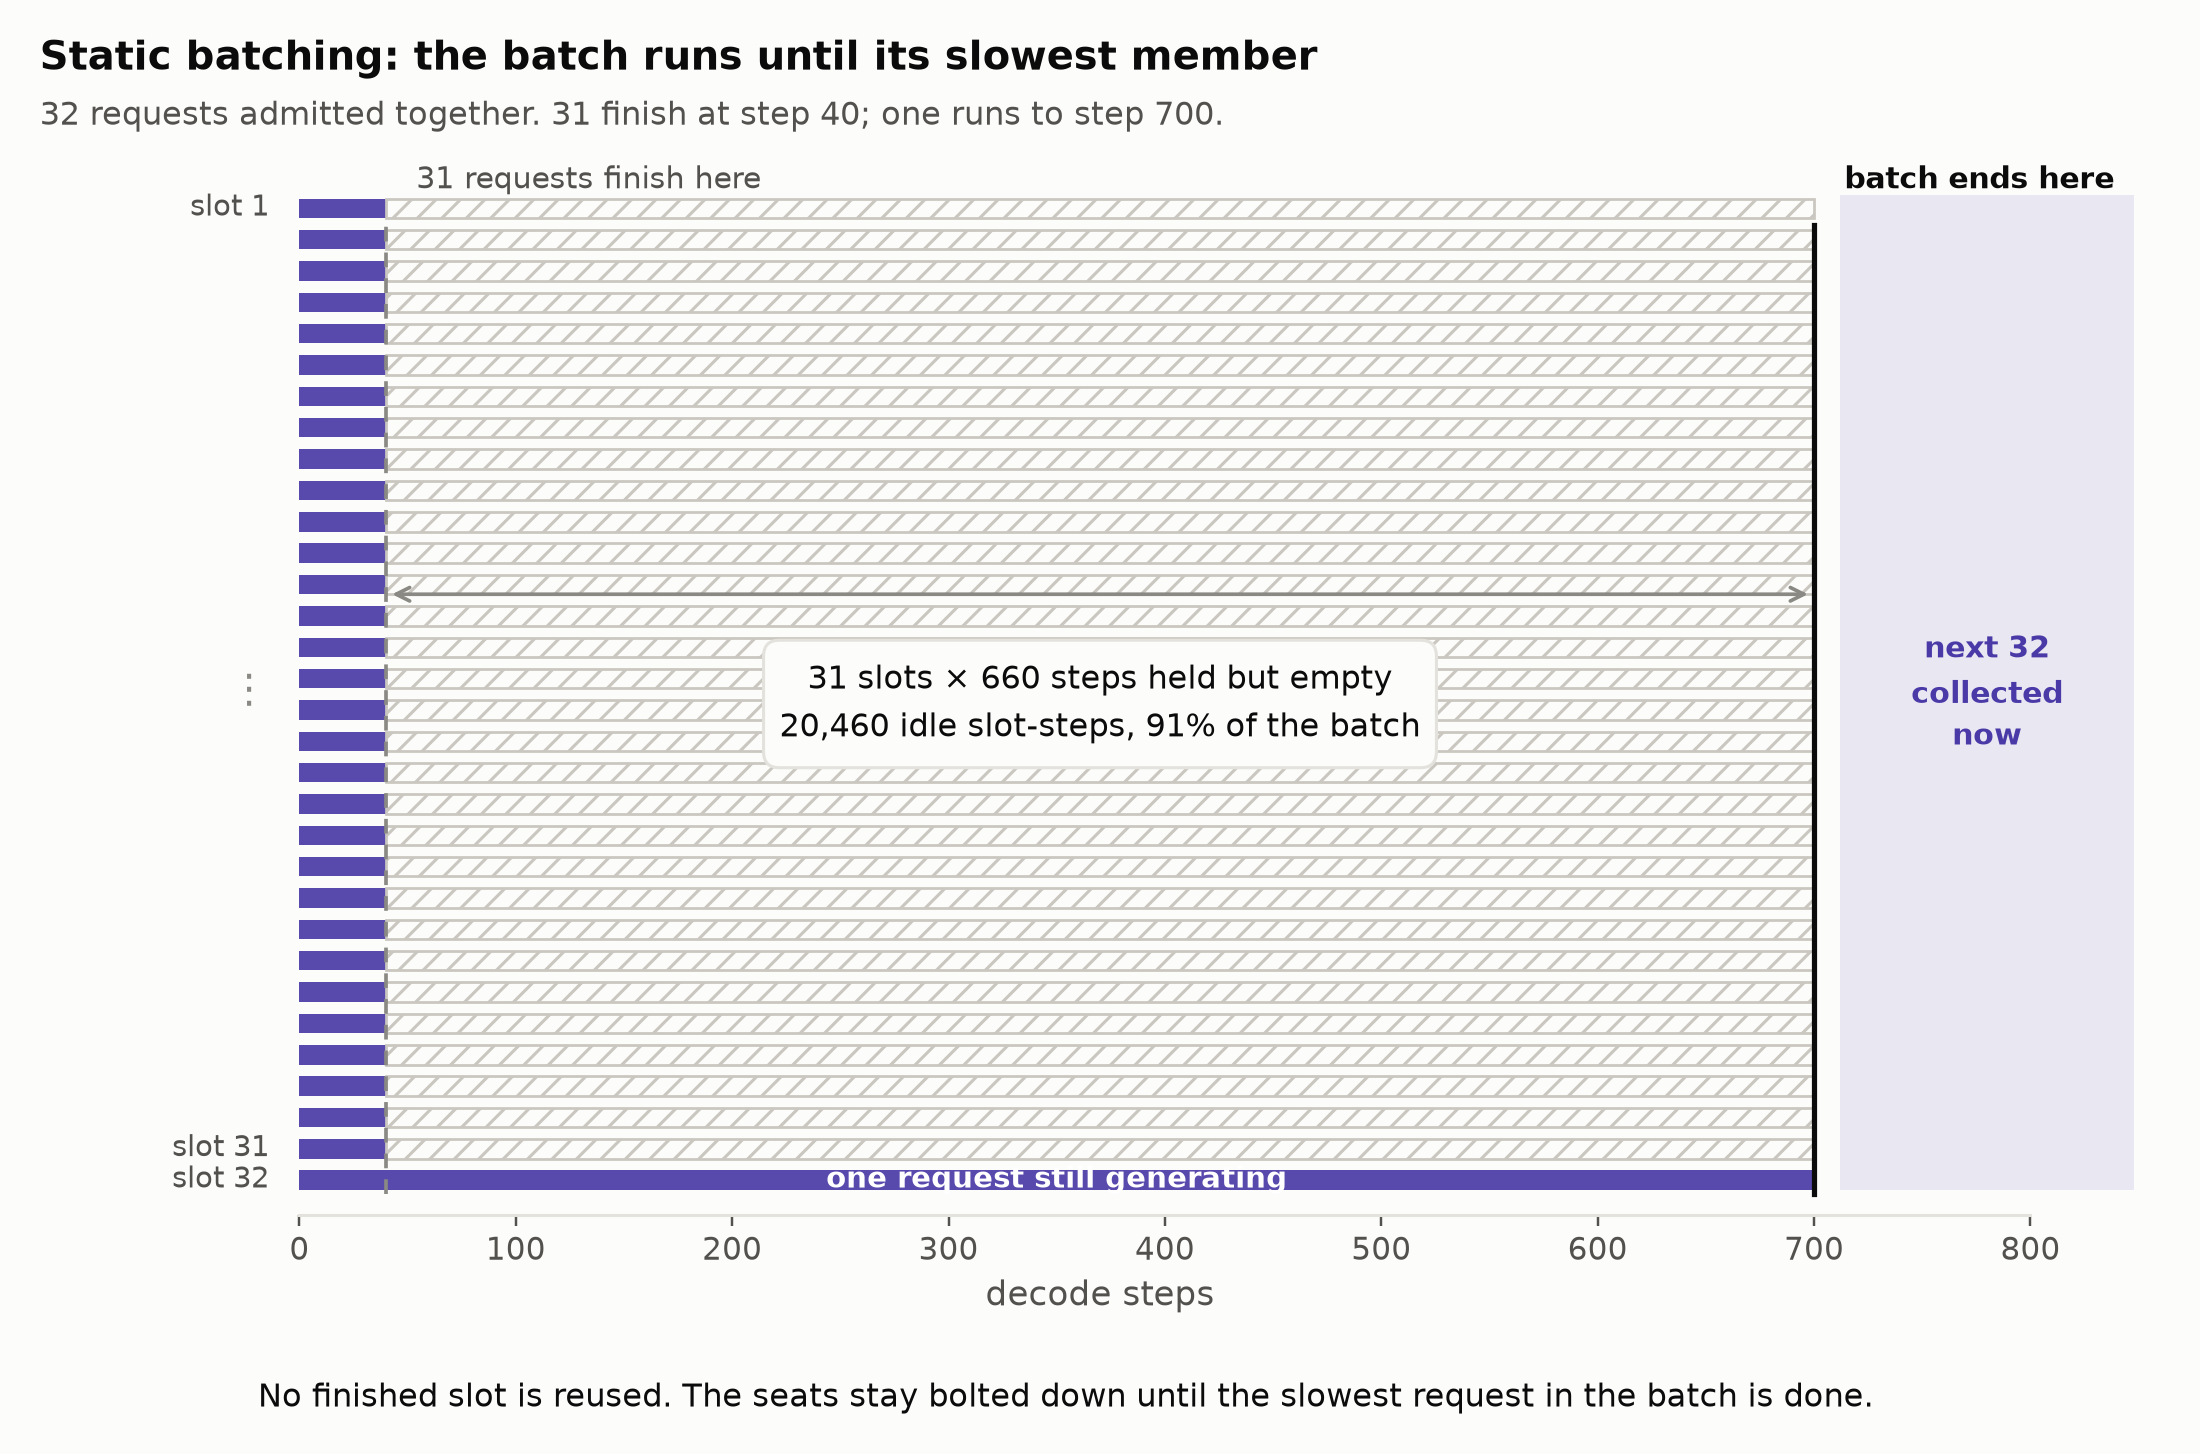
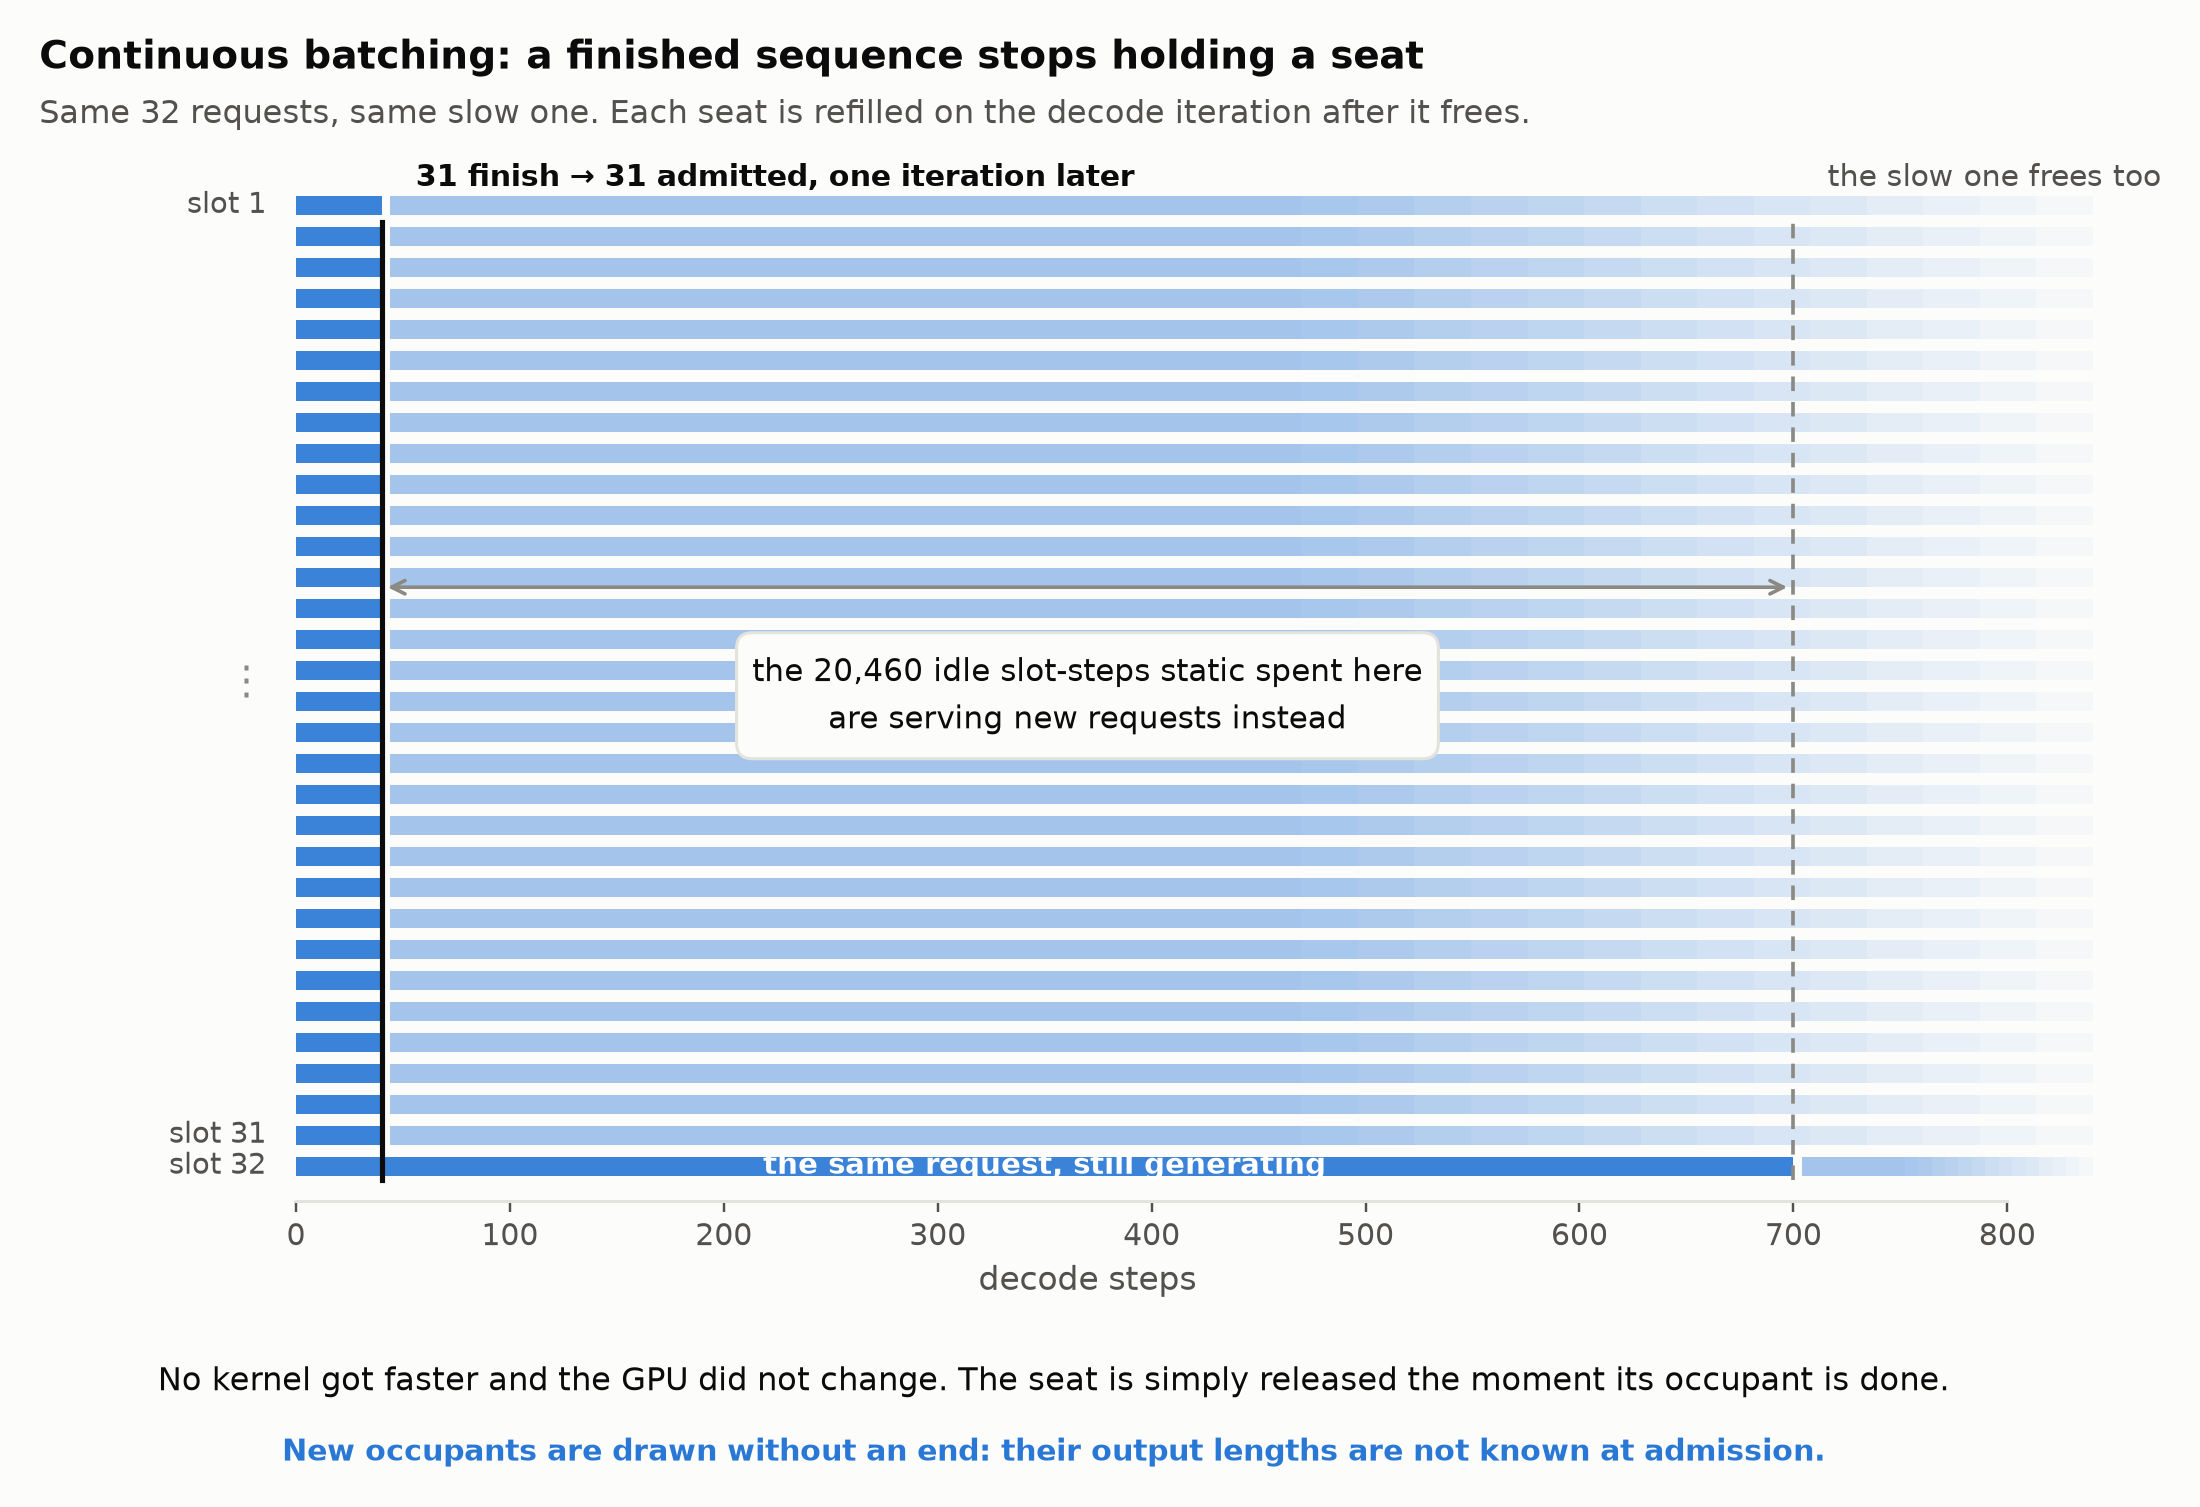
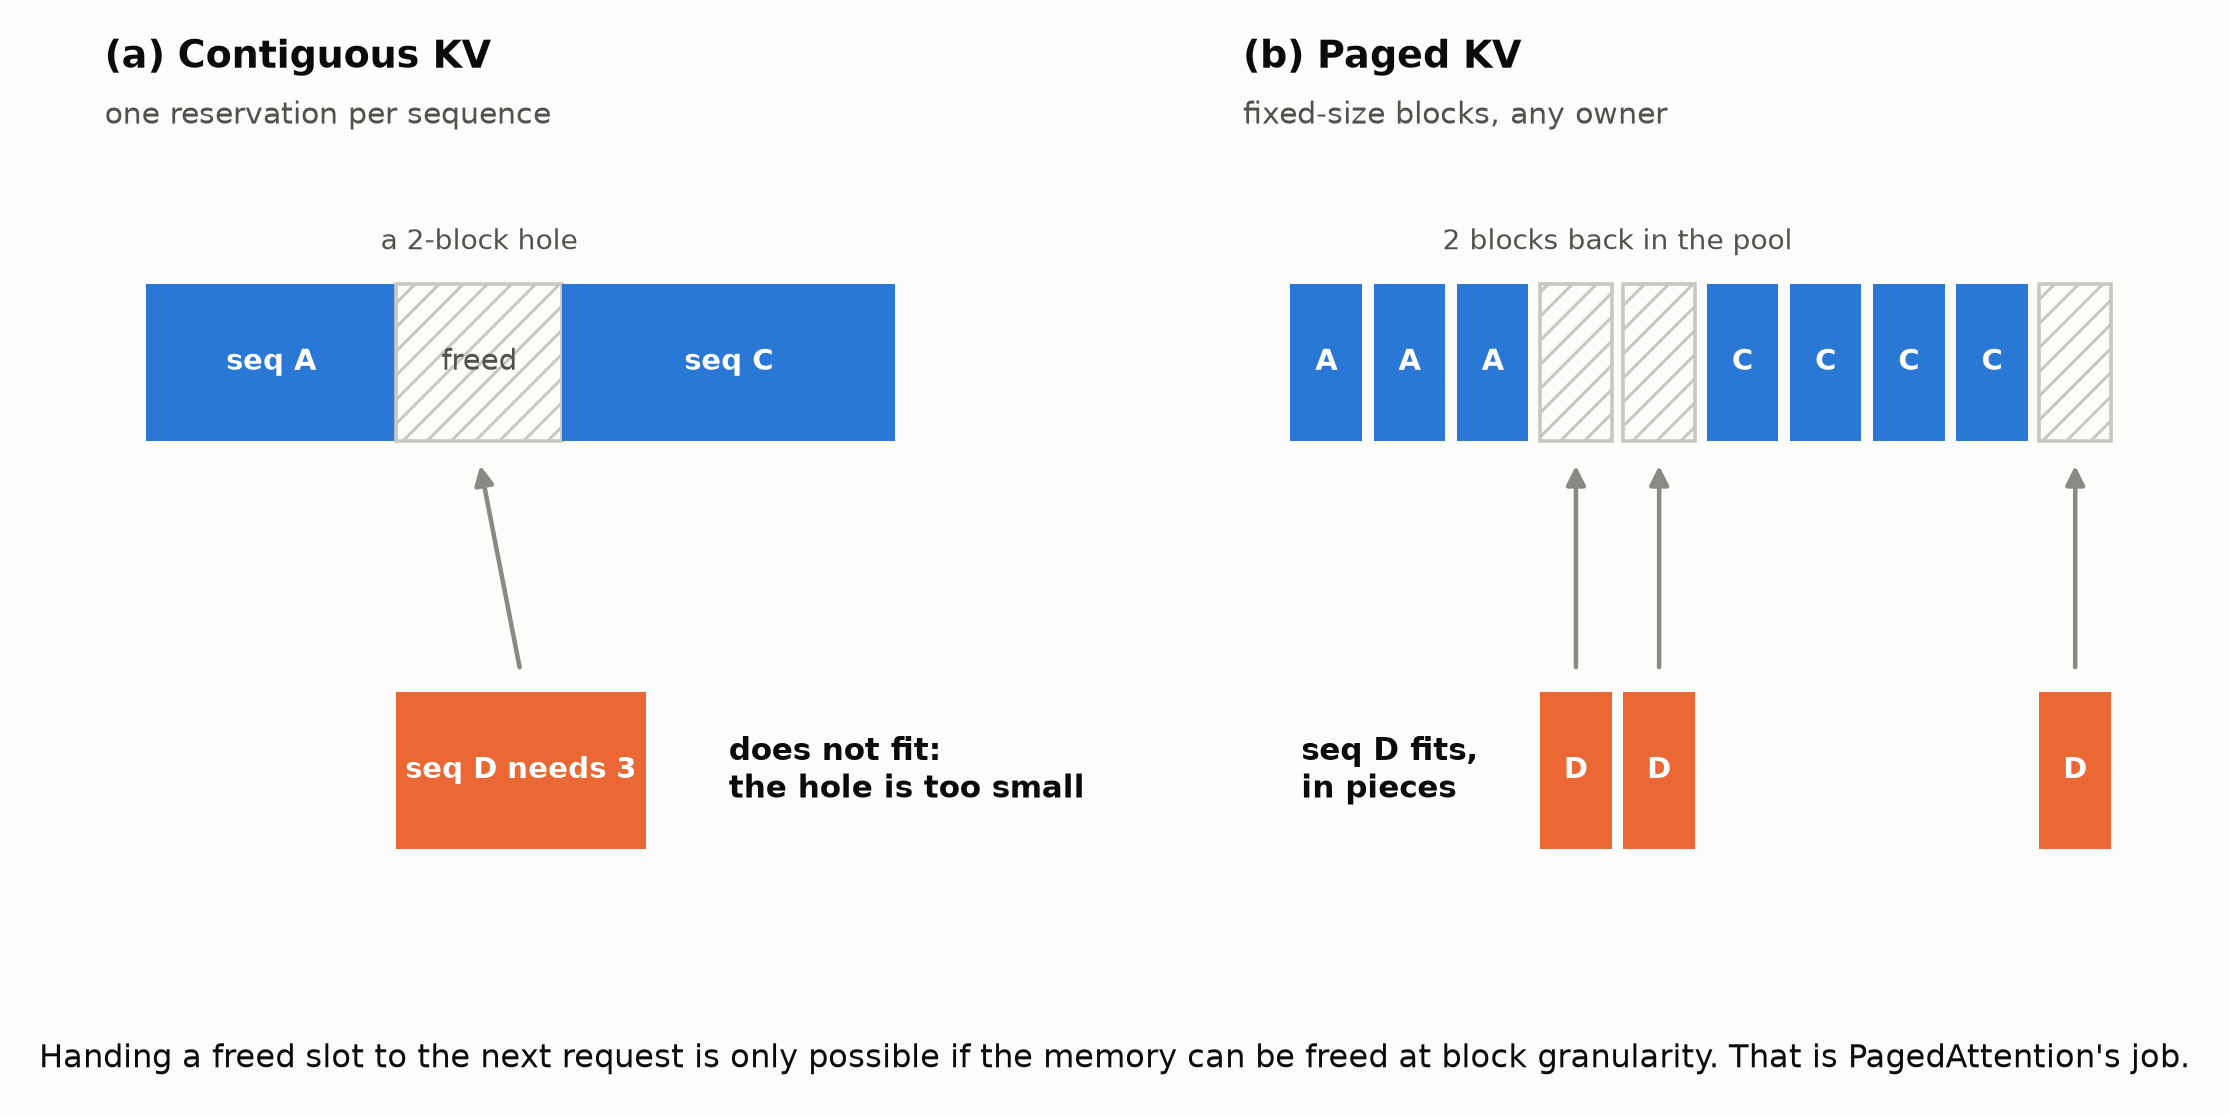
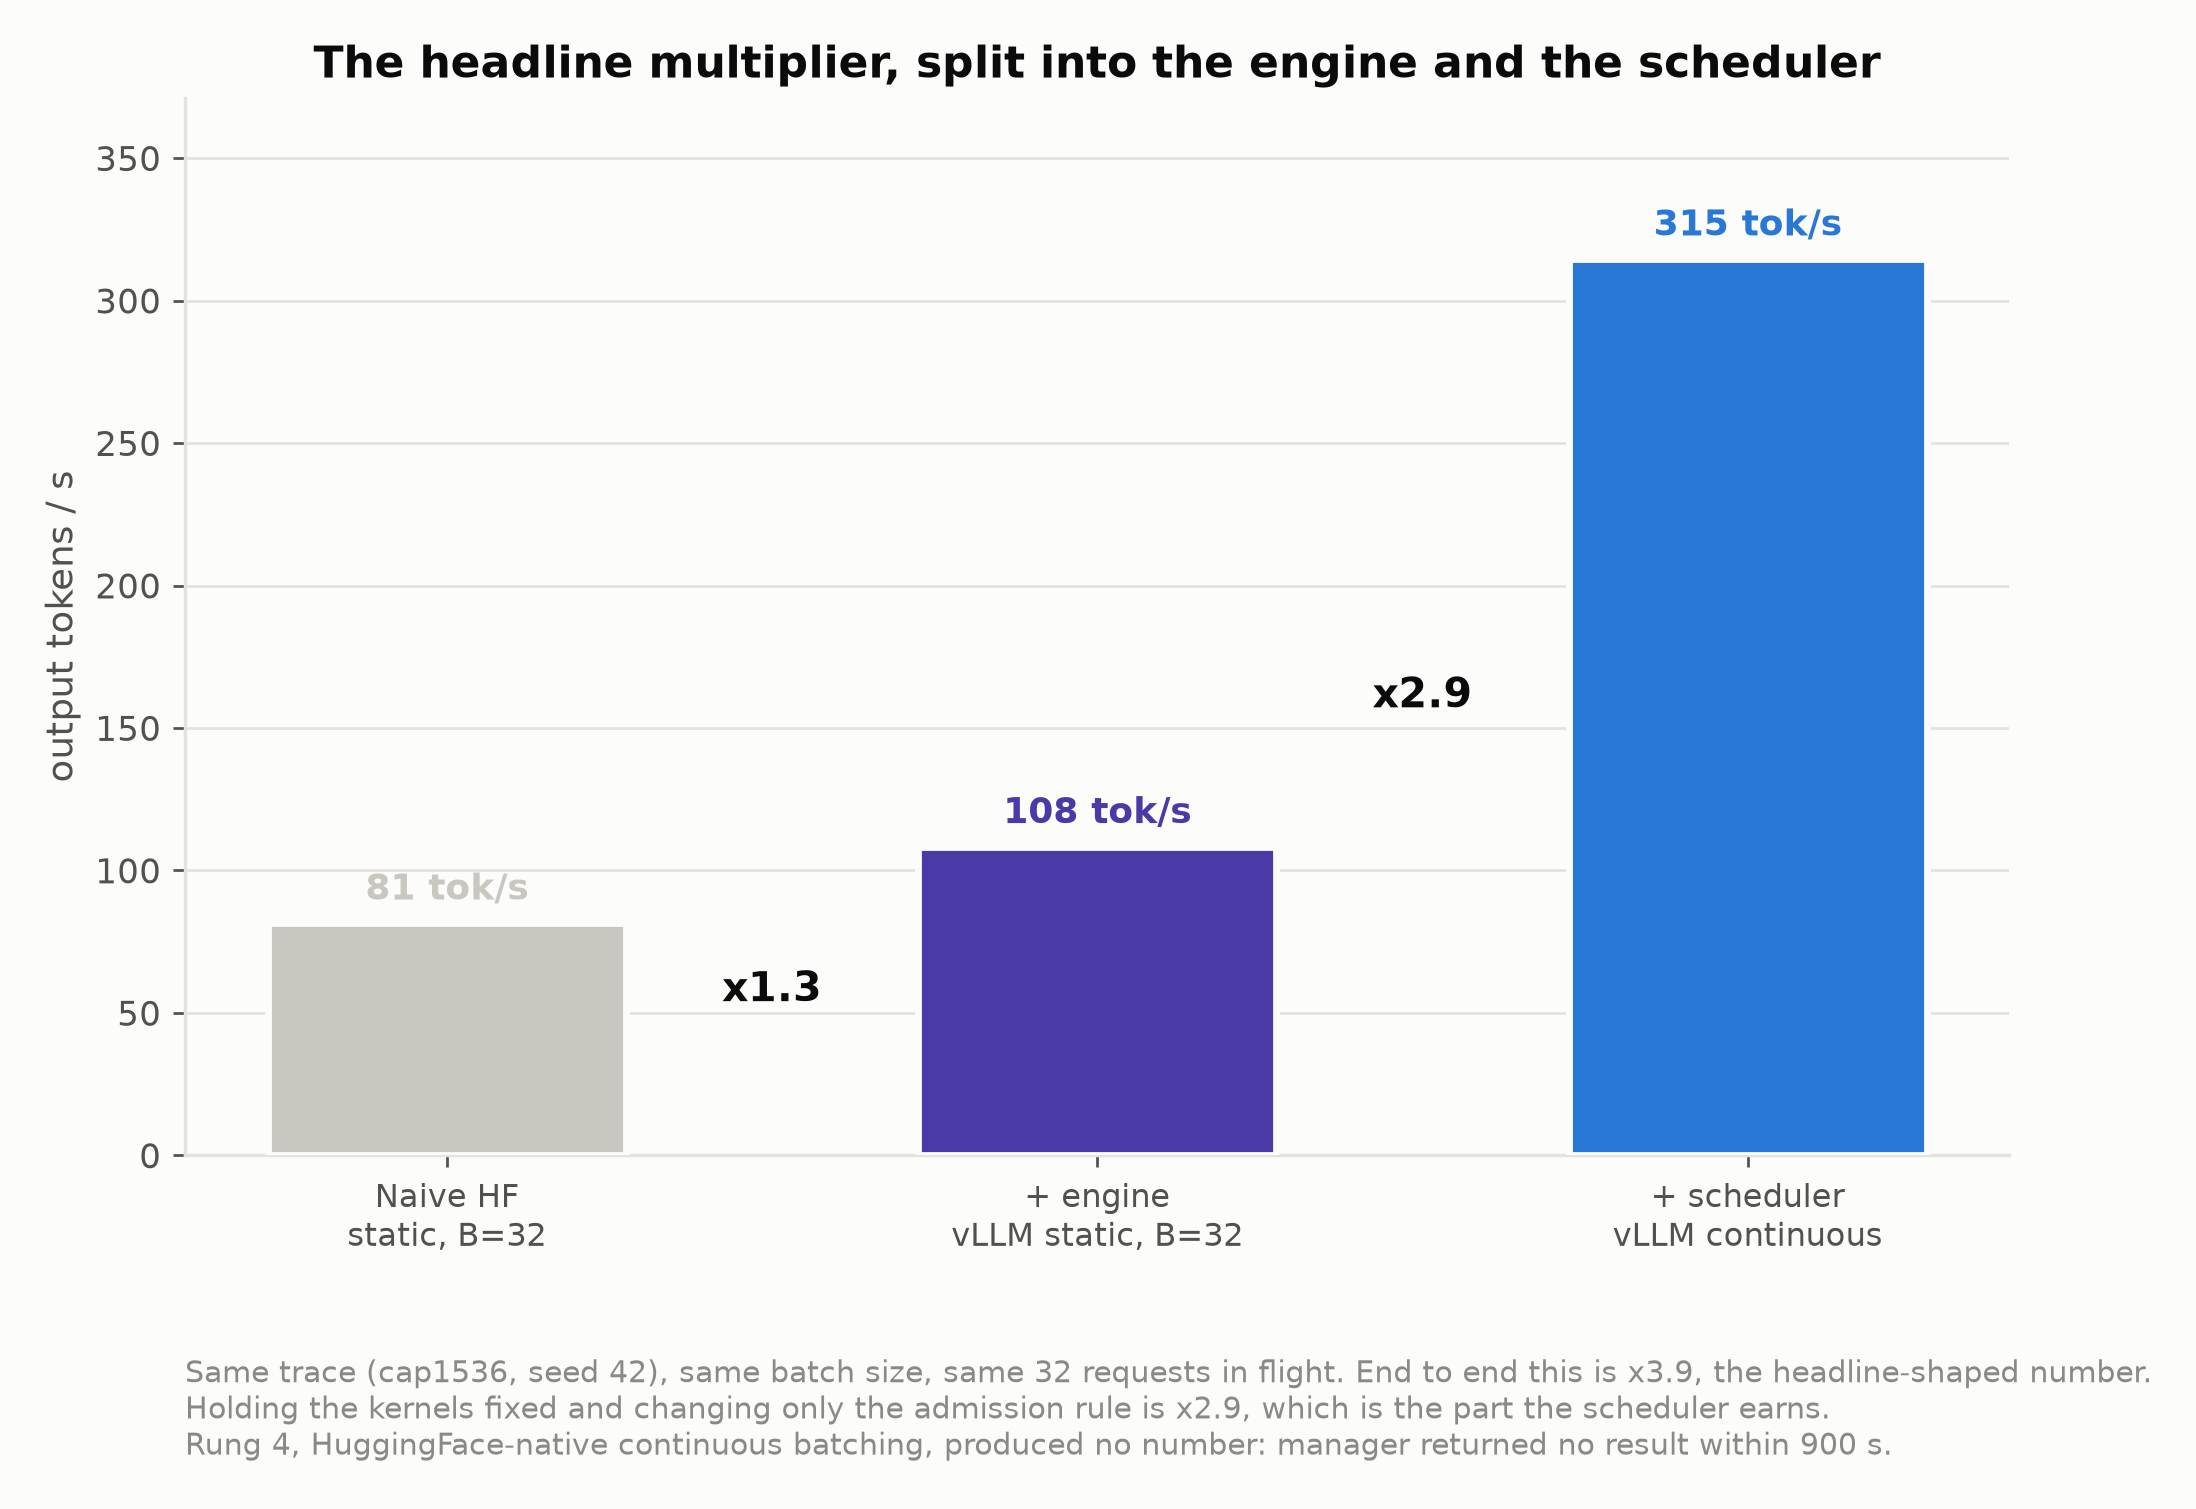
There is one number I kept seeing in LLM serving discussions: Anyscale reports up to 23× throughput over naive HuggingFace transformers using continuous batching and related memory optimizations. This is an impressive number and I'm curious to know what the scheduler itself was actually worth. Hence, I dug further into Anyscale's report, and found out that Anyscale’s comparison contains at least 3 things : a faster engine, better KV-cache management, and a scheduler that admits new requests between decoding iterations in vLLM. The scheduler is the most interesting and flexible piece, so I built a test where the scheduler was the only variable.
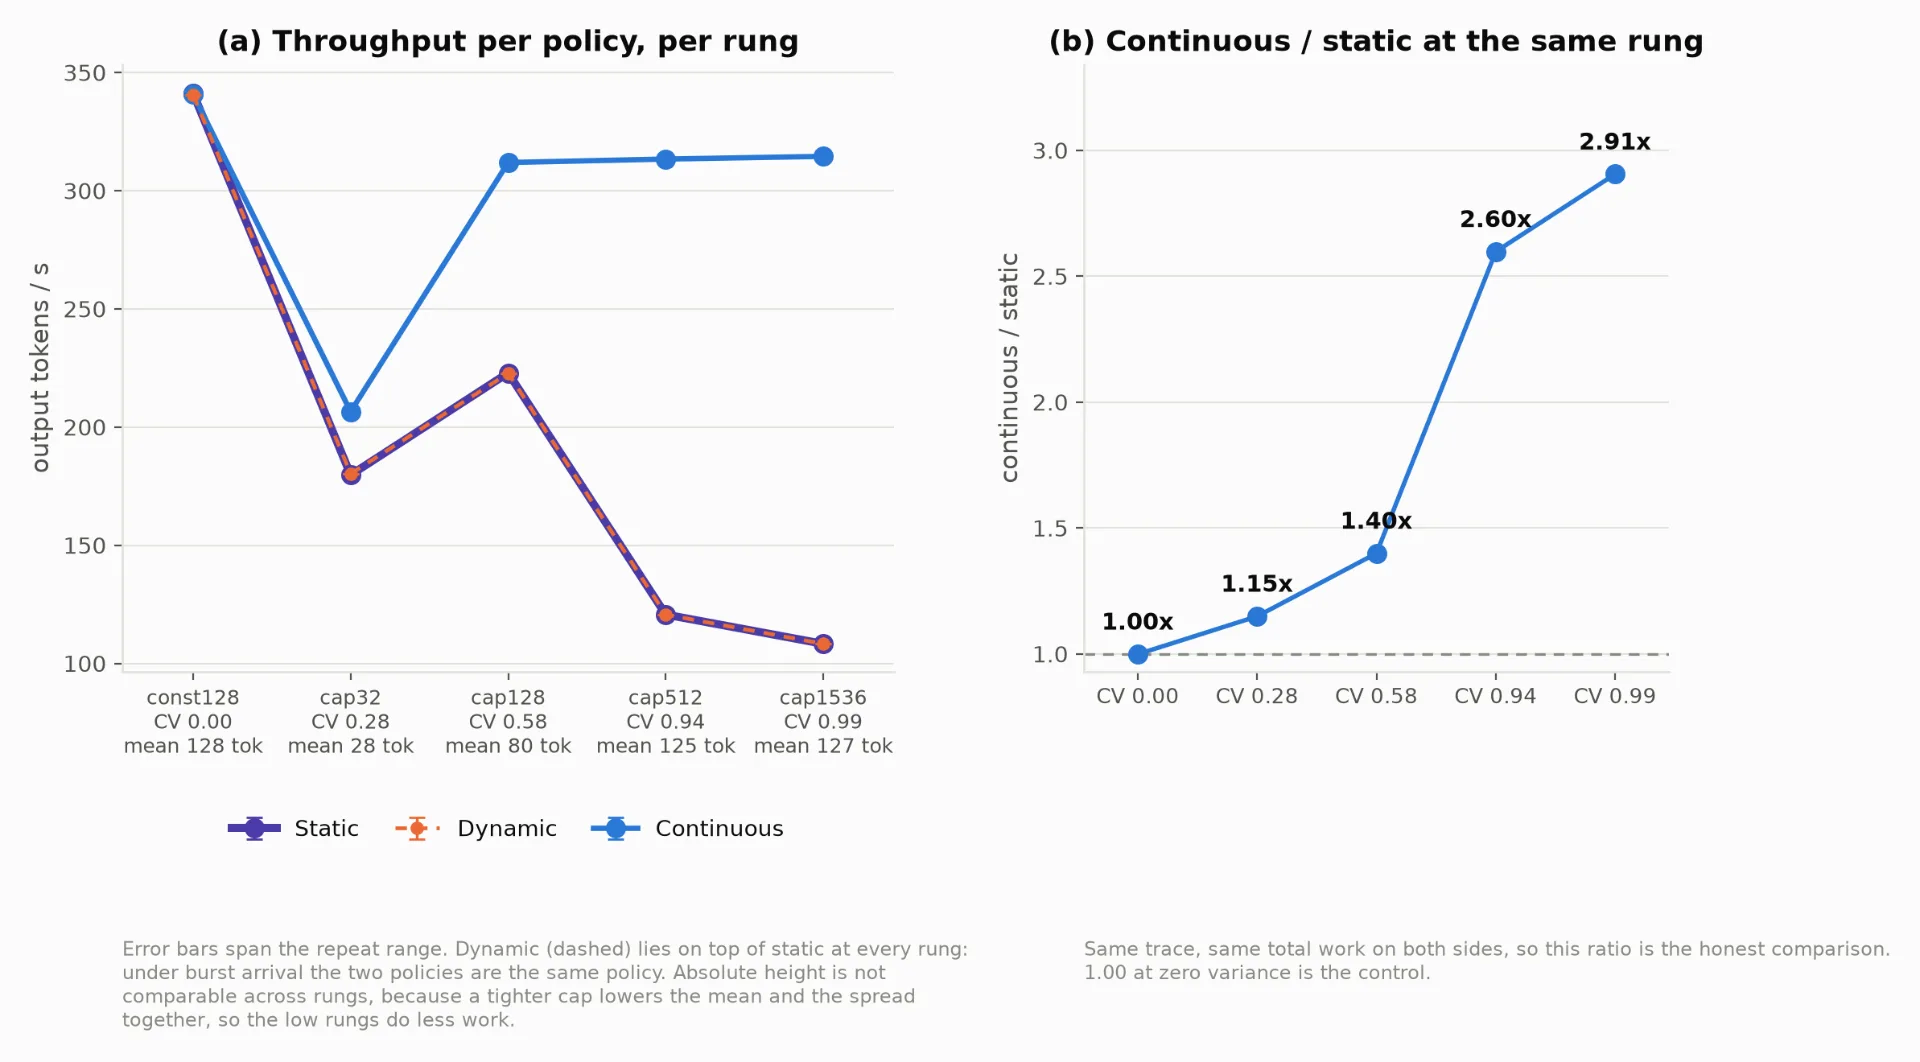
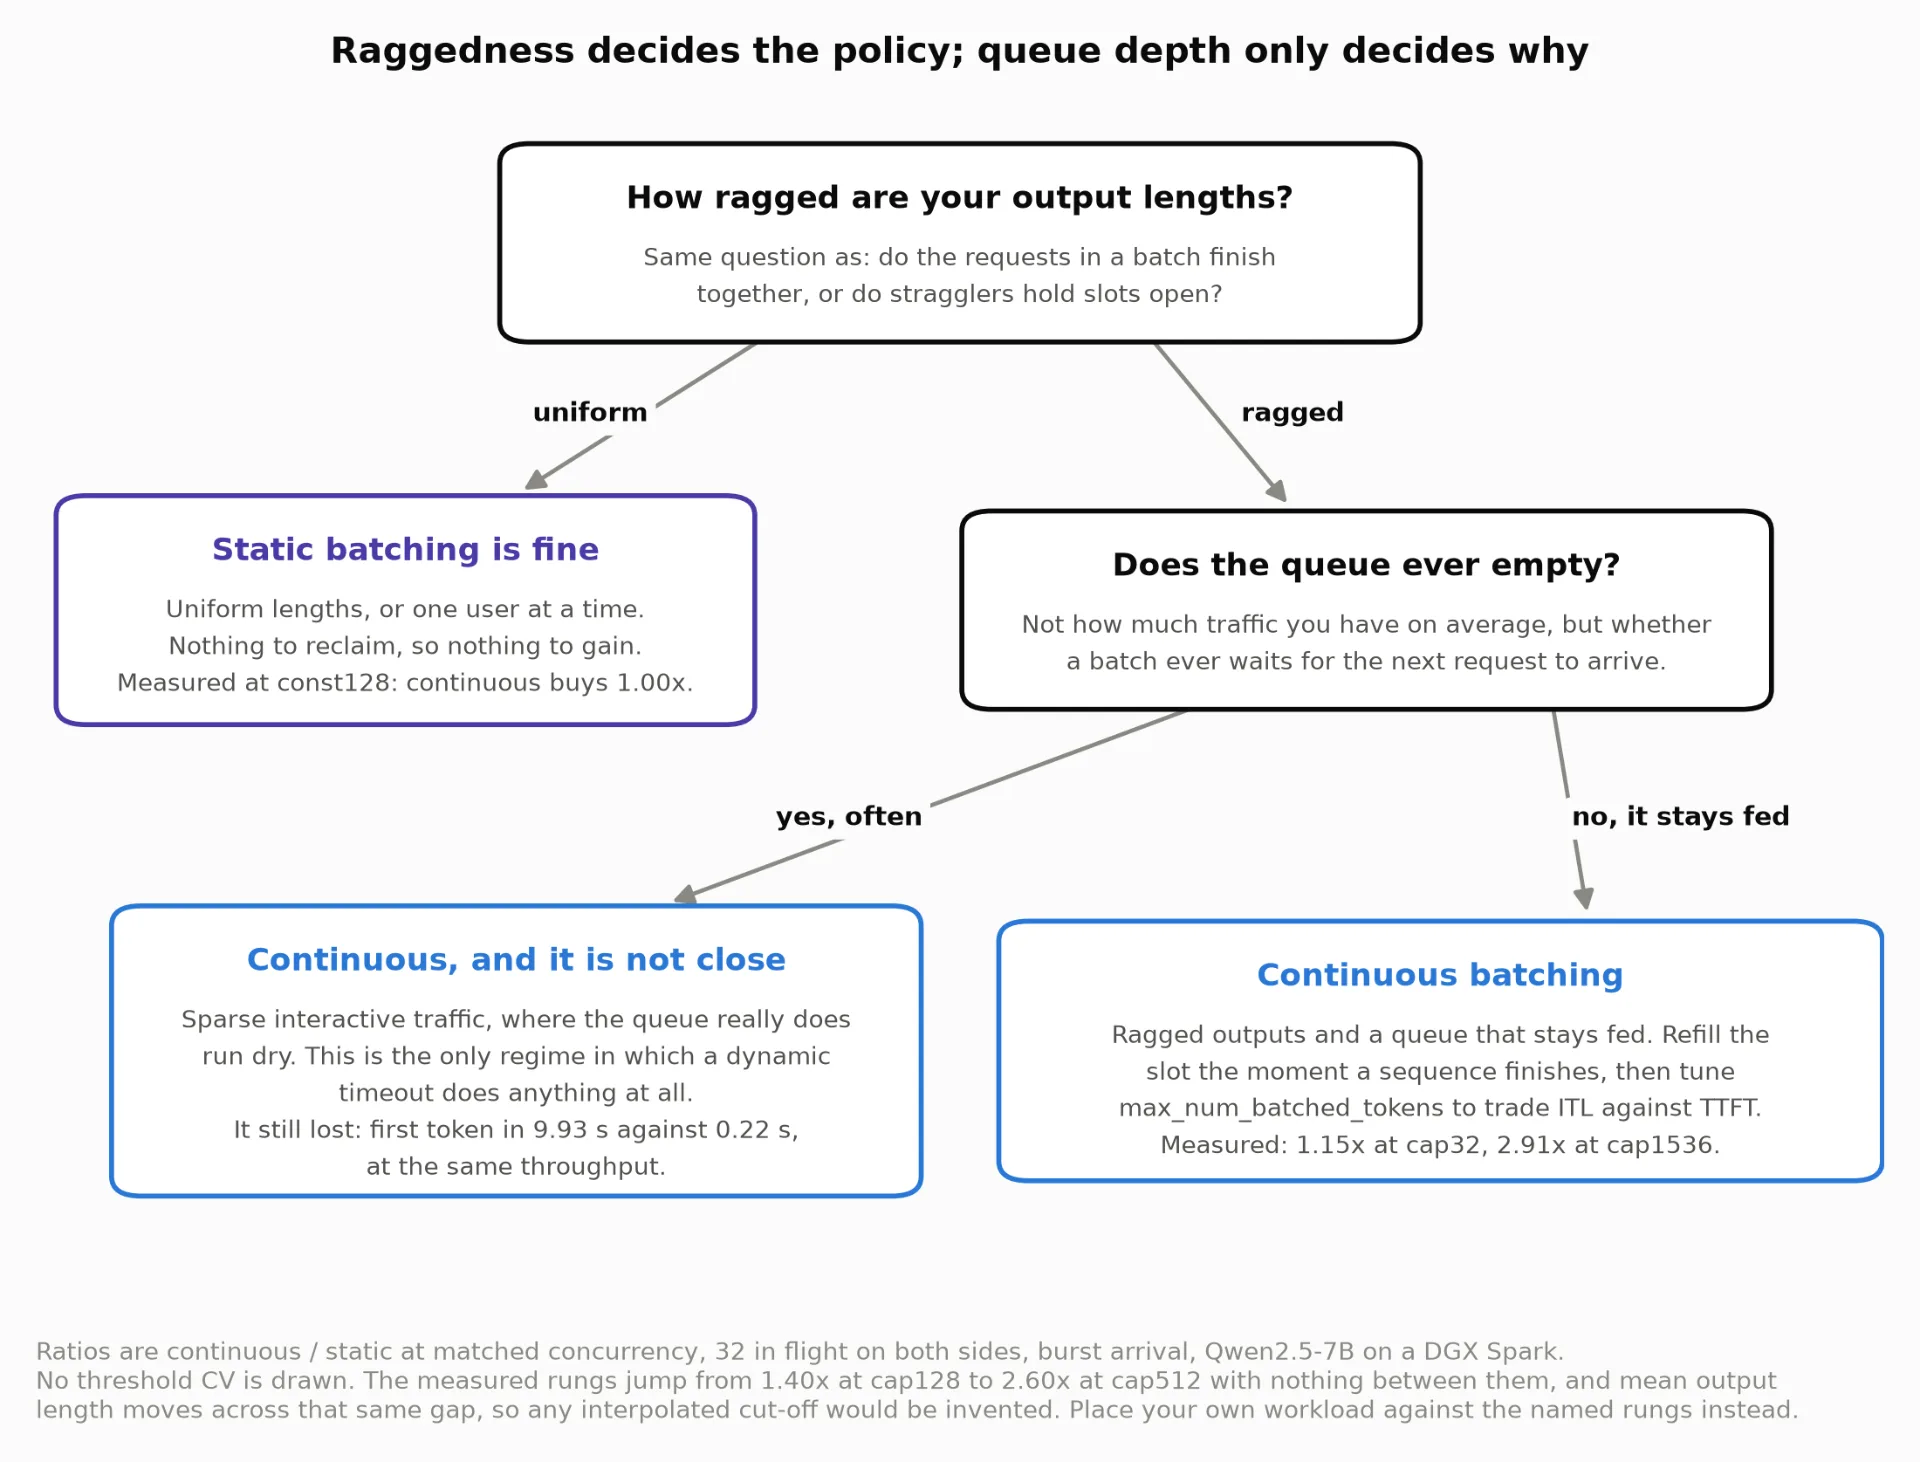
And the result is that the scheduler improved throughput by 2.91× . The engine was worth 1.33× , while the full naive-to-vLLM change measured 3.86× on my hardware. What gave me the most confidence was the control . The control mattered because continuous batching should provide no benefit when every request finishes together.…