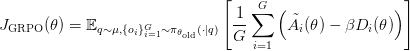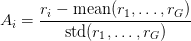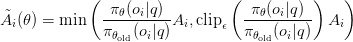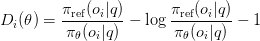Table of Contents
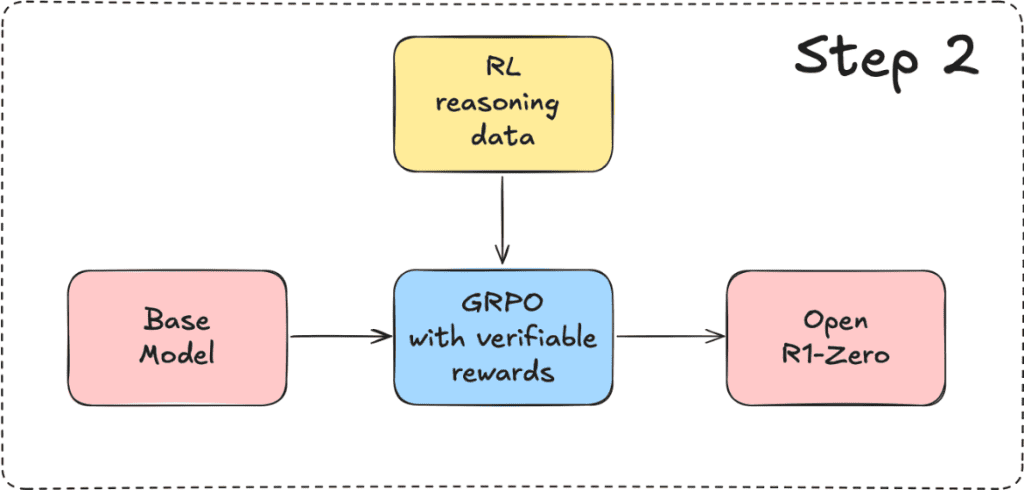
Toward DeepSeek-R1: Building Thinking Models Using GRPO
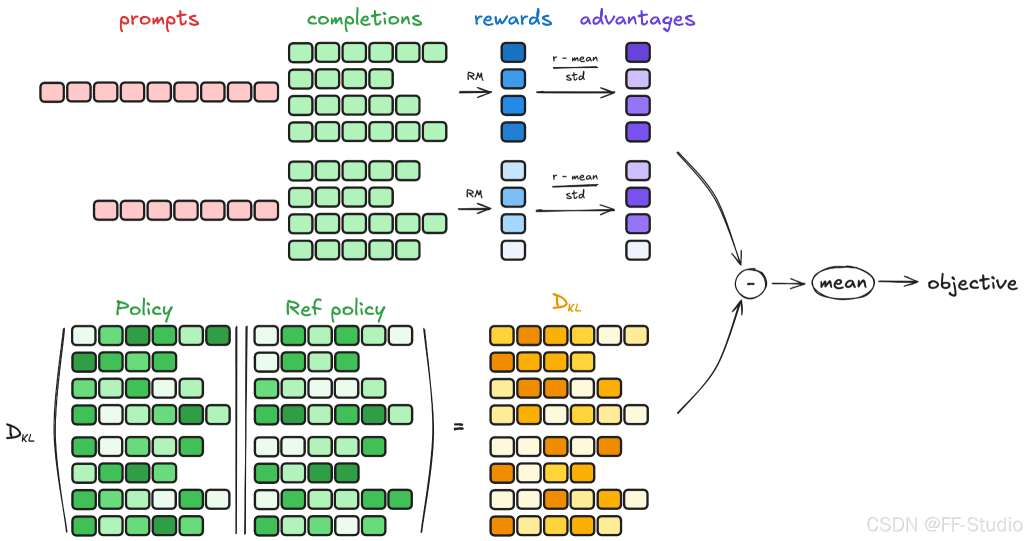
How Group Relative Policy Optimization (GRPO) Works Core GRPO Objective
Group Relative Advantage Estimation
Clipped Surrogate Objective
KL Divergence Regularization
Why GRPO Excels in Mathematical Reasoning Intrinsic Support for Verifiable Rewards
Efficient Learning from Diverse Solution Attempts
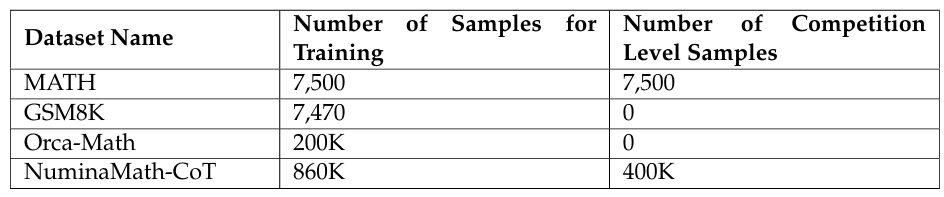
Post-Training Qwen3 for Math Reasoning with GRPO Loading and Exploring the NuminaMath Dataset
Loading Qwen3 and Configuring LoRA
Implementing Verifiable Reward Functions
Training Qwen3 with GRPOTrainer
Summary Citation Information
The journey from DeepSeek‑V3 to DeepSeek‑R1 marks a pivotal shift in how we think about language models: not just as pattern recognizers, but as reasoning agents . While V3 focused on architectural innovations (e.g., multi-head latent attention (MLA), mixture of experts (MoE), and multi‑token prediction (MTP)), R1 introduced a new dimension: the ability to think through problems step by step .…