🖼️00Read later0Read MoreGRPO keeps winning the RL-vs-data argument, and LoRA gets a mechanistic auditDEV Community: deeplearning·Felipe 0liveira·about 3 hours ago#Z9Vc9CJq#devtodeeplearning#education#devto#dev#lora+6 more🧰Tag tools✨Add tagA controlled GRPO-vs-rejection-sampling study, a hidden vocabulary-collapse signal in DPO, and new LoRA internals and infra tricks.15s
🖼️00Read later0Read MoreWhat is GRPO, and how do you run GRPO training on GPUs?DEV Community: deeplearning·Viswaretas Kotra·about 15 hours ago#8OEnzOIO#devtodeeplearning#education#devto#dev#grpo+7 more🧰Tag tools✨Add tagGRPO trains an LLM by scoring groups of sampled answers against each other, with no critic model. How it works, memory math for 8B, and how to run it.15s
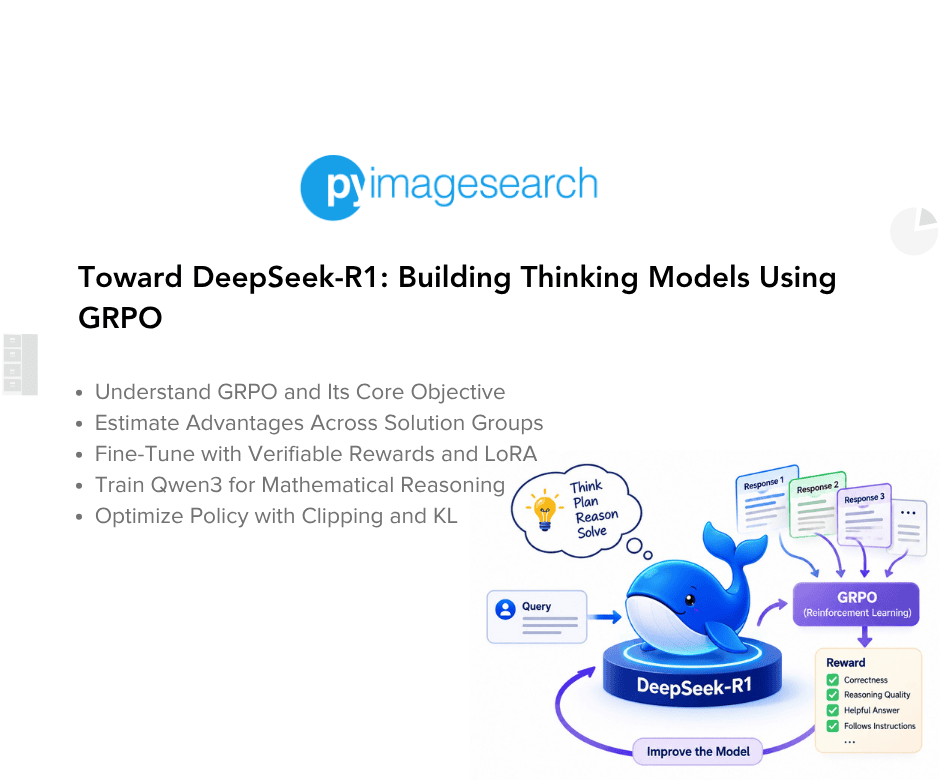
🖼️00Read later0Read MoreToward DeepSeek-R1: Building Thinking Models Using GRPO - PyImageSearchPyImageSearch·Puneet Mangla·6 days ago#Npvp8h0w#pyimagesearch#grpo#model#reward#training+5 more🧰Tag tools✨Add tagFine-tuning Qwen3 for advanced math reasoning using GRPO: boosting precision, structure, and problem-solving accuracy post-training.15s
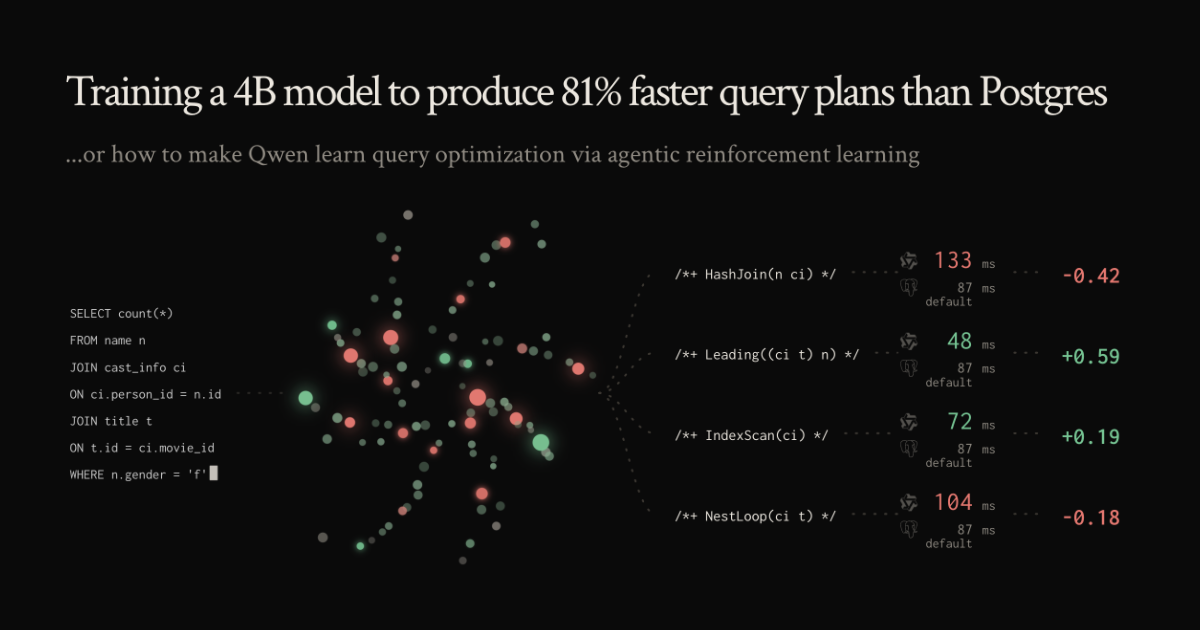
📰00Read later0Read MoreTraining a 4B model to produce 81% faster query plans than PostgresHacker News·about 1 month ago#ut6JOjZ2#rohanbansal#postgres#grpo#article#ama+1 more🧰Tag tools✨Add tag...or how to make Qwen learn query optimization via agentic reinforcement learning15s
🖼️00Read later0Read MoreRRCM Uses GRPO to Decide When to Retrieve for LLM RecommendationDEV Community·gentic news·6 months ago#kuoB6L8h#ai#machinelearning#research#deeplearning#rrcm+7 more🧰Tag tools✨Add tagRRCM uses GRPO to learn when to retrieve evidence for LLM recommendation, outperforming fixed-context baselines.15s