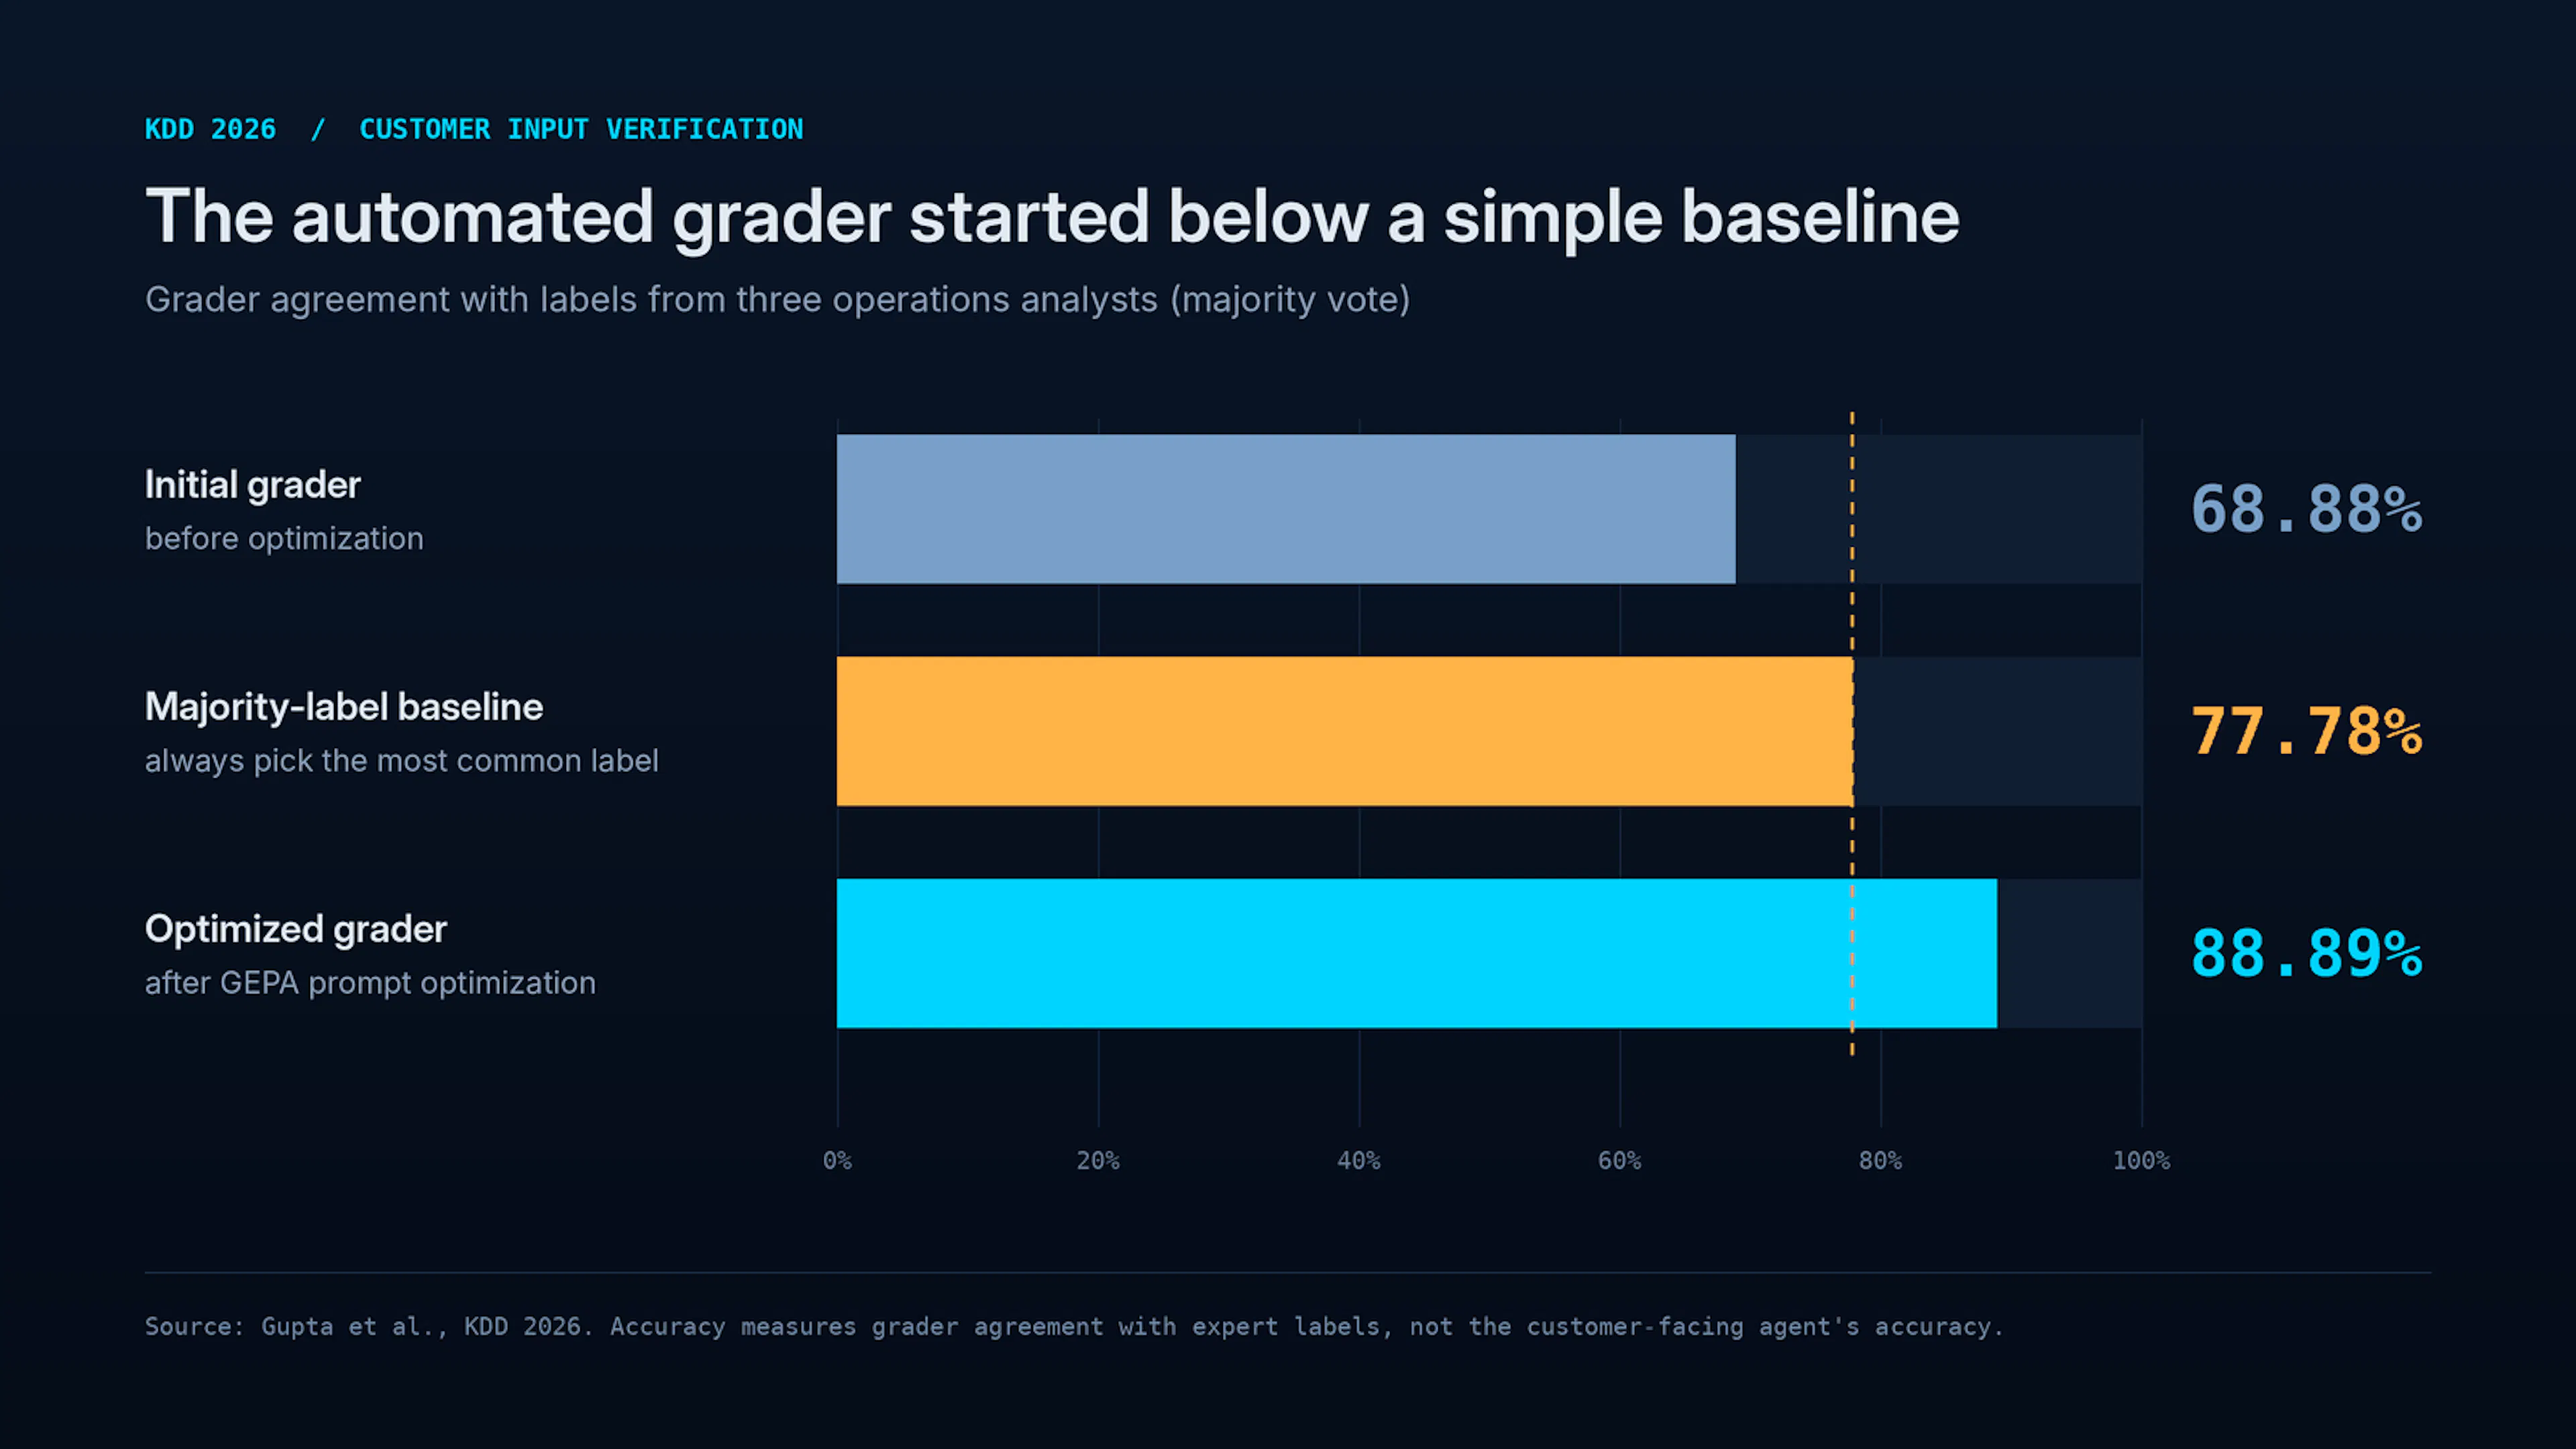
TL;DR : A KDD 2026 paper follows five customer support AI agents through testing and deployment. The team checks automated graders against expert judgments, starts new versions at 1% to 5% exposure, and tracks whether satisfaction gains come with more self-service or more work for human agents.
An automated grader can give an AI agent a passing score and still be wrong. In a June 2026 paper accepted to ACM’s KDD 2026 conference , engineers at a digital bank report that one grader initially performed worse than simply choosing the most common answer. Before relying on it to evaluate customer-facing agents, they had to improve the evaluator itself.
The paper describes how a bank serving more than 100 million users tests agentic AI in production across card delivery, debt management, credit limits, card management and product explanation.…