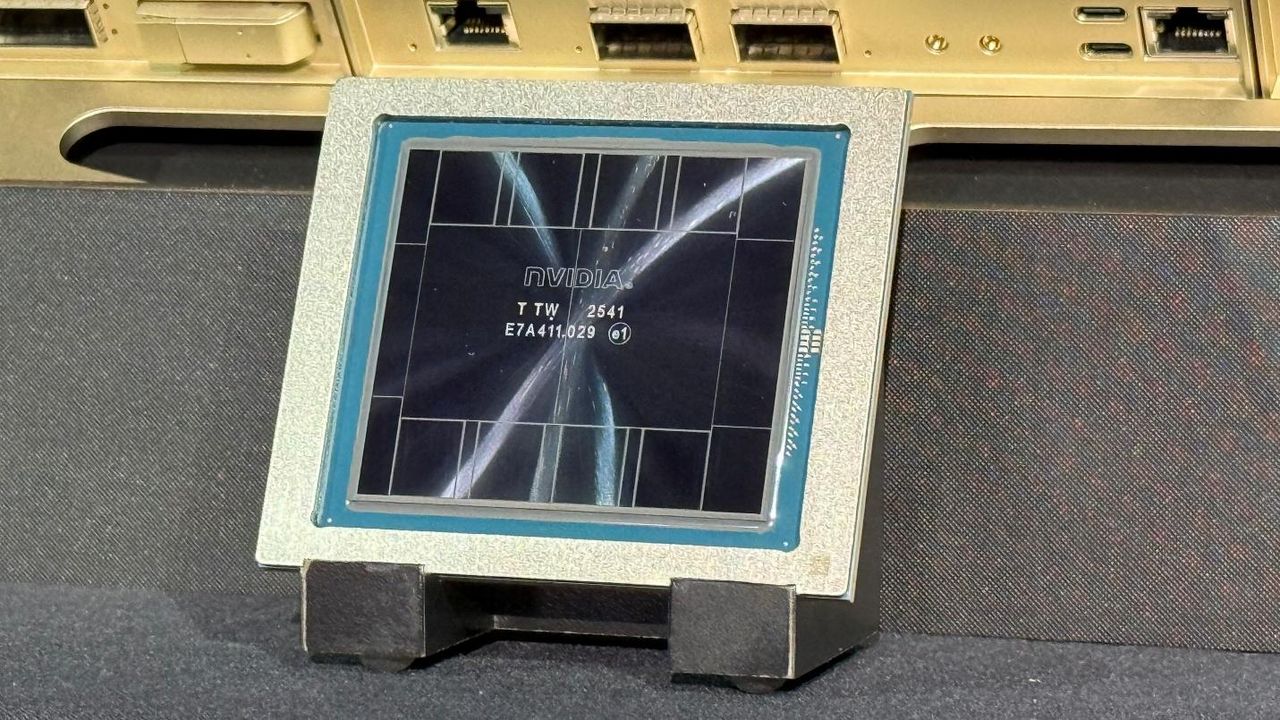
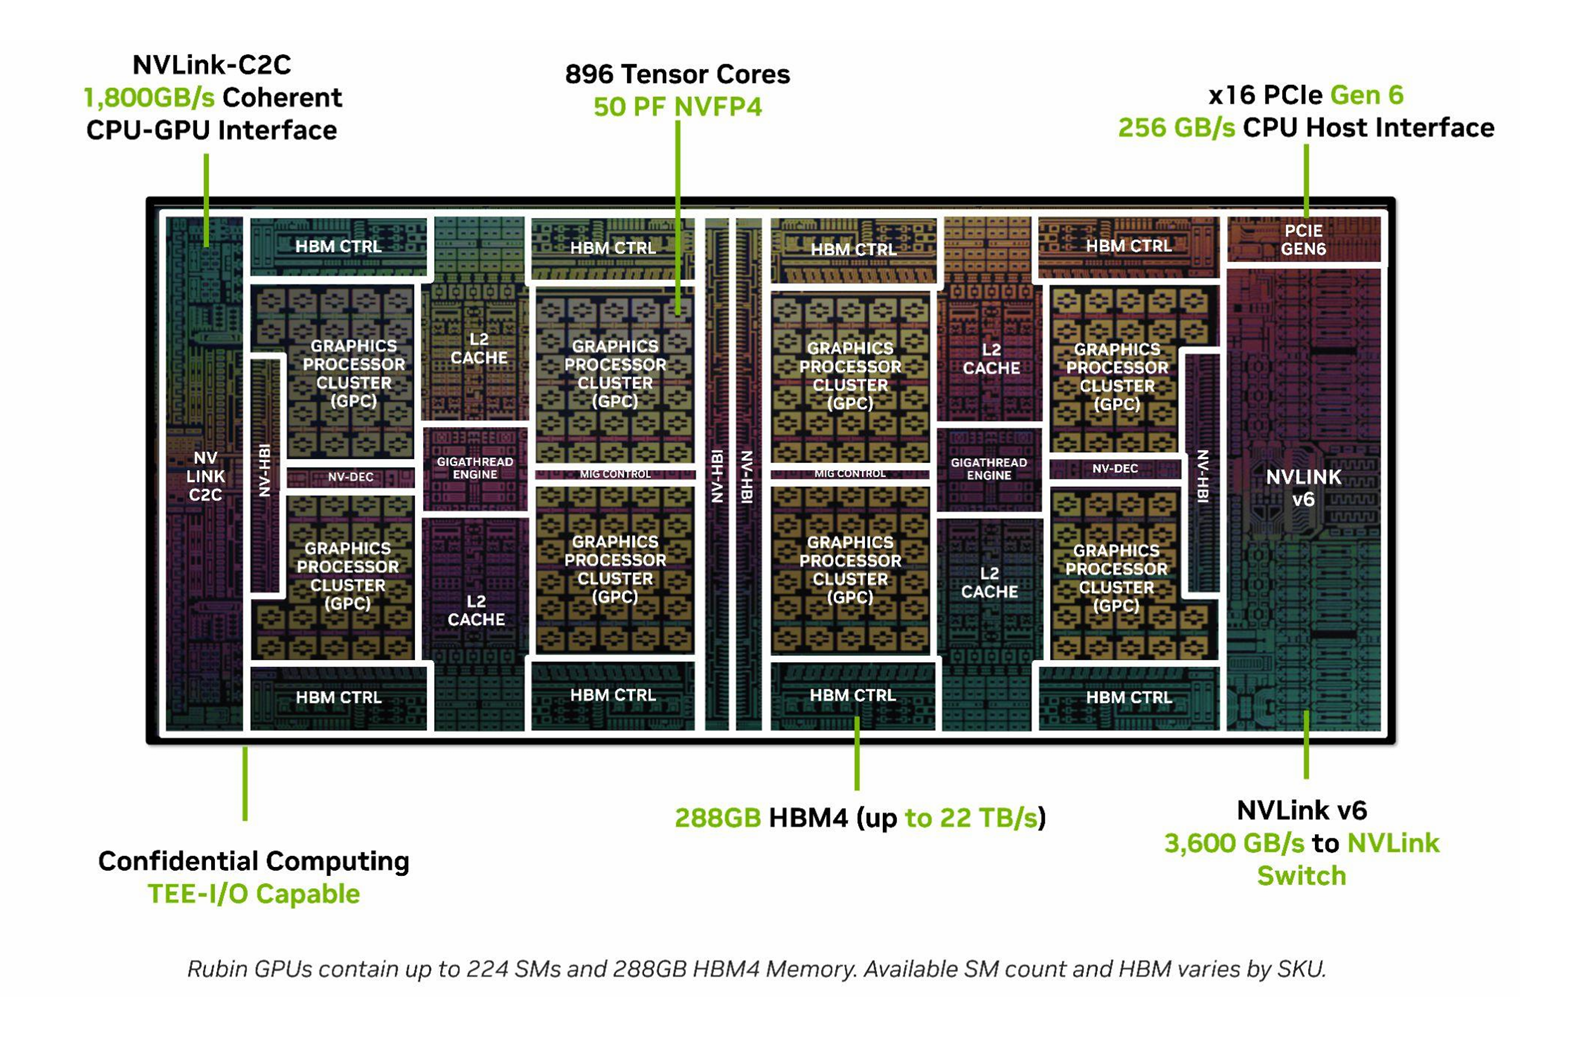
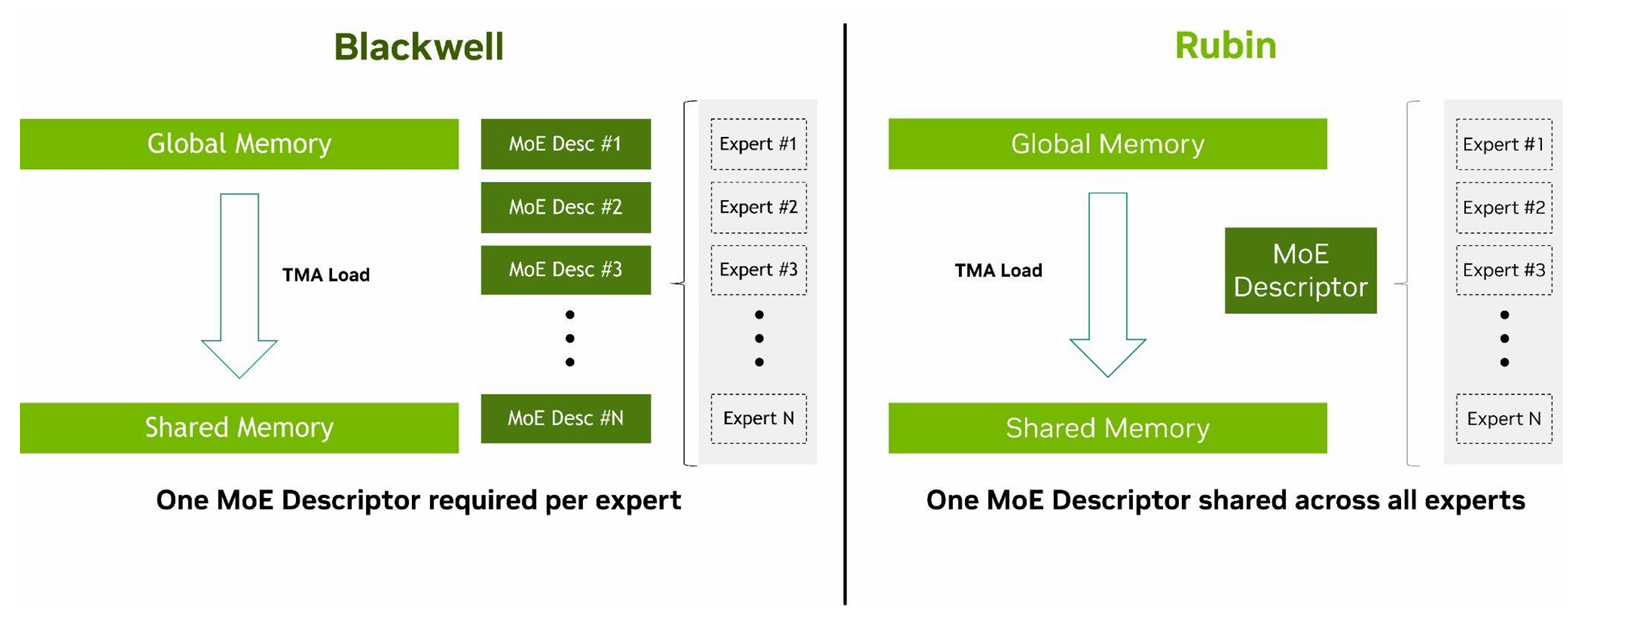
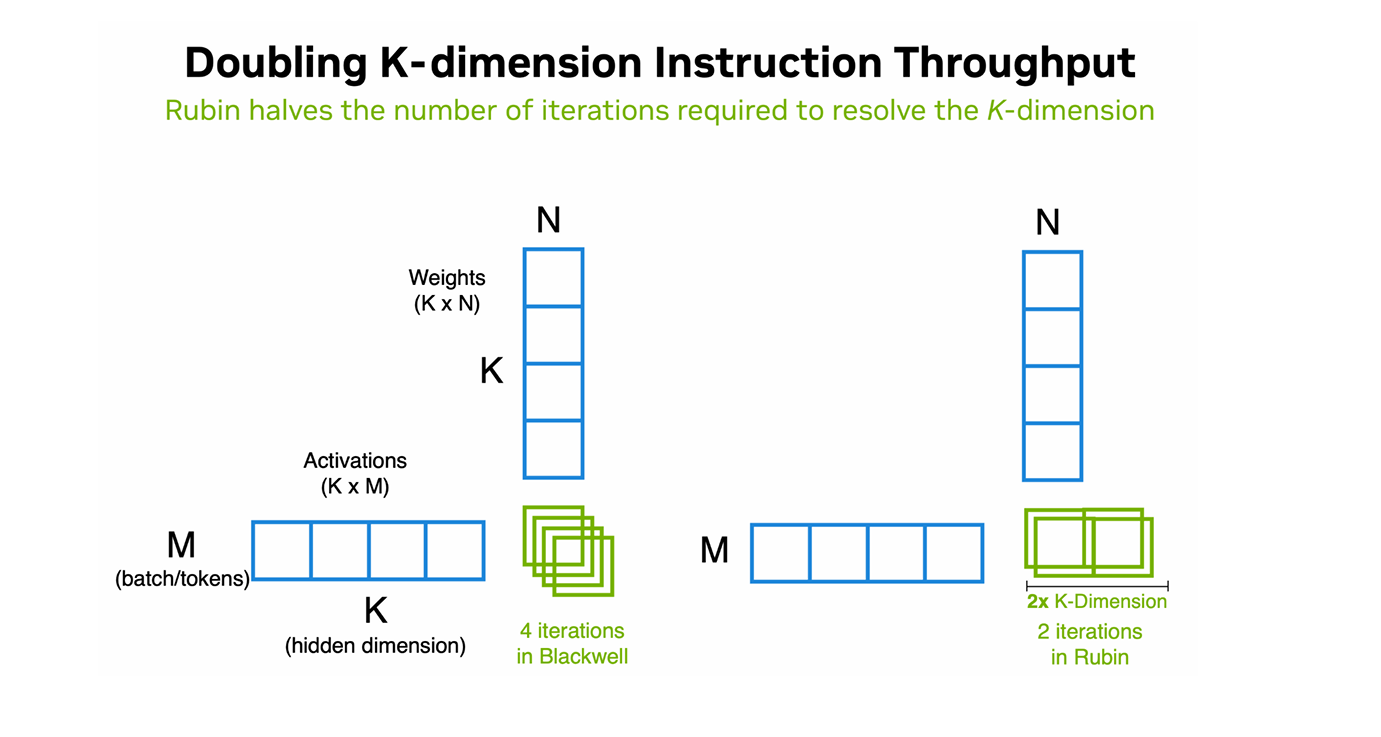
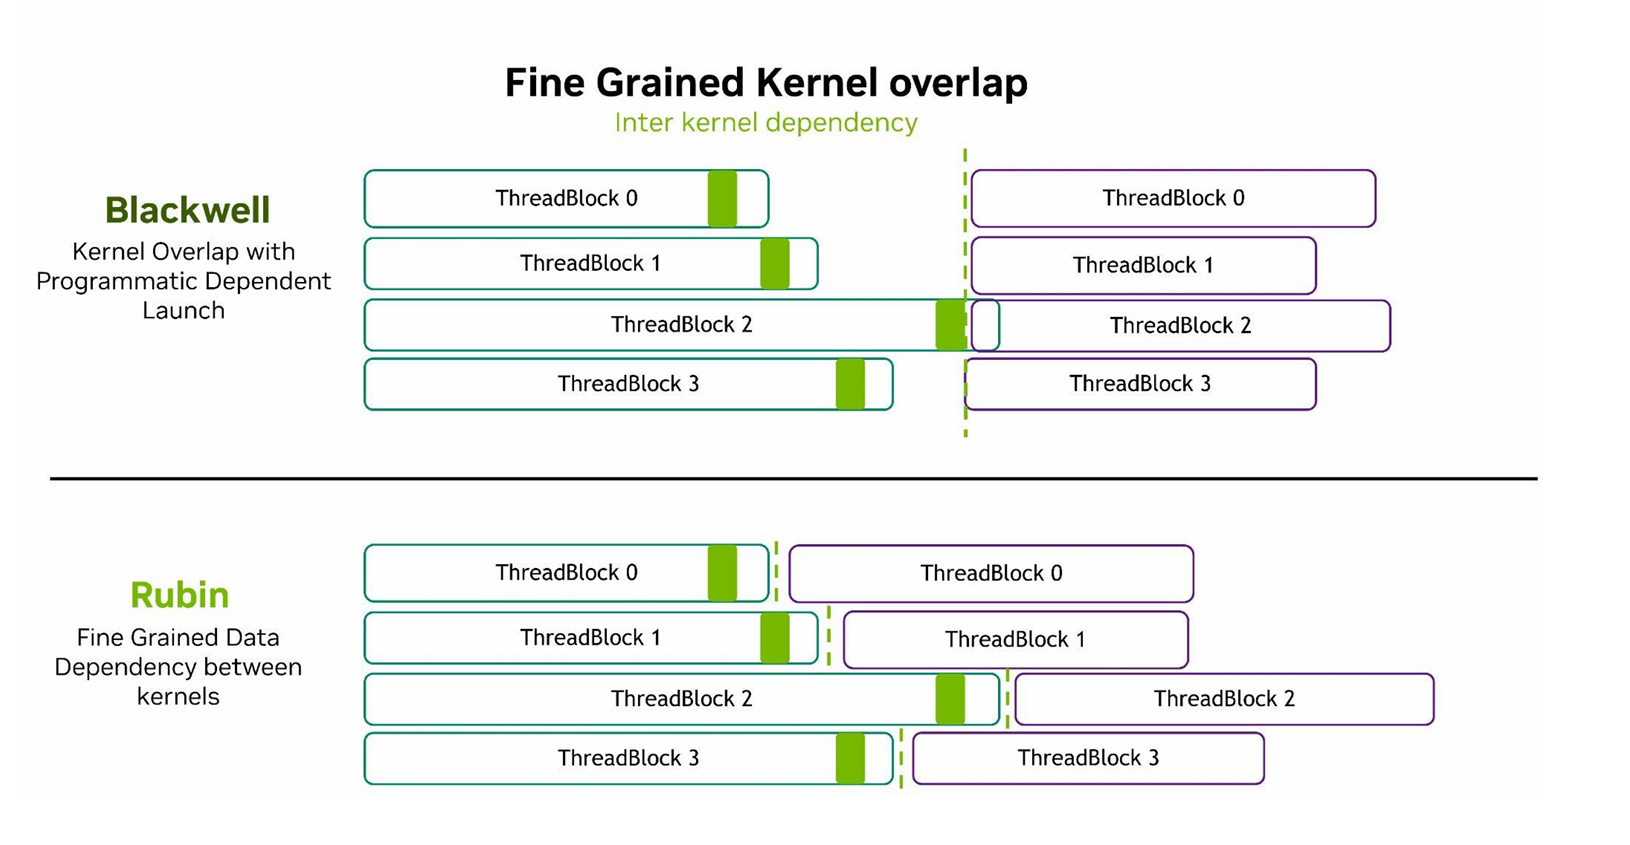
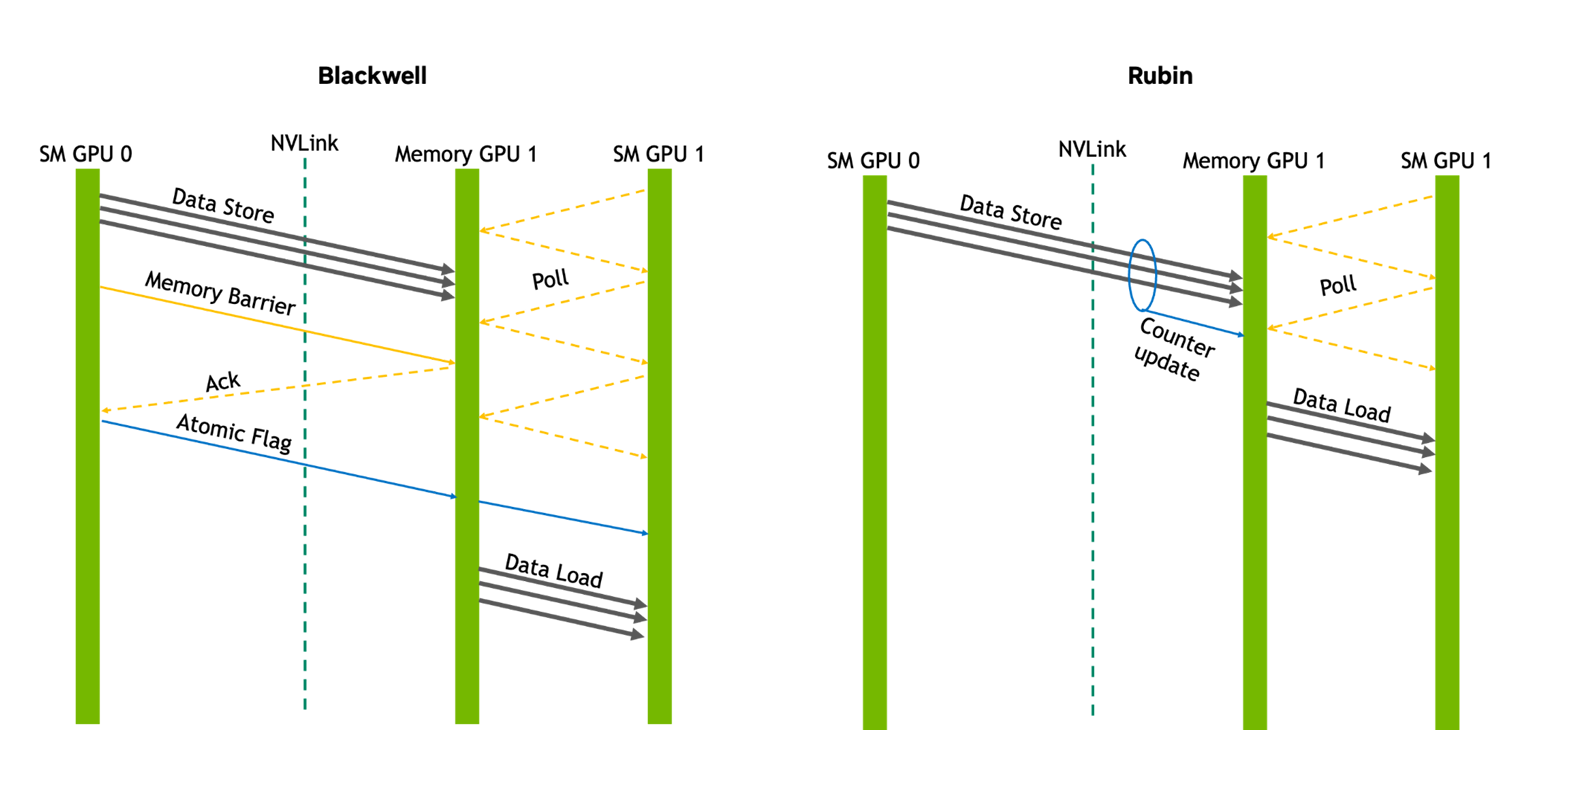
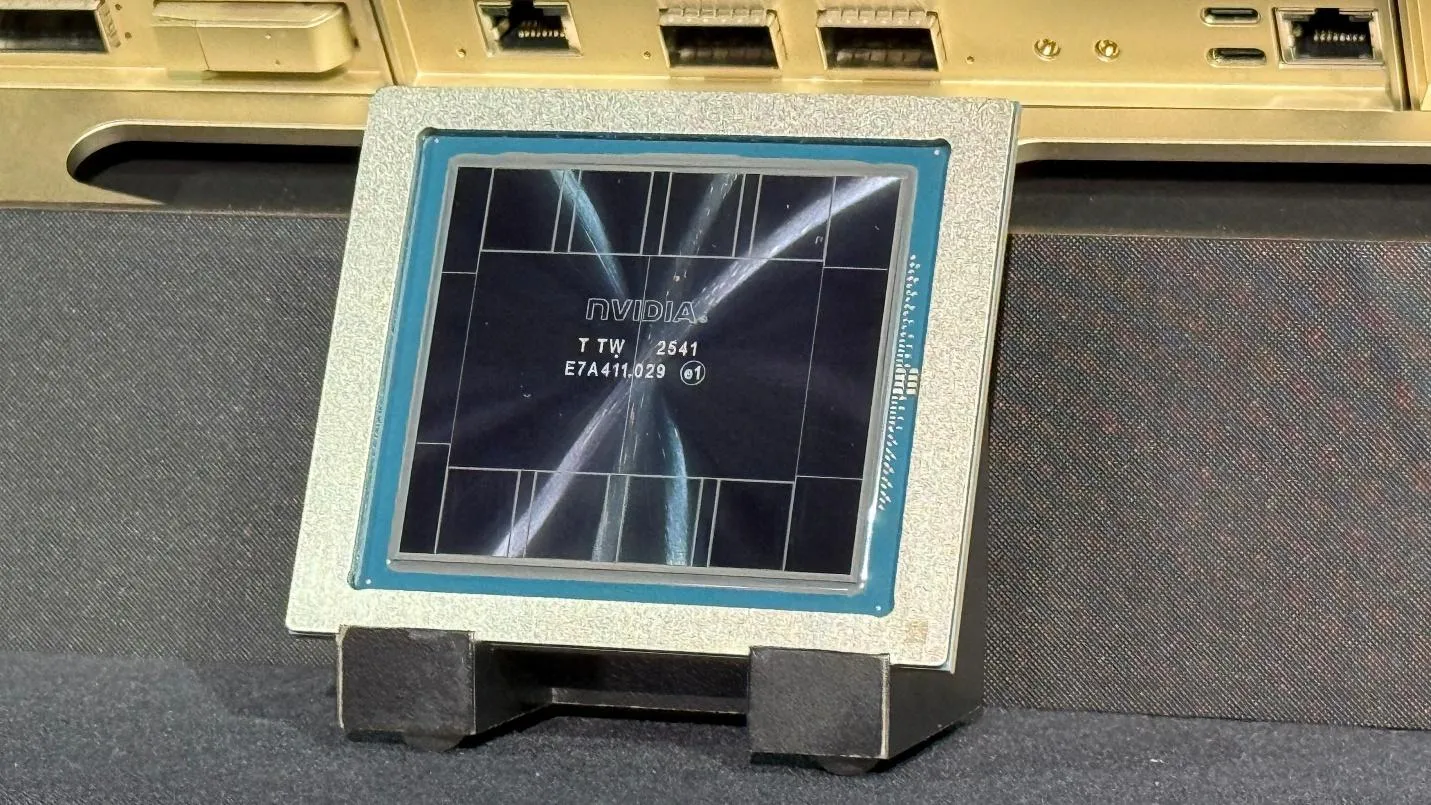
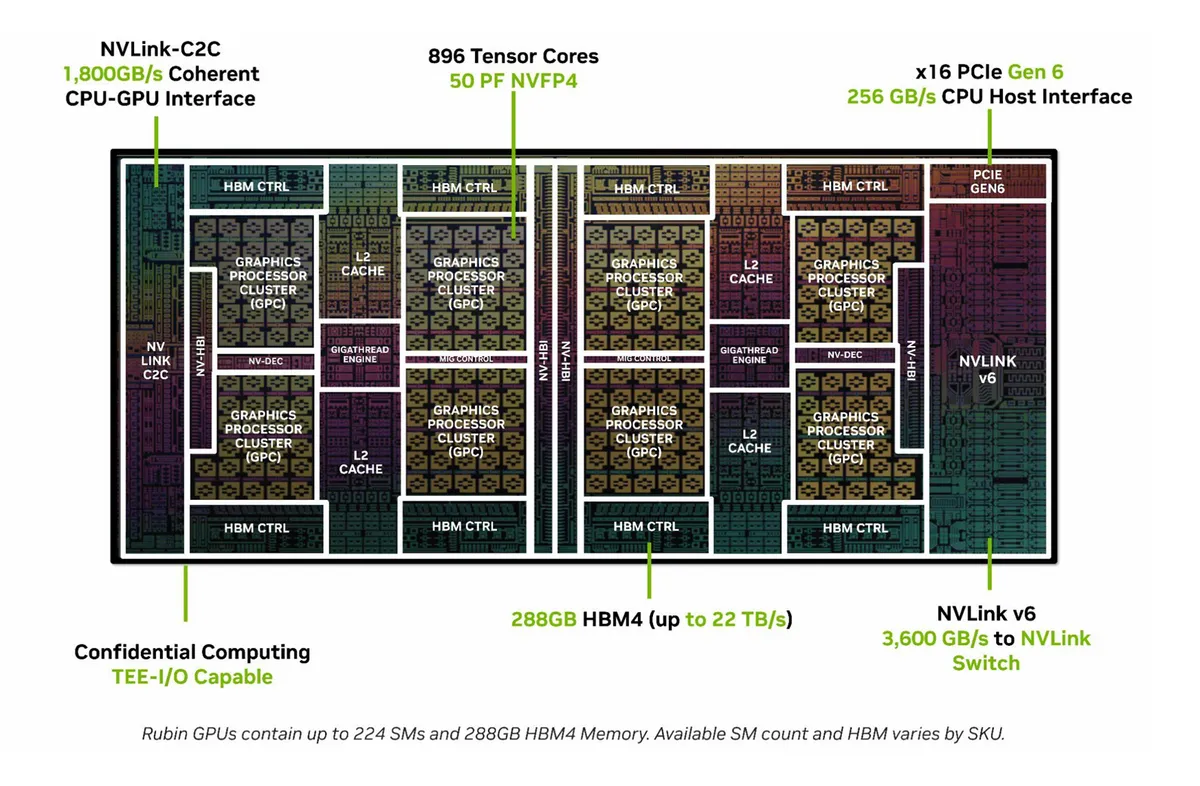
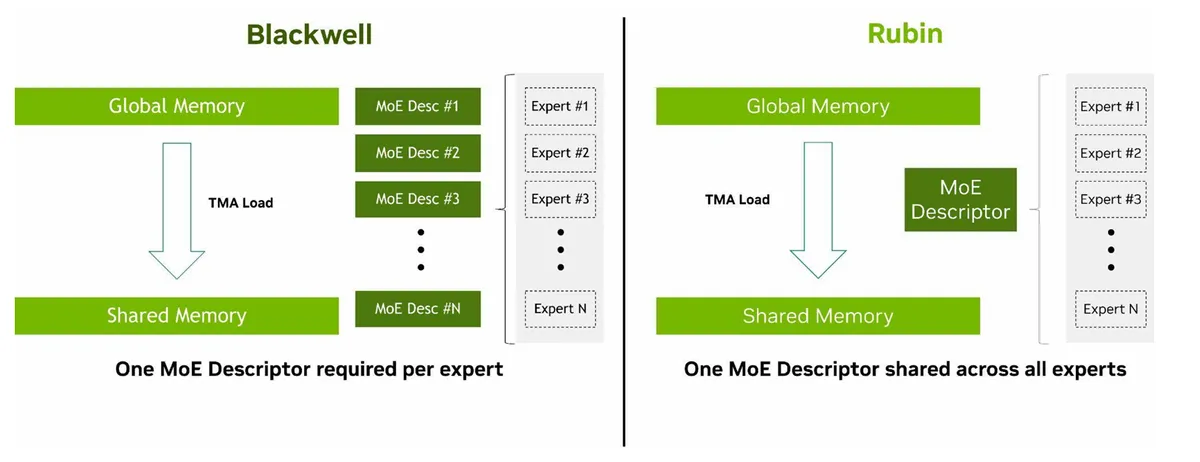
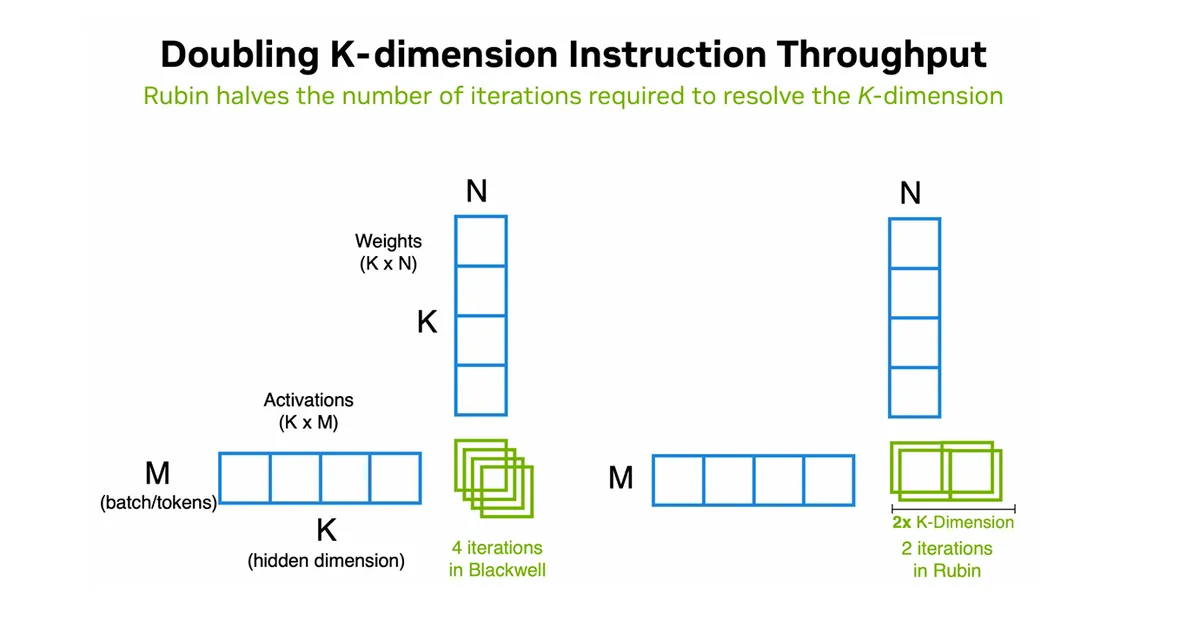
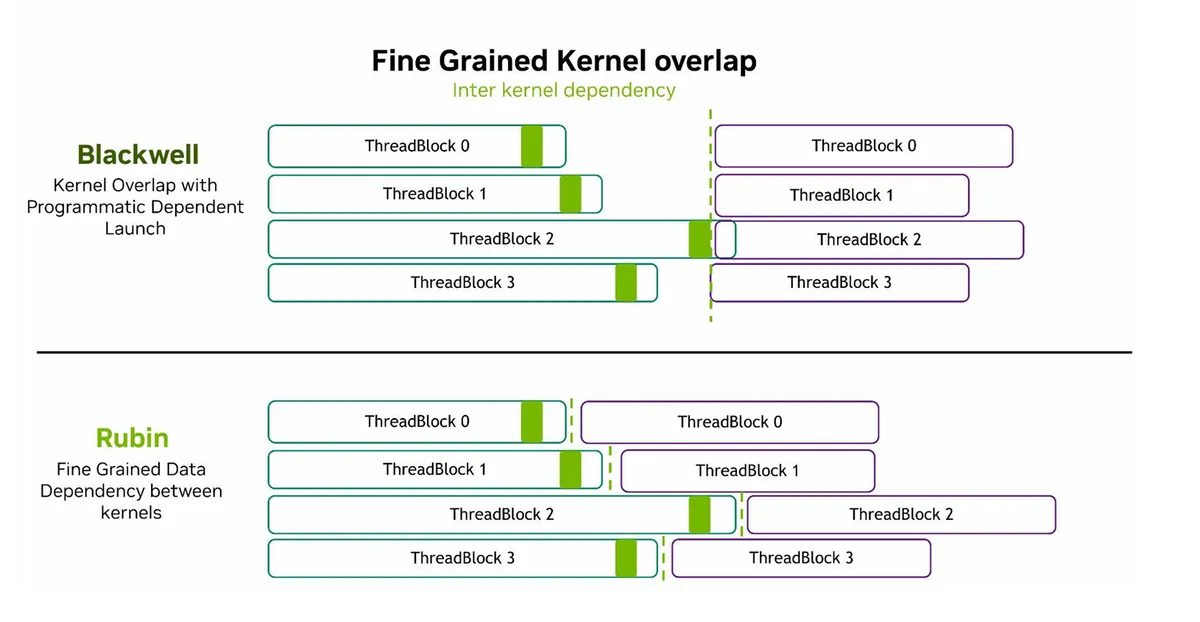
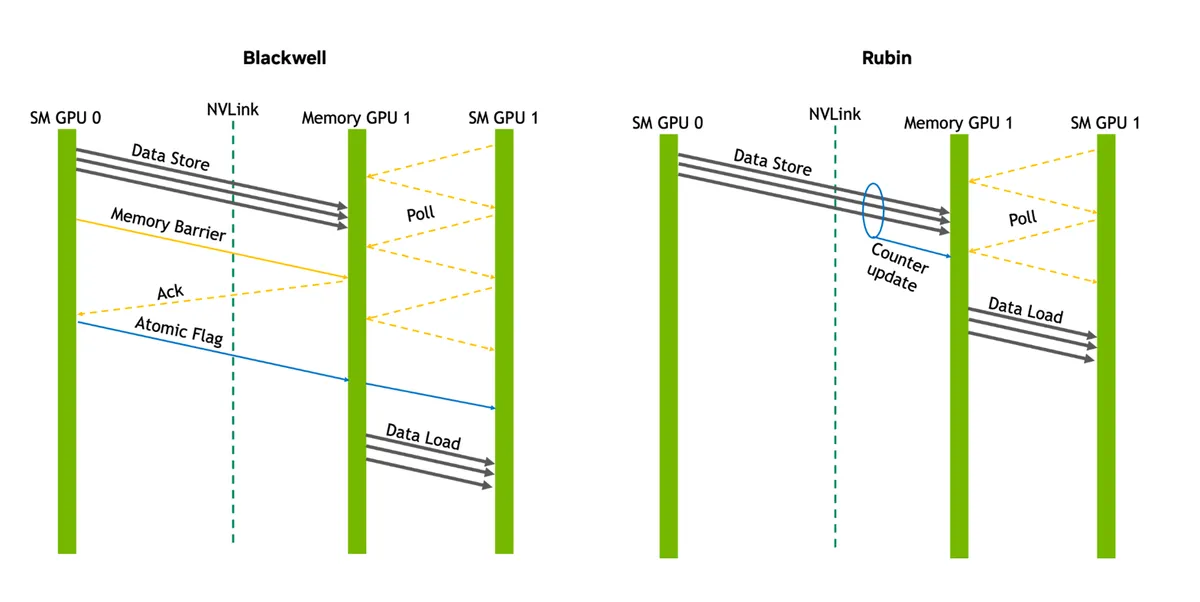
(Image credit: Future) Nvidia's upcoming Vera Rubin platform, set to arrive later this year, will take the stage as the AI world shifts towards an era dominated not by frontier training runs but by the demands of agentic AI inference at massive scale. The hunger for generated tokens in agentic workflows and the demands of delivering them quickly, efficiently, and at low unit cost now dominate the discussion. We’ve already gone in depth on new performance data around the Vera CPU and how it helps to accelerate agentic AI workloads, but that’s not all Nvidia is sharing today. It’s also detailing some new features of the Rubin architecture and how those features are meant to increase inference efficiency from the GPU level to rack-scale and data-center-scale implementations of this accelerator platform. (Image credit: Nvidia) The full Vera Rubin NVL72 rack-scale system is built up from 36 Vera CPUs and 72 Rubin GPUs, but our focus today is on the GPU proper.…