Menu

#Inference

178 posts

Feed·
20 of 178 posts
Why your local LLM feels dumber than it is
🖼️
508

Why your local LLM feels dumber than it is

Hacker News·about 1 month ago
#WSJJzj1r

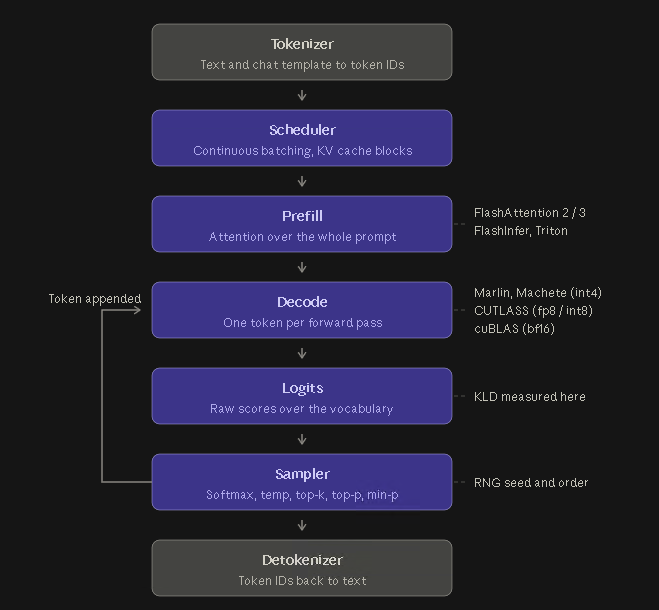
Quick Introduction We have all been on forums, chats, reddit, discord, youtube, or somewhere and heard “Oh! Model XYZ is AMAZEBALLZ!zomgwtfbbq” then downloaded it (or more likely, some quantized form of it) and said “eww… This sucks!” This post is going…

15s
Read More
Autoregressive Language Model on the 6502 Processor
🖼️
0

Autoregressive Language Model on the 6502 Processor

Hacker News·2 months ago
#8h6ZogMM

A language model on a 1975 MOS 6502 processor, using a tiny Mamba-based language model and custom 8-bit ternary inference engine, used to generate text on a BBC Micro from the 1980s.

15s
Read More
Member of Technical Staff at Morph | Y Combinator
🖼️
0

Member of Technical Staff at Morph | Y Combinator

Hacker News·2 months ago
#ejdVz99m

The best candidates would be top 1% at multiple parts of the inference stack. work on PD disaggregation research Morph builds the inference infrastructure behind the fastest open models.…

15s
Read More
Ultralytics YOLO26: Unified Real-Time End-to-End Vision Models
🖼️
55

Ultralytics YOLO26: Unified Real-Time End-to-End Vision Models

Hacker News·4 months ago
#brdwMjx8

Real-time vision demands models that are accurate, efficient, and simple to deploy across diverse hardware. The YOLO family has become widely deployed for this reason, yet most YOLO detectors still rely on non-maximum suppression at inference, carry heavy…

15s
Read More
AI cryptomining network's 320,000 RTX 3090-class GPUs allegedly burn 112 megawatts of power on ‘zero useful AI computation’ — GPU rental costs jump 38%, but Pearl’s cards are doing random matrix math, study claims
🖼️
0

AI cryptomining network's 320,000 RTX 3090-class GPUs allegedly burn 112 megawatts of power on ‘zero useful AI computation’ — GPU rental costs jump 38%, but Pearl’s cards are doing random matrix math, study claims

The mining protocol does not verify whether work came from real AI training or inference workloads.

15s
Read More
Why Your Local LLM Setup Is Costing More Than You Think — And What Happens When It Breaks
🖼️
0

Why Your Local LLM Setup Is Costing More Than You Think — And What Happens When It Breaks

DEV Community·xu xu·4 months ago
#XoJWHCQa
#dev#local#inference#model#ollama#teams

You're three hours into debugging a model quantization issue. The GPU utilization is sitting at 12%....

15s
Read More
After Nvidia's $20B not-acqui-hire, AI chip startup Groq reportedly raising $650M | TechCrunch
🖼️
0

After Nvidia's $20B not-acqui-hire, AI chip startup Groq reportedly raising $650M | TechCrunch

TechCrunch·Dominic-Madori Davis·4 months ago
#moNUXX32
#apple#amazon#cloudcomputing#evs#google#groq

Chipmaker Groq is looking to raise $650 million in internal funding as it pivots from hardware to focus more on AI inference, the process of refining the way AI models respond to prompted requests, per Axios.

15s
Read More