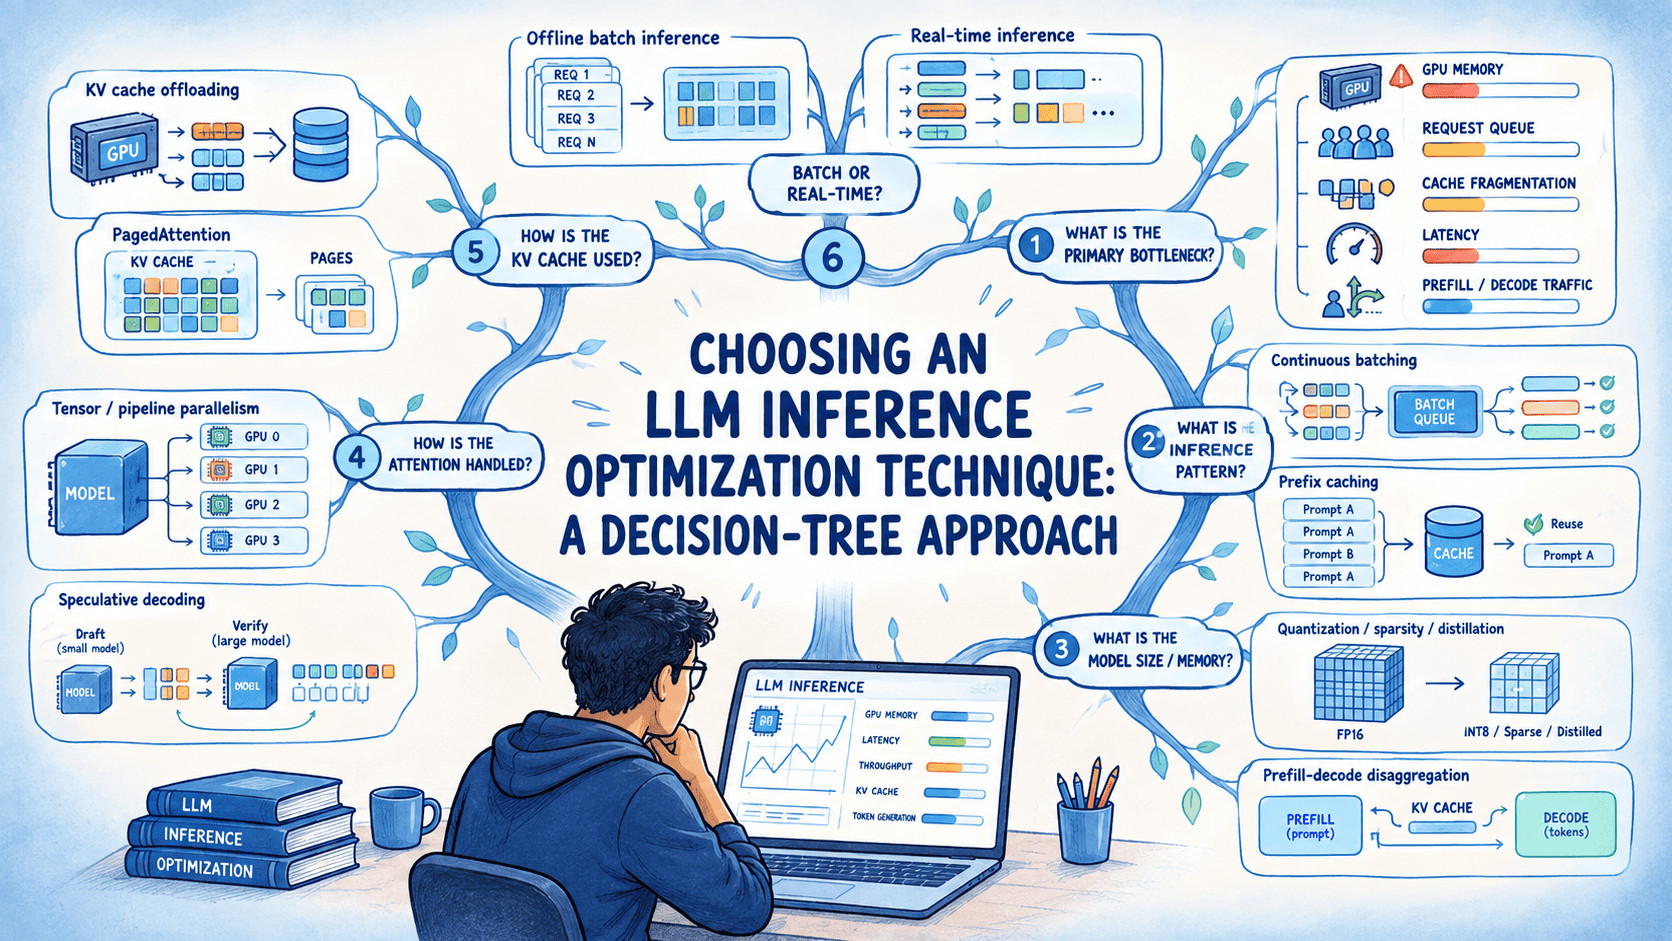
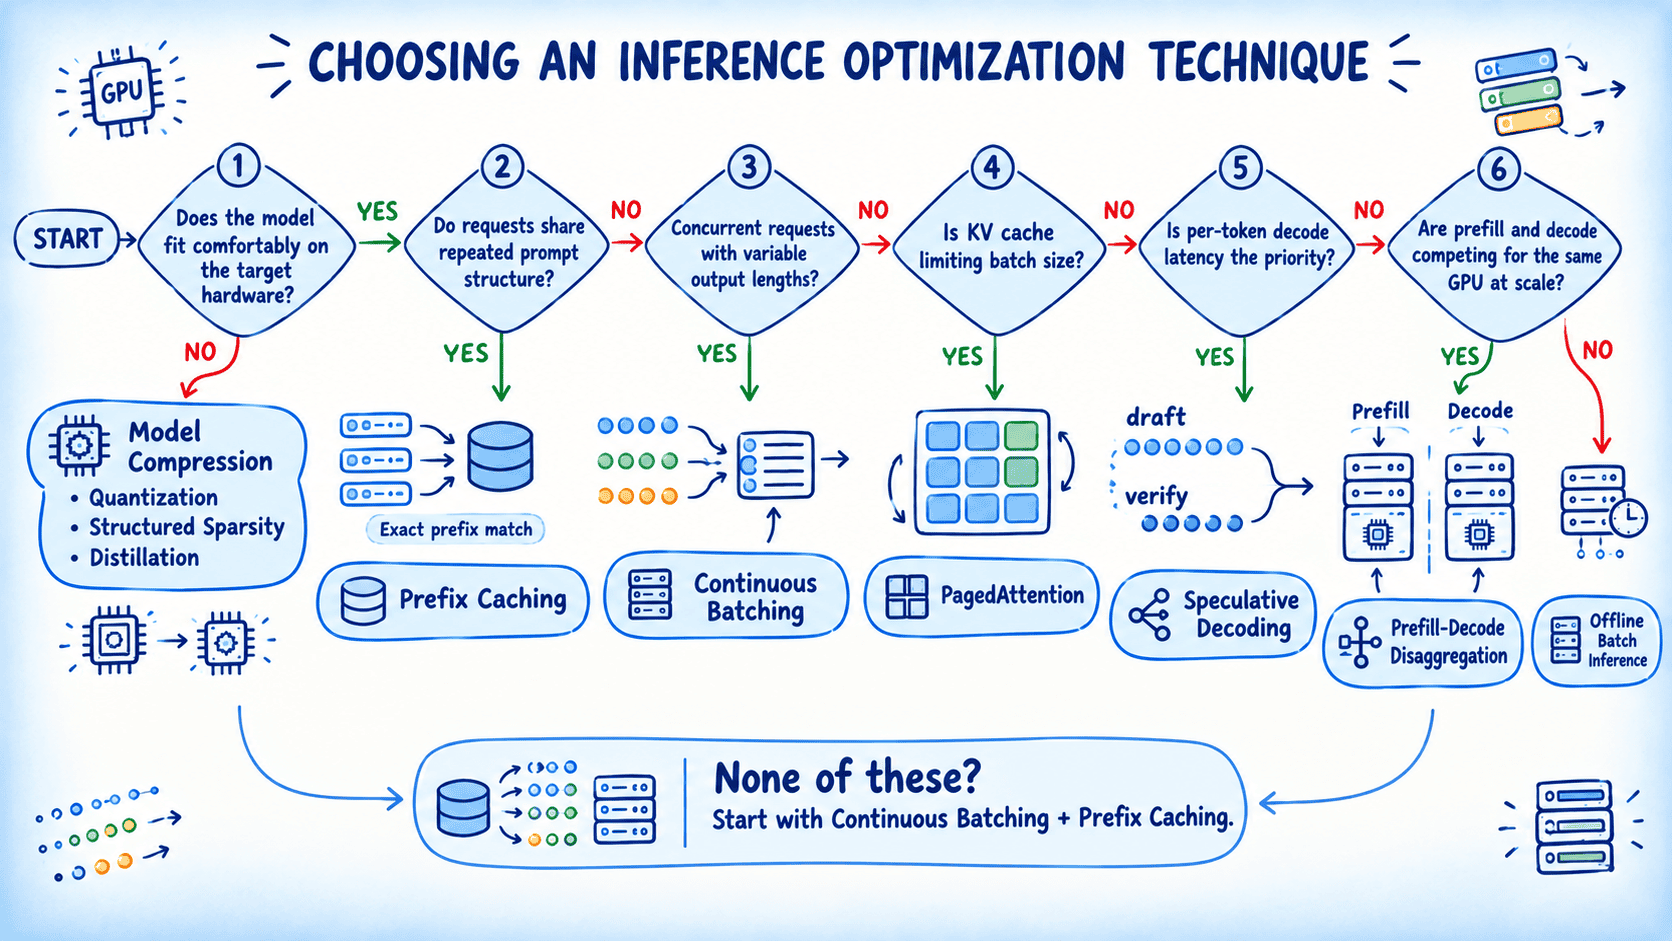
In this article, you will learn how to match an LLM inference optimization technique to the actual bottleneck in your workload by working through a six-question decision tree.
Topics we will cover include:
What each major inference optimization technique, from quantization to prefill-decode disaggregation, assumes about your workload.
How to work through a decision tree that routes you to the right technique based on your model and traffic.
How the techniques compare on trade-offs, and which symptoms show that a chosen technique isn’t working.
Introduction
LLM inference gets slow and expensive as traffic grows. Requests queue behind long generations, GPU memory fills with cached attention state, and the hardware spends much of its time waiting on memory reads.
Inference optimization is the set of techniques that help here. Some techniques target memory, some target compute, and some target how requests are scheduled against each other.…