But anyone paying attention to the world of AI developments will recognize that we’ve become quite successful at tuning billions of parameters in neural networks, in part through a mathematical technique called gradient descent. And, because this is central to training large neural networks, people have put a lot of work into optimizing the performance of gradient descent on GPUs.
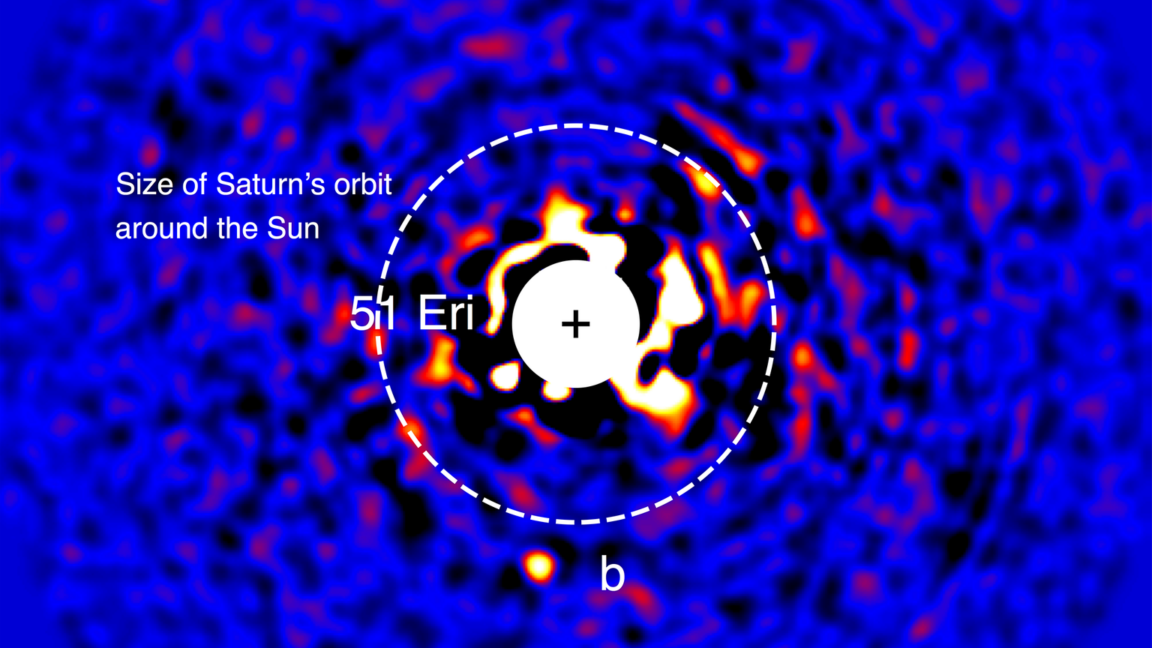
So a team of researchers has developed a process they’re calling FLIP (a non-acronym for Physics-based Learning for Imaging Planets) that uses a physical model of the hardware (in this case, the NIRCam on the James Webb Space Telescope) with 10 6 possible parameters, and then uses software to optimize all its parameters. The optimization starts with a simulated point spread function, then uses gradient descent to optimize its performance on data from an actual star.…