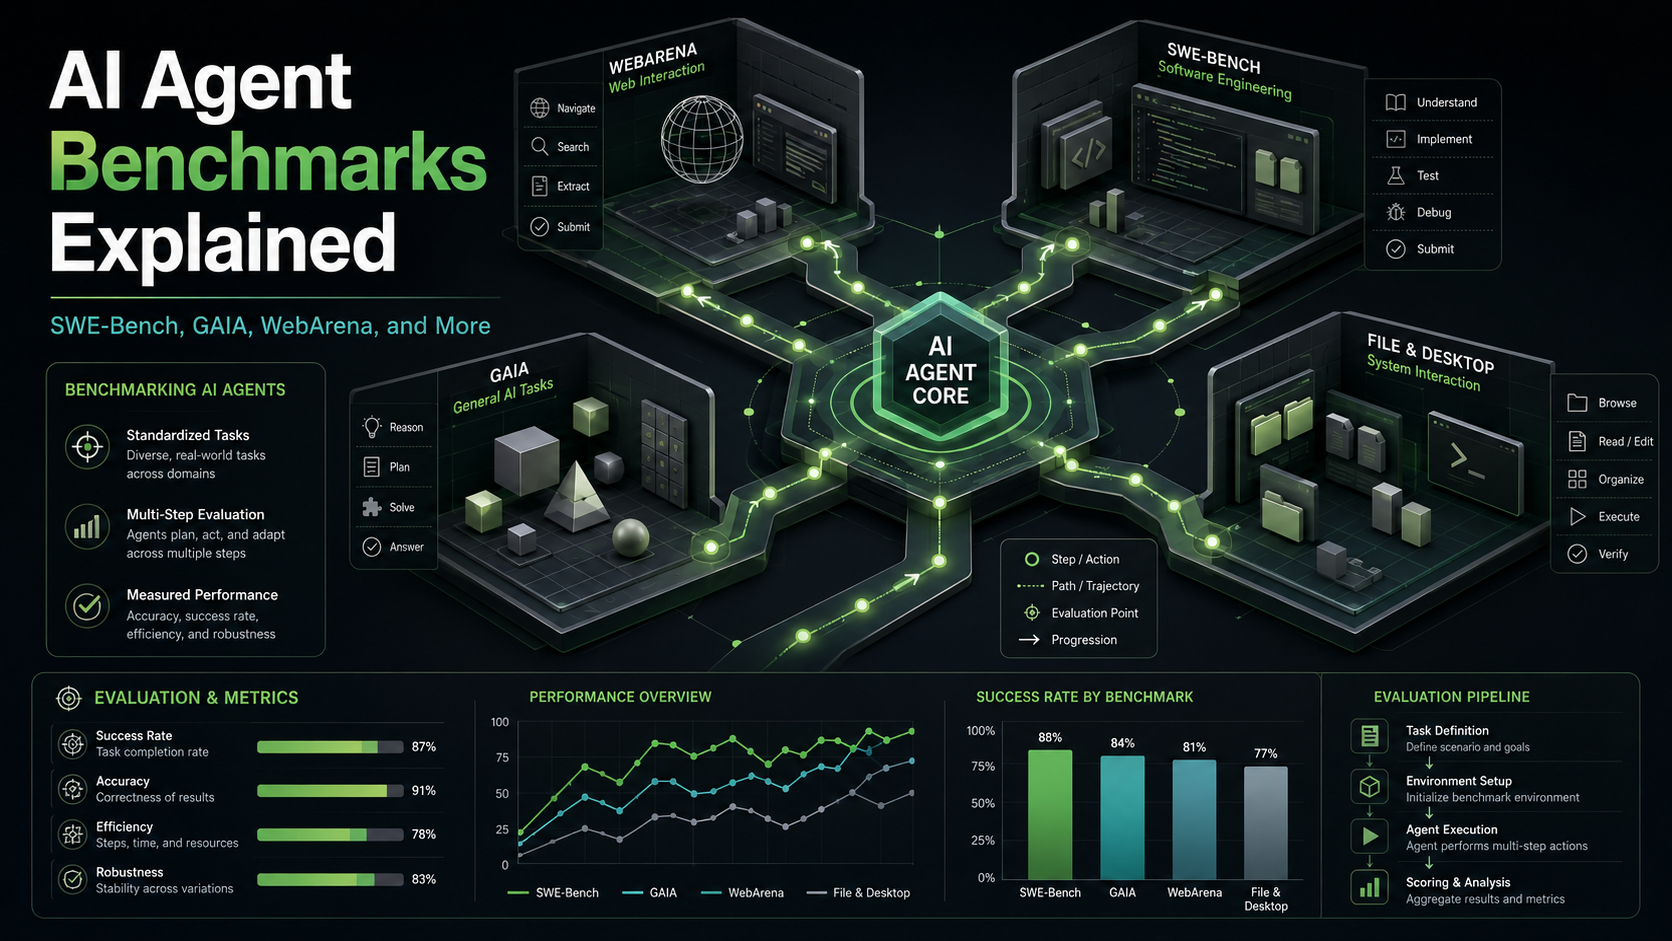
In this article, you will learn what the major AI agent benchmarks measure, how they differ from traditional model benchmarks, and how to use them as directional signals rather than performance guarantees.
Topics we will cover include:
How agent benchmarks like SWE-Bench, GAIA, WebArena, and OSWorld differ from one another and what each one actually tests.
What leaderboard scores consistently leave out, including cost, latency, safety, and error recovery.
How to combine public benchmarks with private evaluations to make more reliable decisions about agent deployment.
Introduction
Every AI provider claims their agent is state of the art. Leaderboards update weekly. Marketing pages glow with impressive percentages. But for anyone who has actually deployed an AI agent in production, one question matters more than any score: does it reliably do the job you hired it for?
This guide cuts through the leaderboard noise.…