Menu

#BenchMarkS

36 posts

Feed·
20 of 36 posts
0Read More

We need a new era of benchmarks

Reddit r/artificial·u/Prestigiouspite·2 days ago
#jhxqn2Ek
#benchmarks#tasks#need#kind#photo

Most of the benchmarks are in English. But a large portion of the world's population doesn't speak English (around 80 %). We can see from SWE Pro or the stagnation at DeepSWE that we're kind of measuring in a vacuum right now.…

15s
Why your local LLM feels dumber than it is
🖼️
508Read More

Why your local LLM feels dumber than it is

Hacker News·2 months ago
#WSJJzj1r
#forum#inference#benchmarks#gpu#quantization

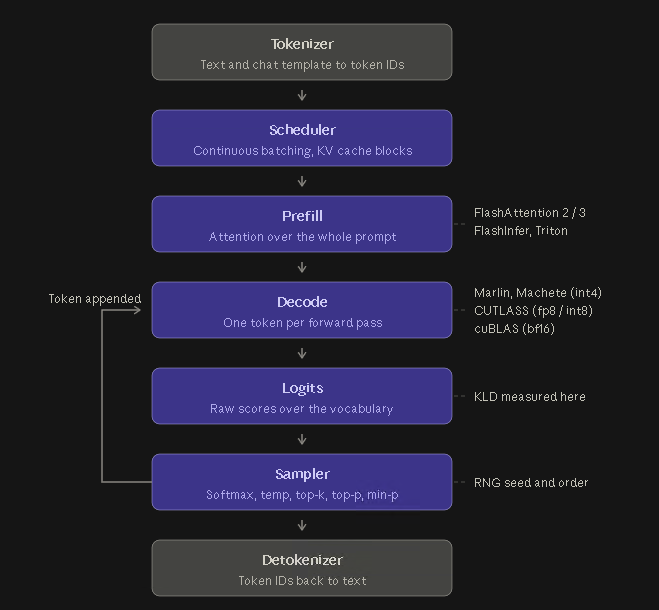
Quick Introduction We have all been on forums, chats, reddit, discord, youtube, or somewhere and heard “Oh! Model XYZ is AMAZEBALLZ!zomgwtfbbq” then downloaded it (or more likely, some quantized form of it) and said “eww… This sucks!” This post is going…

15s
Ox Alpha - API Pricing & Providers
📰
0Read More

Ox Alpha - API Pricing & Providers

Hacker News·2 months ago
#Rr1PcsqP

Ox Alpha is a reasoning model designed for coding, sustained agentic work, and production workloads. This model is free to use. 1,048,576 token context window, maximum output of 131,072 tokens.

15s
GPT-5.6 Sol - API Pricing & Benchmarks
📰
0Read More

GPT-5.6 Sol - API Pricing & Benchmarks

Hacker News·2 months ago
#uynMX7px

GPT-5.6 Sol is the flagship model in OpenAI's GPT-5.6 series. $2.50 per million input tokens, $15 per million output tokens. 1,050,000 token context window, maximum output of 128,000 tokens. Higher uptime with 3 providers.…

15s
164Read More

Agentic test processes, LLM benchmarks, and other notes on agentic coding from Galapagos Island

danluu.com·4 months ago
#tzlHUBvB
#testing#benchmarks#better#people#test

I've been using AI fairly heavily since last November and the whole thing is a funny experience. An agent will do something that, if a human did it, you'd immediately fire them.…

15s
Model Evaluation: Benchmarks, Human Evaluation, LLM-as-Judge, and A/B Testing in Production
🖼️
0Read More

Model Evaluation: Benchmarks, Human Evaluation, LLM-as-Judge, and A/B Testing in Production

DEV Community·丁久·6 months ago
#56BjaQm9
#ai#machinelearning#llm#software#model

Evaluate LLM models systematically using benchmarks, human evaluation, LLM-as-judge frameworks, and production A/B testing.

15s
Interfaze: A new model architecture built for high accuracy at scale
🖼️
0Read More

Interfaze: A new model architecture built for high accuracy at scale

Interfaze·Yoeven·6 months ago
#djHlBmCp
#x26#x3c#interfaze#benchmarks#model

A complete walkthrough of Interfaze: what it is, who we benchmark against (Gemini-3-Flash, Claude-Sonnet-4.6, GPT-5.4-Mini, Grok-4.3, plus task specialists like Reducto, SAM 3, Scribe v2), full results across 9 benchmarks, and code examples for OCR,…

15s