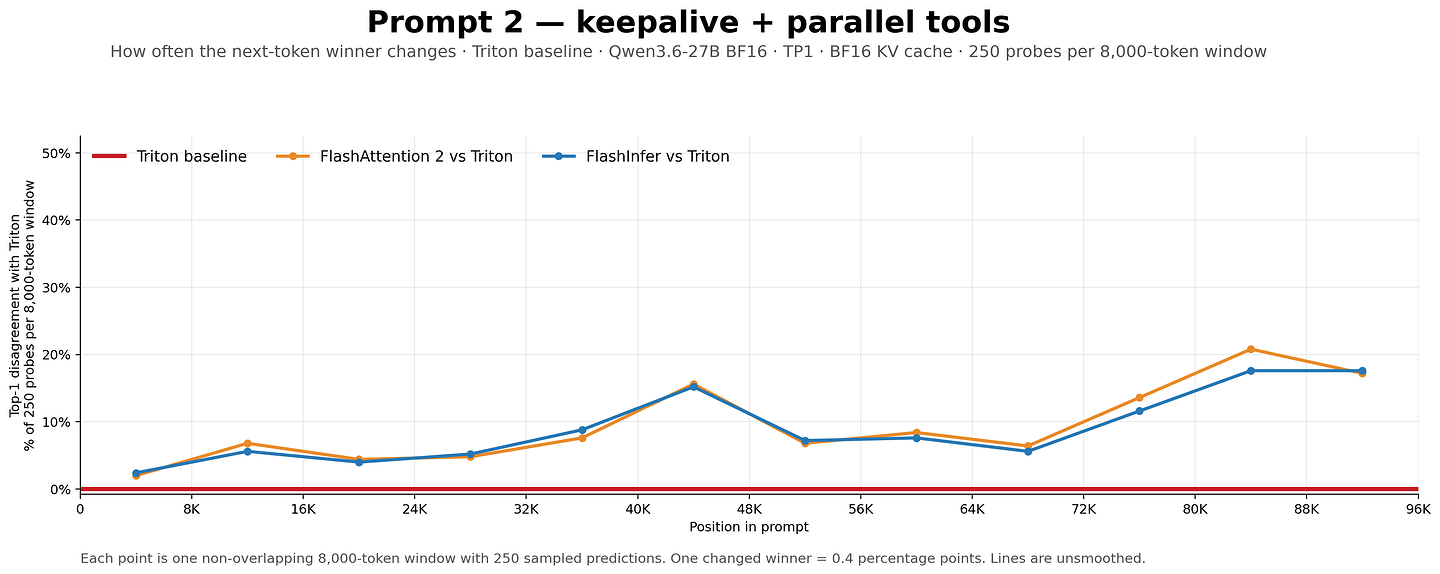
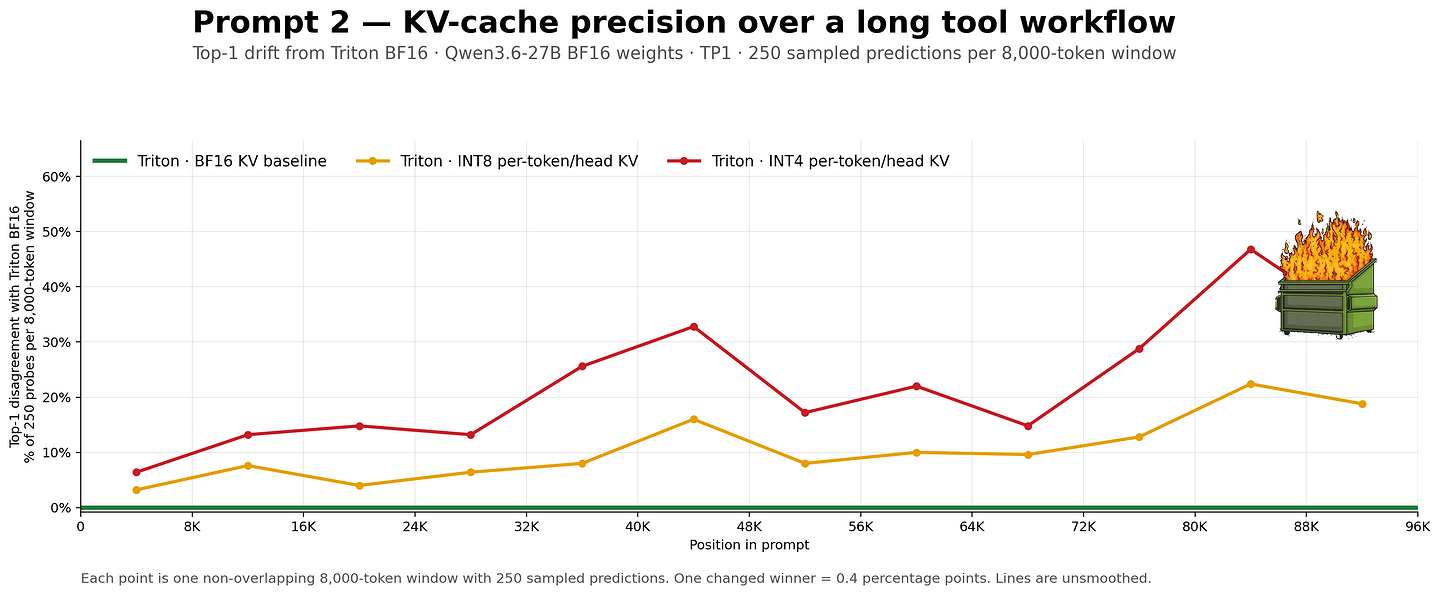
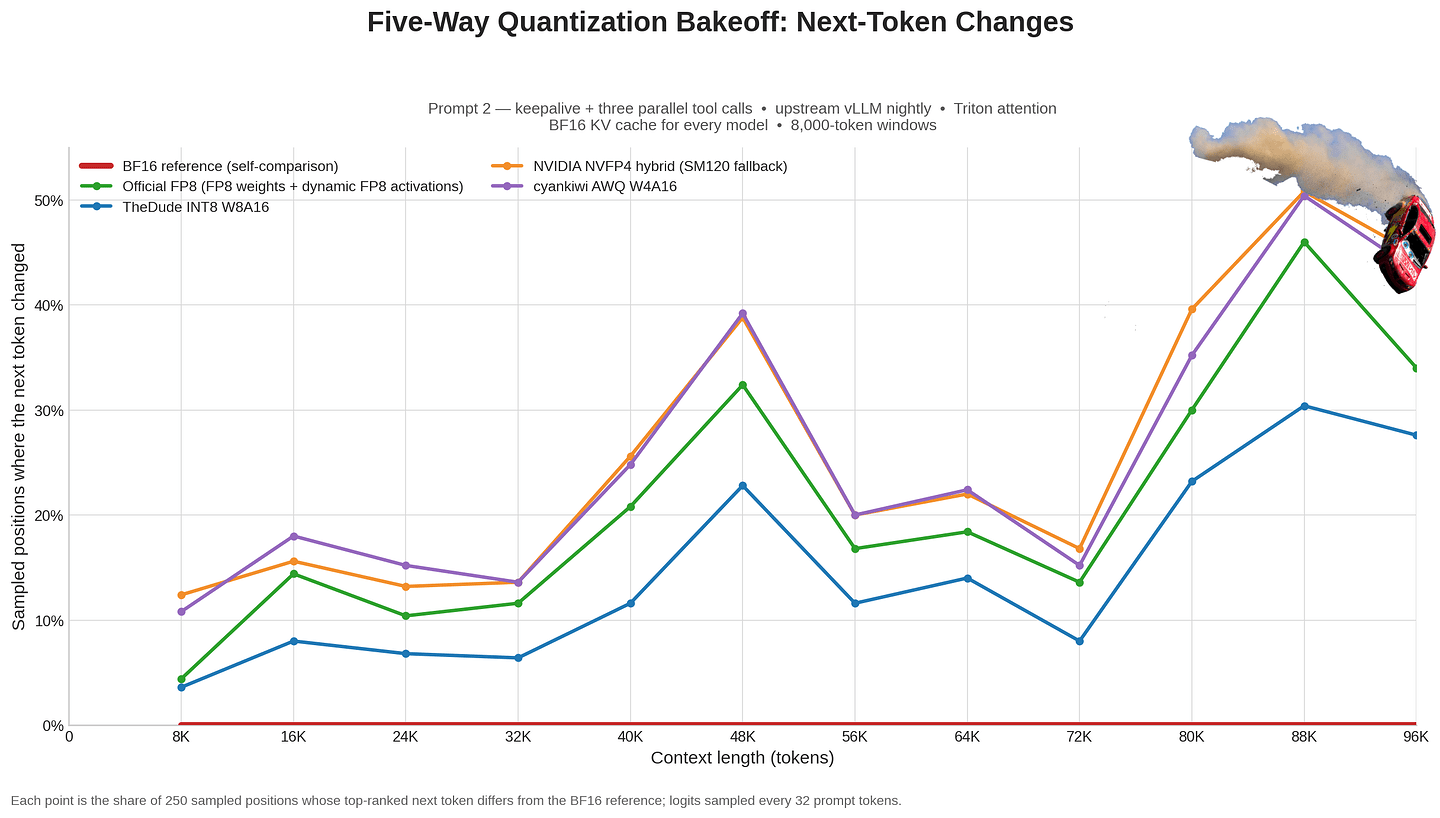
Quick Introduction We have all been on forums, chats, reddit, discord, youtube, or somewhere and heard “Oh! Model XYZ is AMAZEBALLZ!zomgwtfbbq” then downloaded it (or more likely, some quantized form of it) and said “eww… This sucks!” This post is going to be a rather technical series of experiments to demonstrate the impact of implementation-specific hazards with inference. I will be using the term “reference implementation” to describe the lab that published and offers first-party hosting of their models and posts original benchmark claims. Their hardware will be different than yours. Their software will be very different than yours. And the comparisons in this post are not going to be running some 2.58-bit-gguf-in-ollama with a couple test prompts. I am intentionally glossing over entire emerging fields of study, mountains of research papers and lit review to make this more approachable for you the reader.…