#Quantization
34 posts
Feed·
20 of 34 posts

📰
15s

📰
The AI Chip War: A Practical Guide to GPU Memory, LLM Inference and AI Infrastructure
15s

📰
Design Patterns for Private ML Inference in ZK Circuits
15s

📰
Image Quantization Explained: Uniform, Non-Uniform and Vector Quantization
15s

📰
Model Quantization for Local AI: A Practical Guide
15s

📰
Zero-Allocation INT8 Quantization & Fast Inference on Embedded MCUs
15s

🖼️
How to Optimize Transformer-Based Models for Low-Precision Training
15s

🖼️
Developing Nemotron 3.5 Lightning NVFP4 with QAD Using NVIDIA Model Optimizer
15s

🖼️
How to Size GPUs for AI Inference and TCO Without Overspending
15s
🖼️
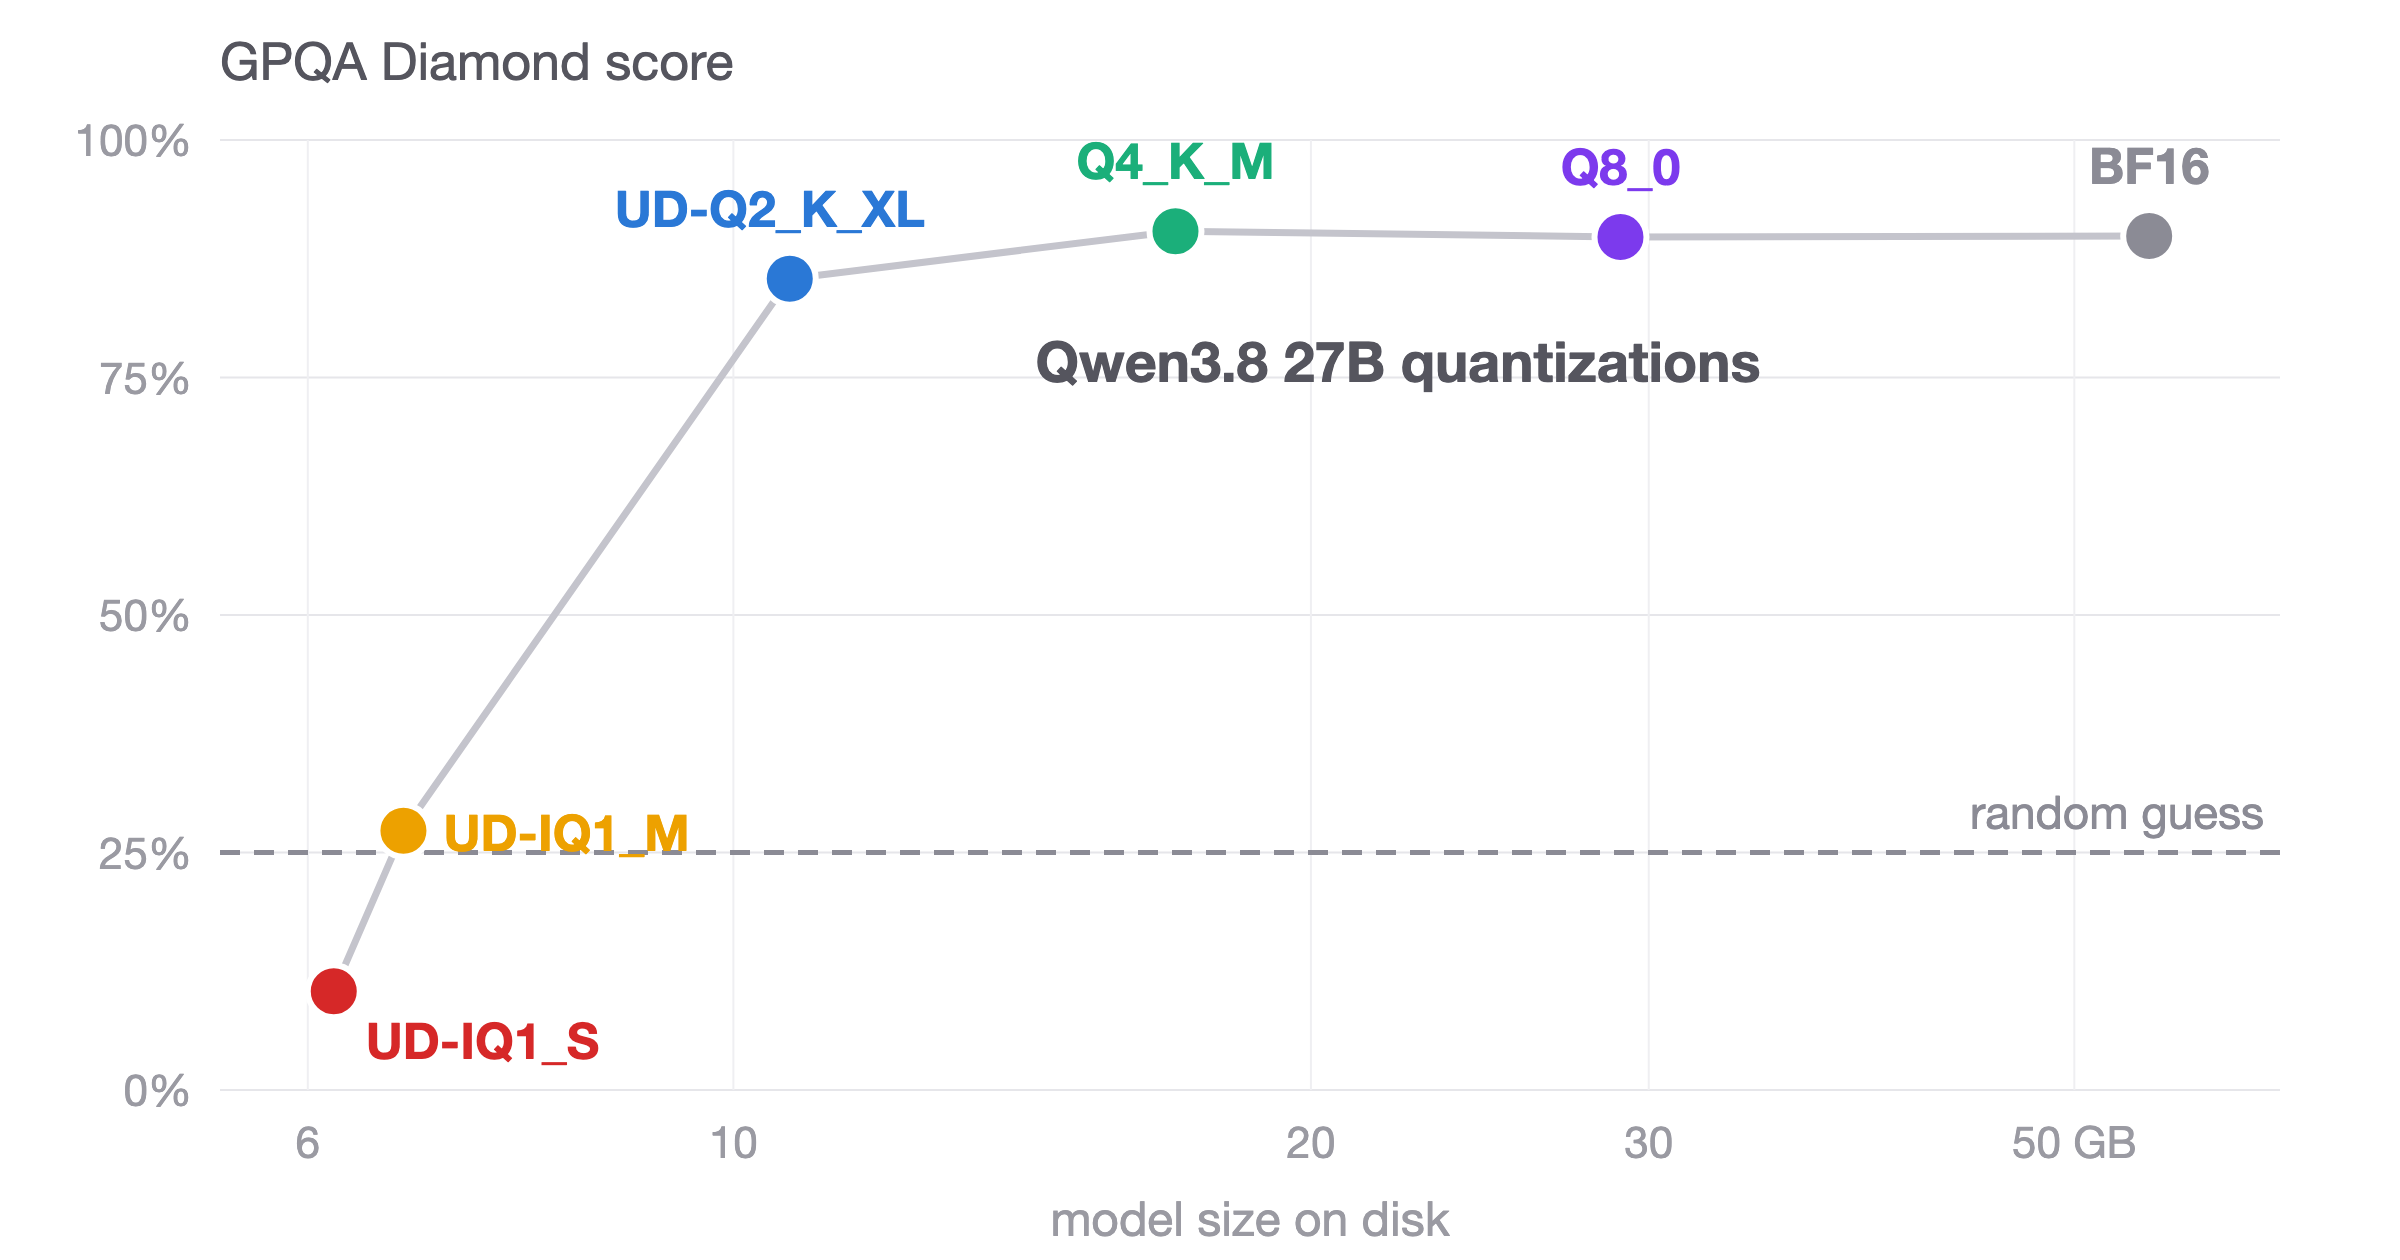
Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses
Hacker News·2 months ago
#hwNfzXDZ15s

🖼️
Why your local LLM feels dumber than it is
Hacker News·3 months ago
#WSJJzj1r15s

🖼️
🖼️
Qdrant TurboQuant Explained: Is TurboQuant the Silver Bullet? | Towards Data Science
15s

🖼️
The End of the Memory Tax: How Google’s TurboQuant is Rewriting the Rules of Local RAG Systems
15s

🖼️
GGUF Quantization Explained: Q4_K_M vs Q5_K_M vs Q8 — Which to Pick (2026)
15s

🖼️
Model Quantization: Making LLMs Smaller and Faster
15s

🖼️
When I started running models locally, I thought quantization meant squeezing more into RAM. Turns o
15s

🖼️

🖼️

🖼️