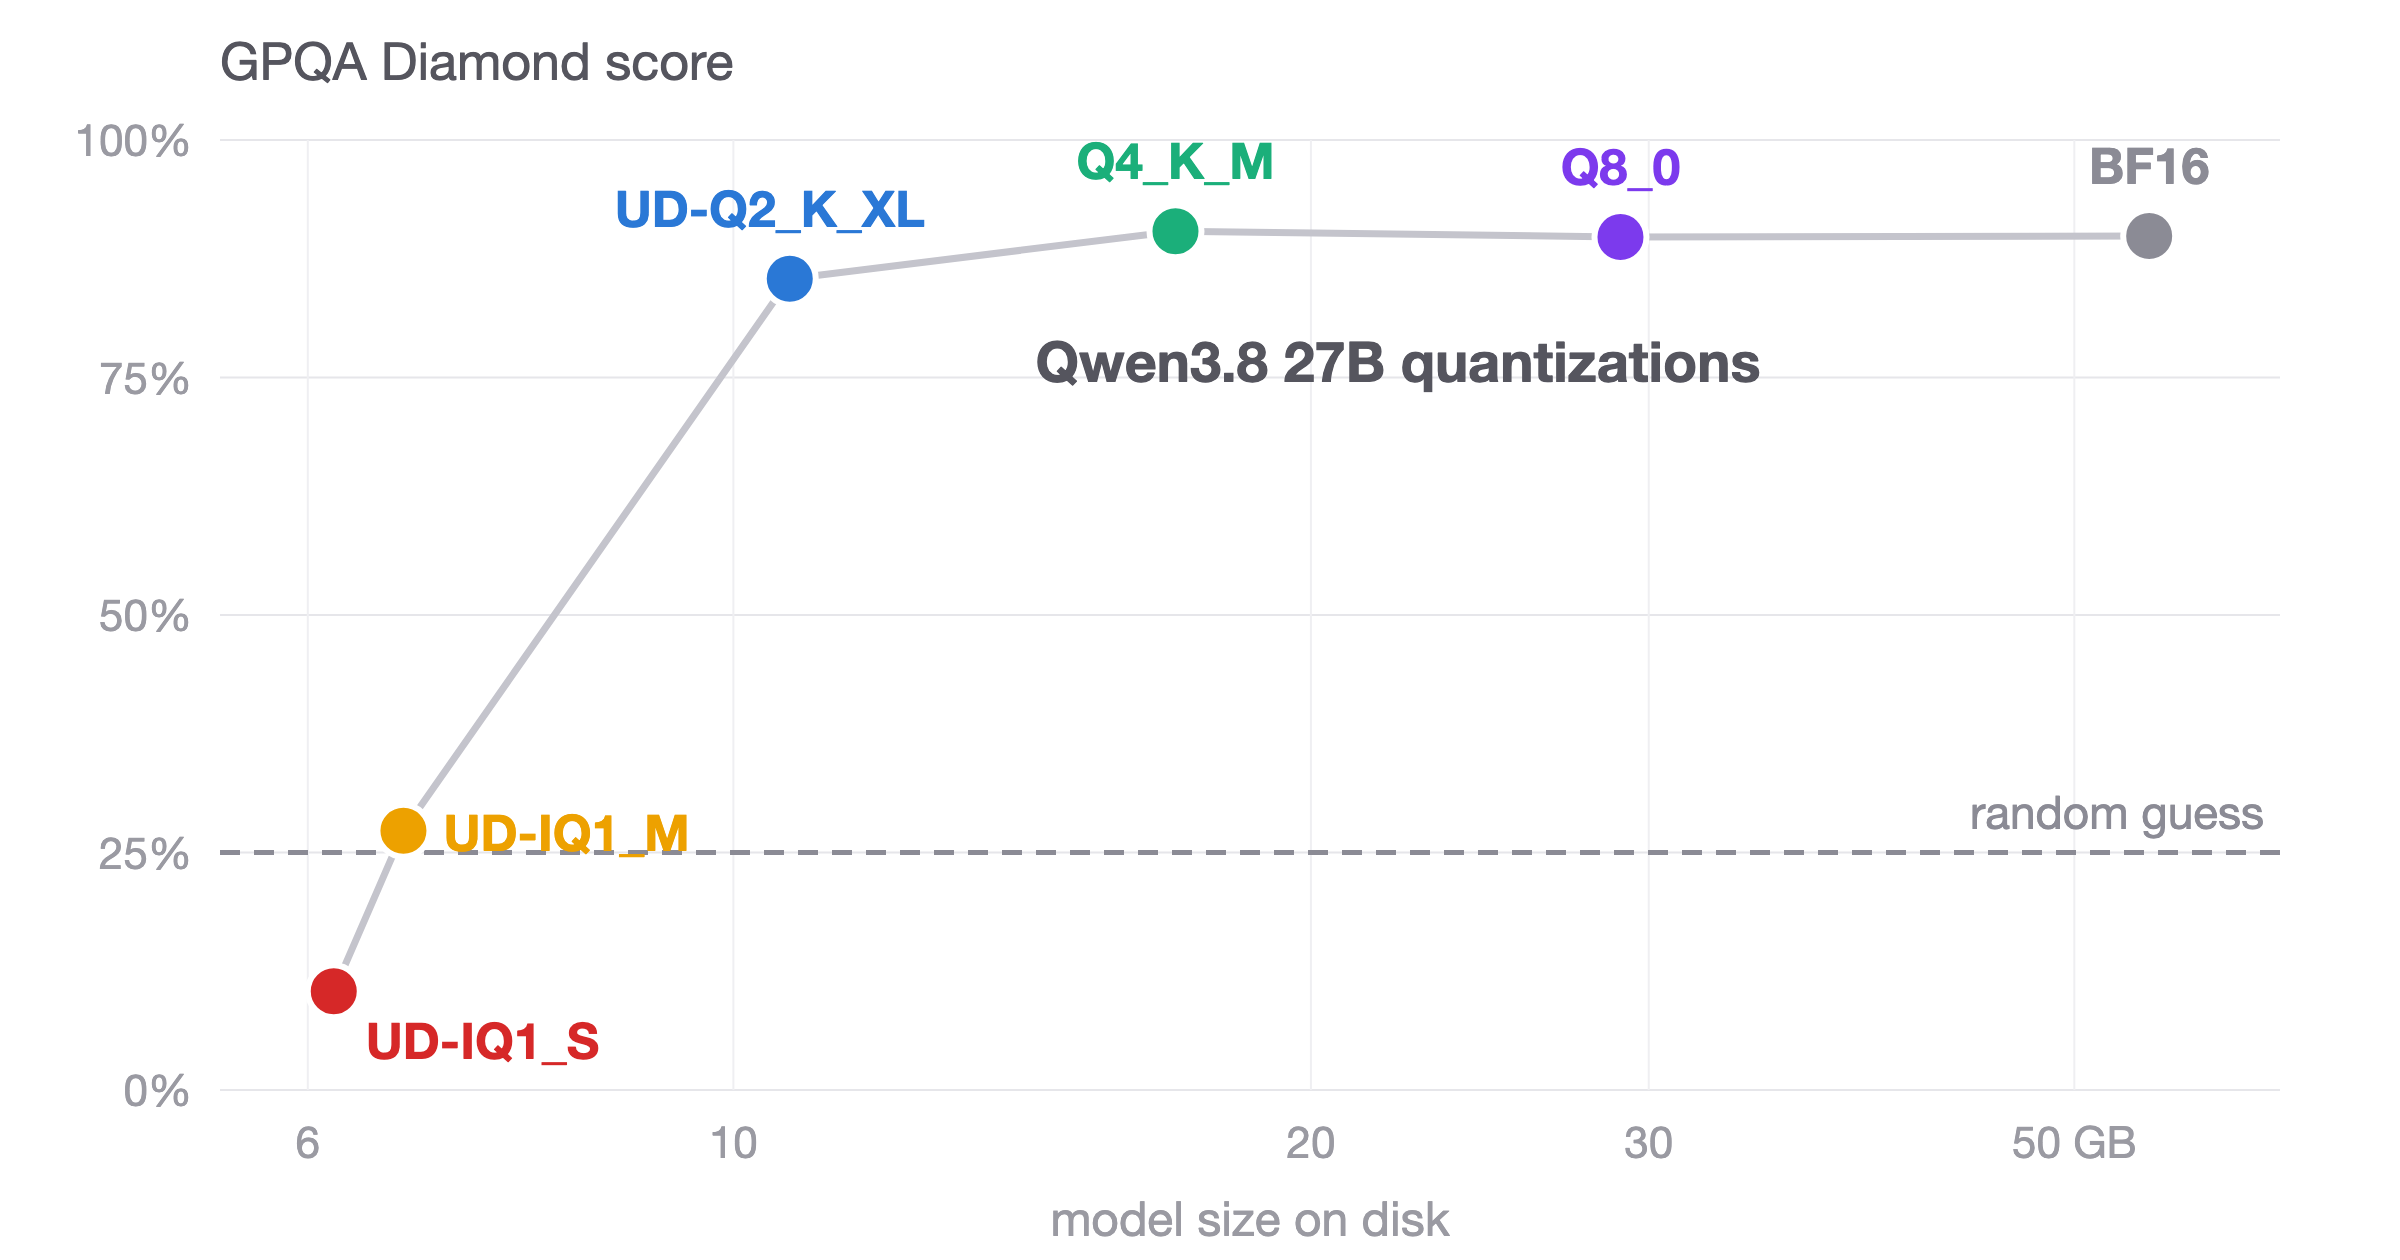
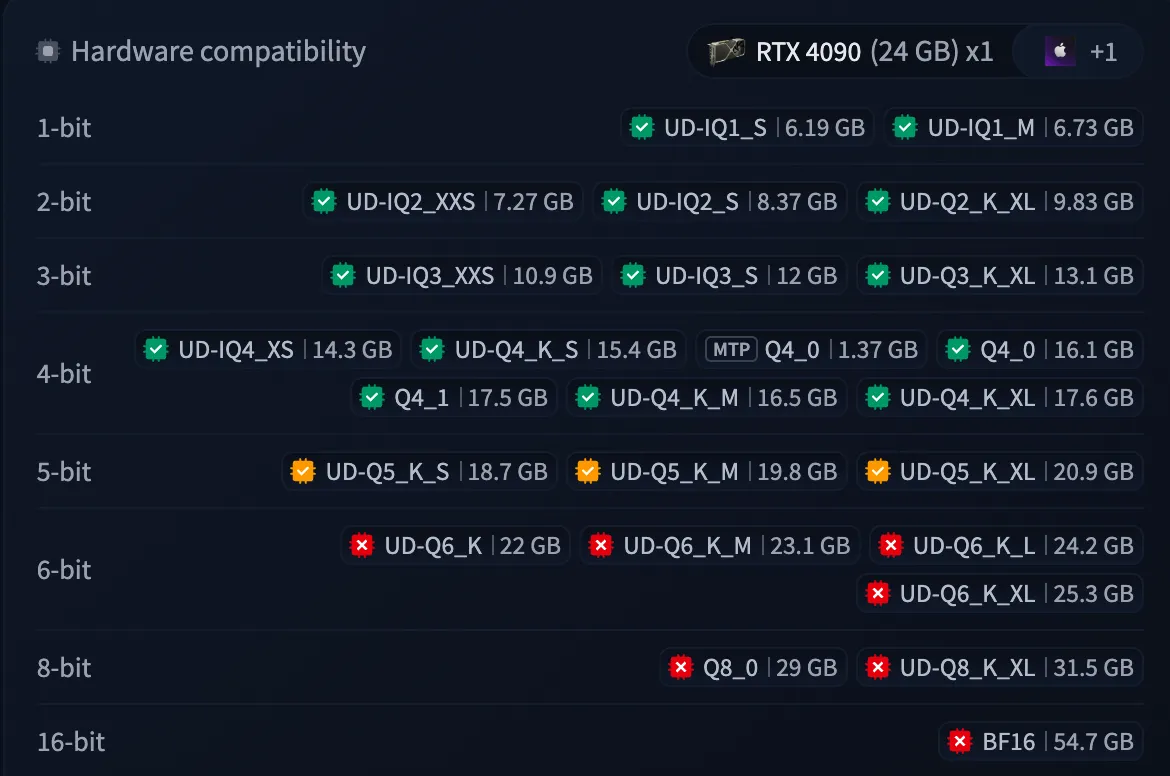
How much GPU RAM do you actually need to run Qwen3.8 27B without sacrificing quality? The full BF16 model weighs 55 GB, putting it beyond most consumer hardware. Yet the 17 GB Q4_K_M matches the full model on a popular agentic coding benchmark, Terminal-Bench 2.1. It fits on a 24 GB card such as RTX 4090, still leaving room for about 64k tokens of context. Compression eventually hits a cliff. At 1 bit, the model performs around random chance on GPQA Diamond, and longer reasoning makes it worse. Background Qwen3.8 27B GGUF quantizations available from Unsloth on Hugging Face . So much to choose from! I will check 8-bit Q8_0 (29 GB), 4-bit Q4_K_M (17 GB), 2-bit UD-Q2_K_XL (10.7 GB), and the smallest one possible, 1-bit UD-IQ1_S (6.2 GB). Previously, I investigated the Qwen3.6 27B model, which was good at generating SVG pelicans even at 12GB , and maintained most of its knowledge up to 16GB .…