Menu

#Quesma

3 posts

1 point
Feed·
3 of 3 posts
I burned all my tokens researching how to save tokens
🖼️
182Read More

I burned all my tokens researching how to save tokens

Hacker News·3 months ago
#g8eqdbi5
#quesma#research#claude#model#agents

How I burned a full Claude limit in 30 minutes and built my own deep research pipeline instead: 3 subscriptions, shared memory, a clear role for each model. You can build the same from what you already pay for.

15s
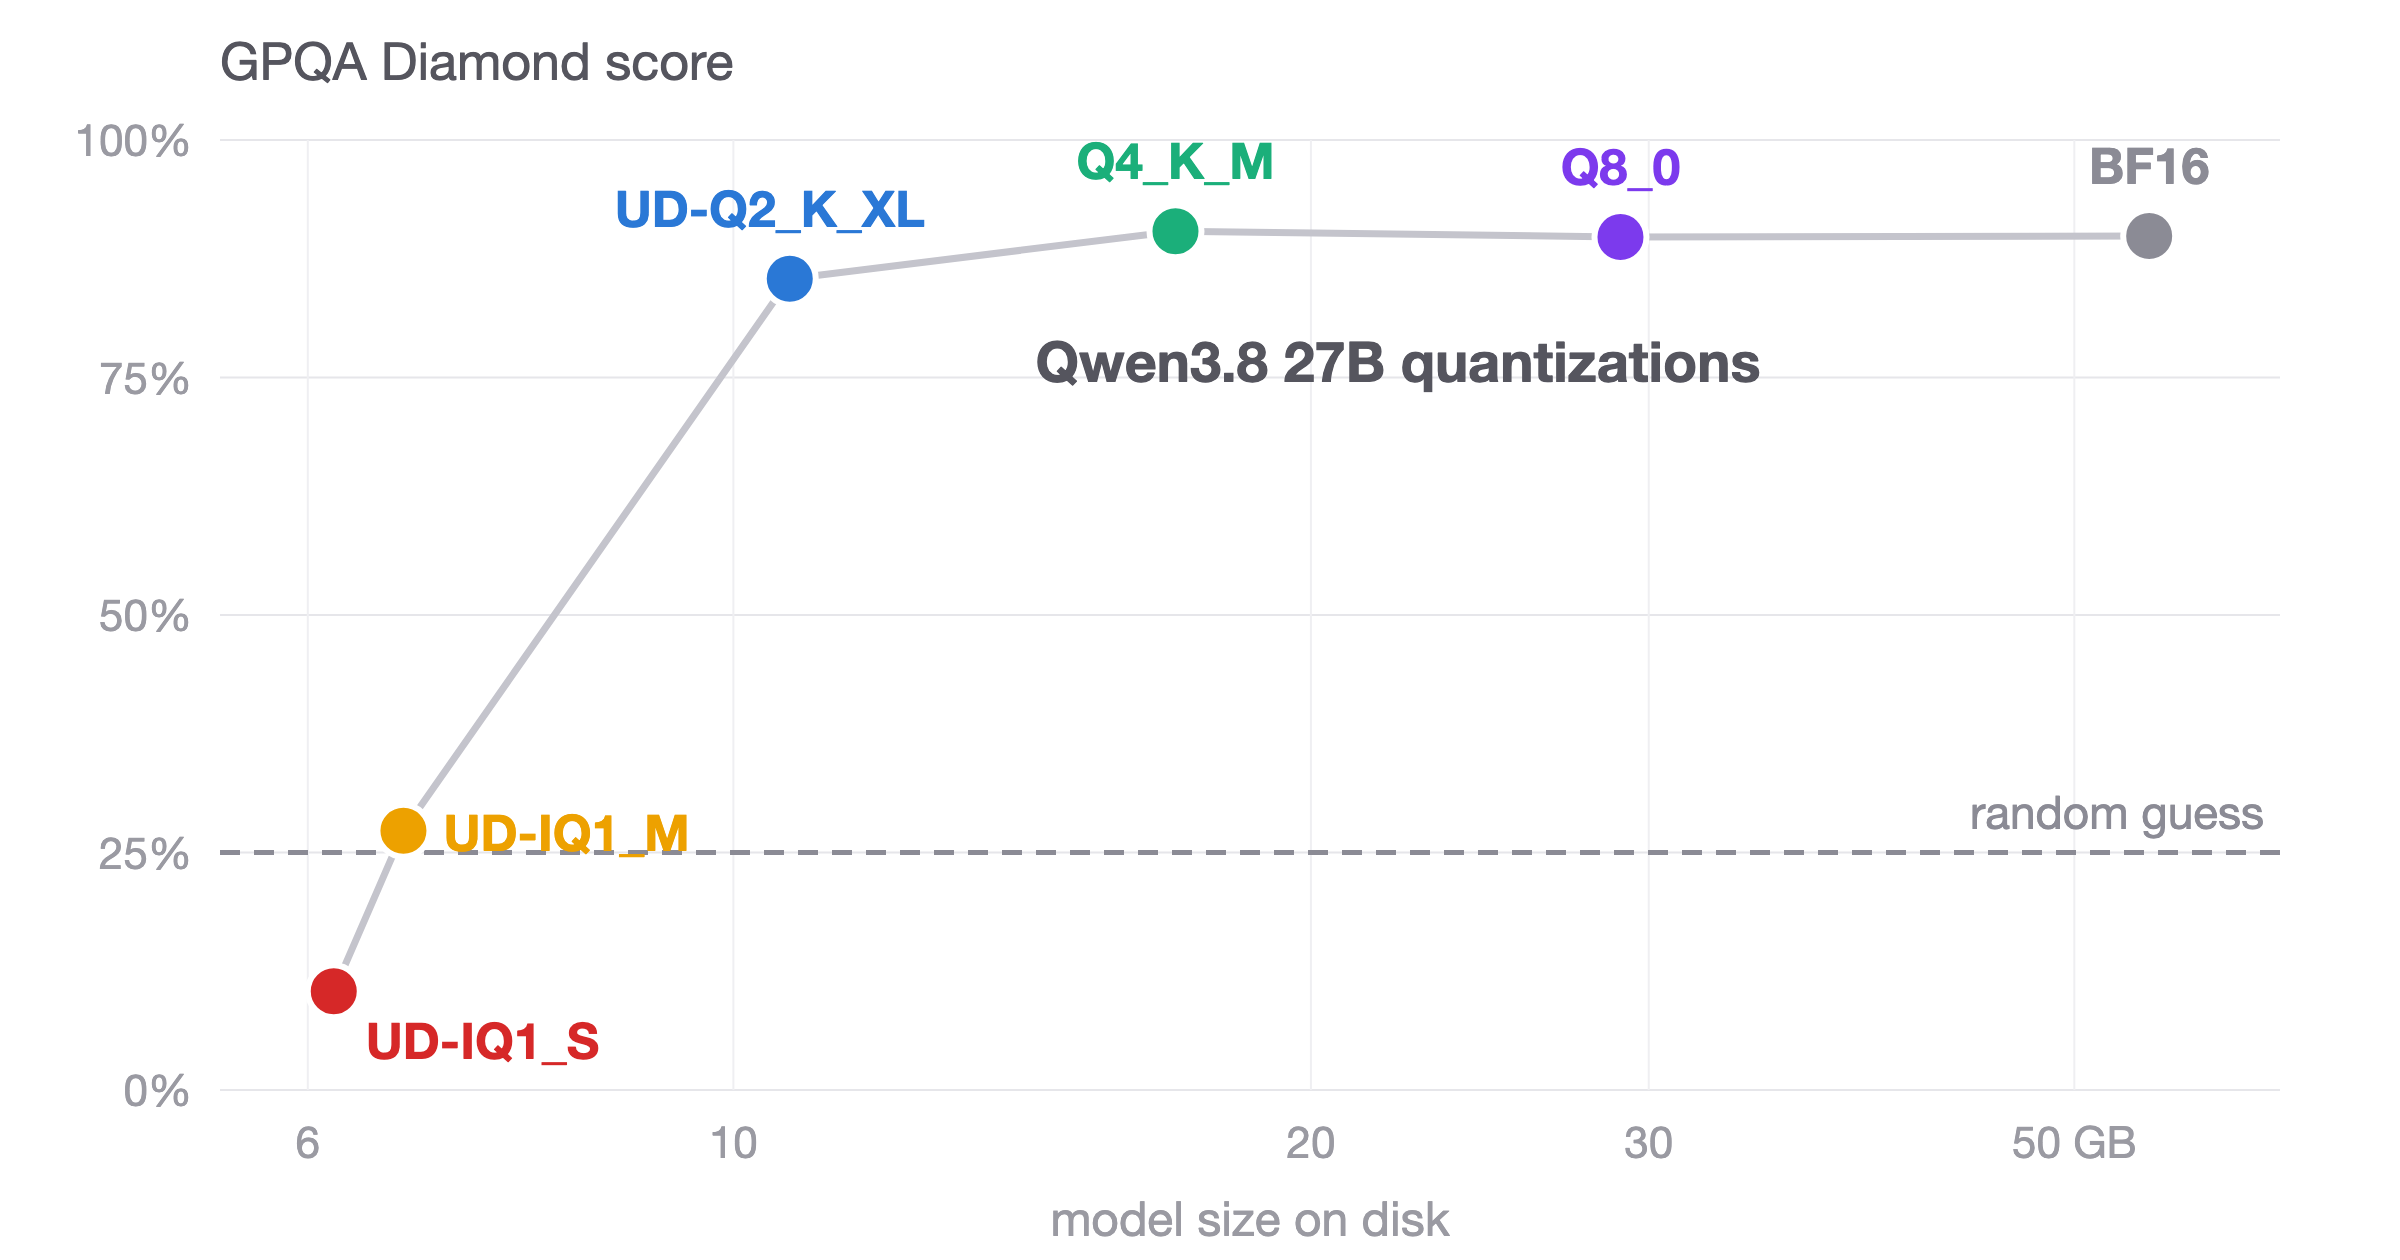
Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses
🖼️
0Read More

Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses

Hacker News·about 2 months ago
#hwNfzXDZ
#quesma#benchmarking#qwen#quantization#llm

I test Unsloth GGUFs of Qwen3.8 27B (Q4_K_M, UD-Q2_K_XL, UD-IQ1_S) with llama.cpp on GPQA Diamond, IFBench, Terminal-Bench 2.1. Q4_K_M matches BF16 abd fits an RTX 4090.
15s
Qwen 3.6 27B is the sweet spot for local development
🖼️
1188Read More

Qwen 3.6 27B is the sweet spot for local development

Hacker News·4 months ago
#dk5UeS09

Qwen 3.6 27B is finally a smart model we can use for coding on Macbook or Nvidia RTX - with llama.cpp and OpenCode.

15s