Menu

#Triton

12 posts

Feed·
10 of 12 posts
Simplifying Model Serving Across Multiple GPUs with NVIDIA TensorRT Multi-Device Integration in NVIDIA
🖼️
0Read More

Simplifying Model Serving Across Multiple GPUs with NVIDIA TensorRT Multi-Device Integration in NVIDIA

NVIDIA Technical Blog·Tanya Lenz·1 day ago
#DeJK7ImN
#developer#tensorrt#triton#device#multi

The compute and memory demands of generative AI increasingly exceed what a single GPU can provide. NVIDIA TensorRT multi-device inference is a new capability…

15s
Deploying an HSTU Generative Recommender with NVIDIA Dynamo-Triton
🖼️
0Read More

Deploying an HSTU Generative Recommender with NVIDIA Dynamo-Triton

NVIDIA Technical Blog·Tanya Lenz·1 day ago
#q2JYUUjR
#developer#model#hstu#triton#dynamo

Generative recommender (GR) systems are emerging as a powerful new approach for large-scale personalization. Instead of treating recommendation as a set of…

15s
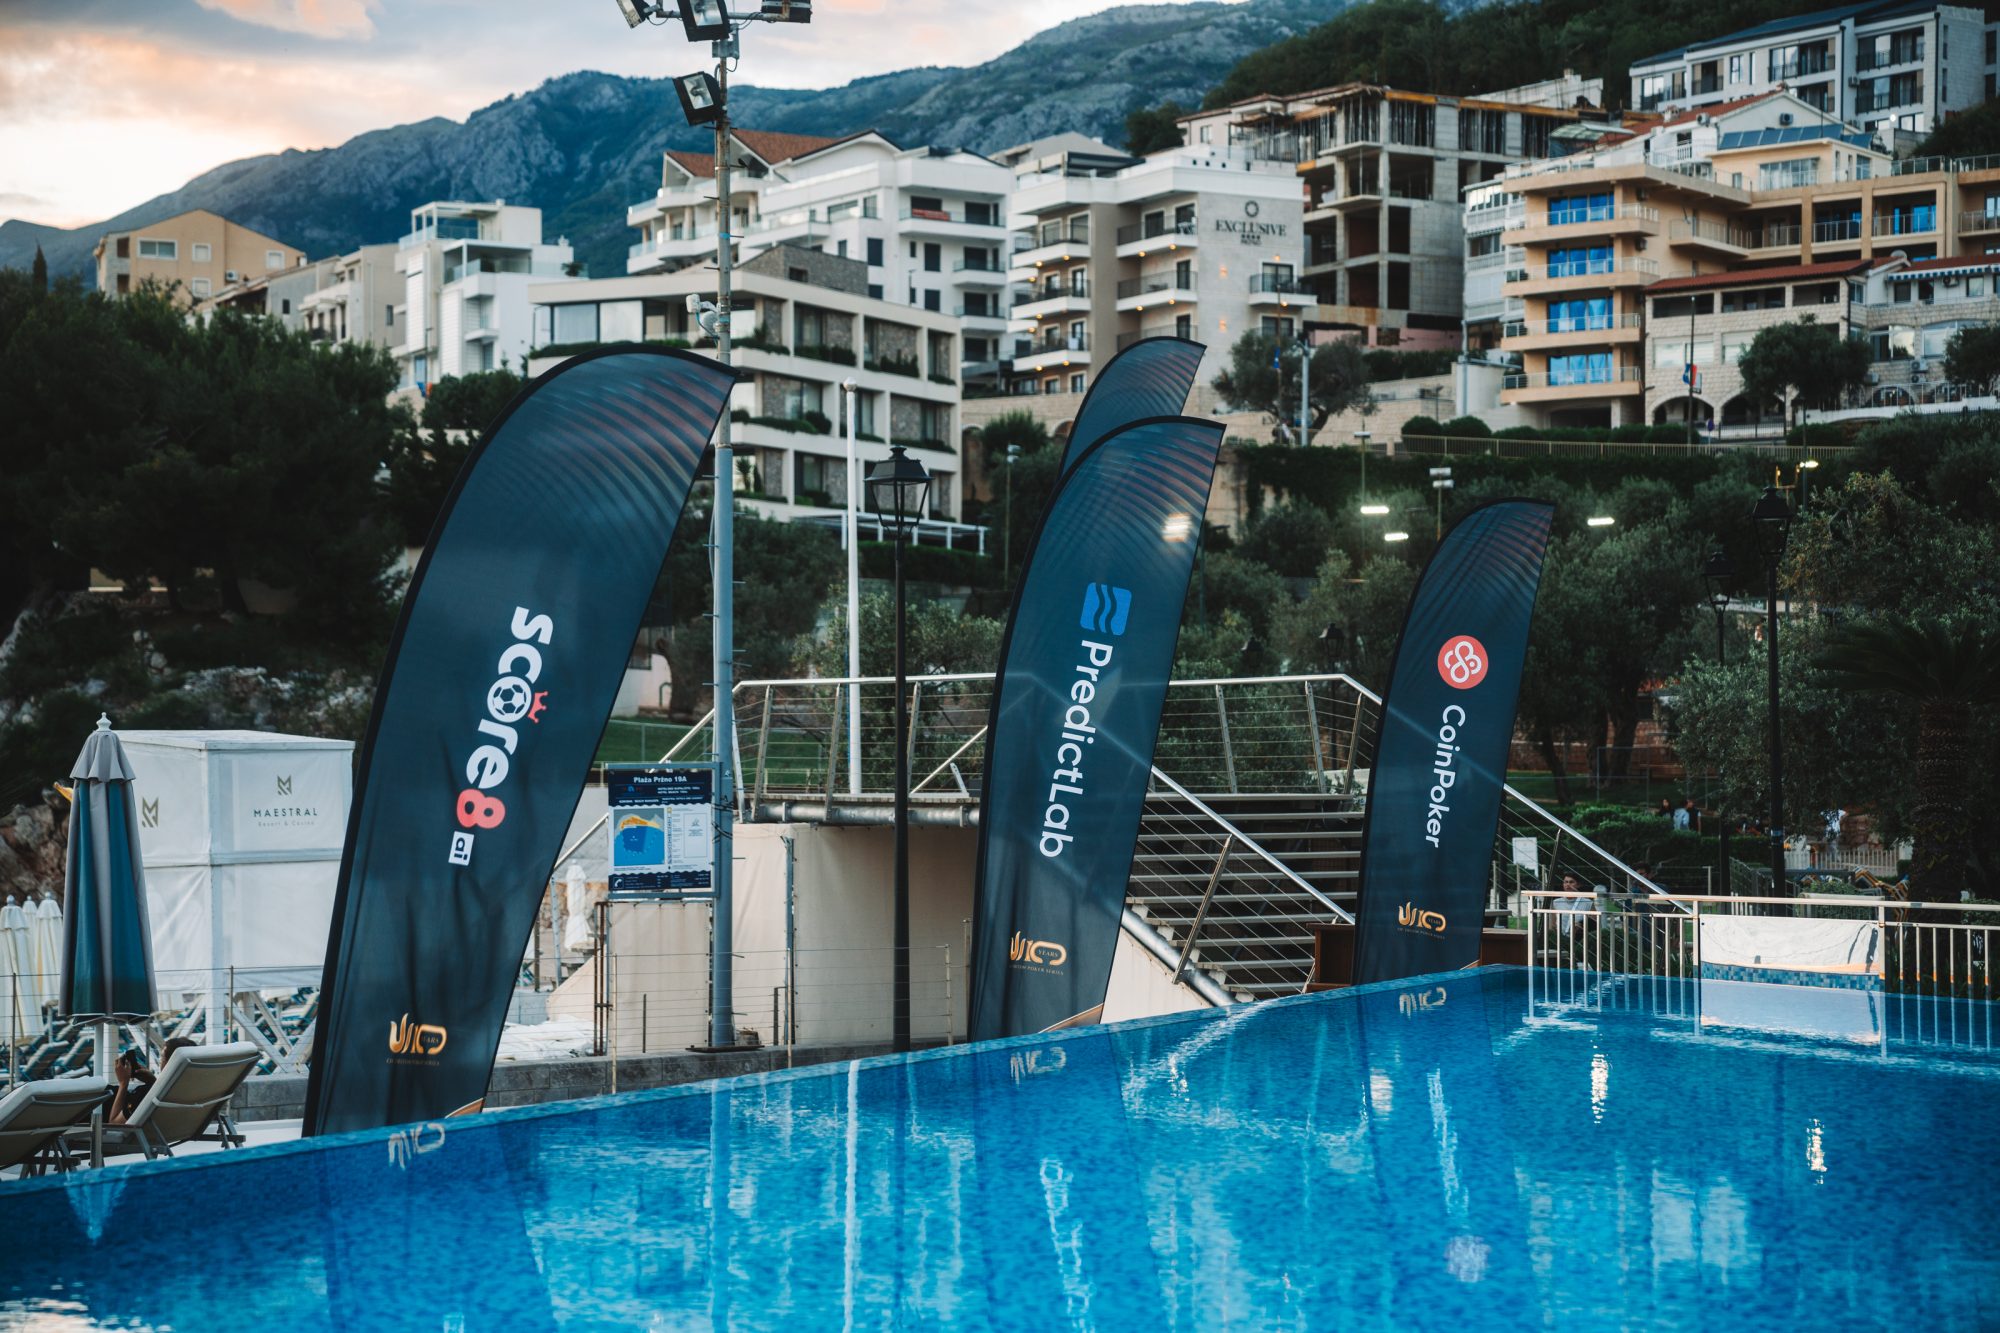
Tether Poker Room Seals Triton Partnership For Montenegro Stop, Announces 25,000 USDT Giveaway
🖼️
0Read More

Tether Poker Room Seals Triton Partnership For Montenegro Stop, Announces 25,000 USDT Giveaway

Online Casinos·jamesspillane·5 months ago
#UYA4EvVw
#valuewalk#event#poker#triton#coinpoker

Well-known Tether poker room, CoinPoker, is pushing deeper into elite poker territory through bold, strategic collaborations and sponsorship deals.

15s
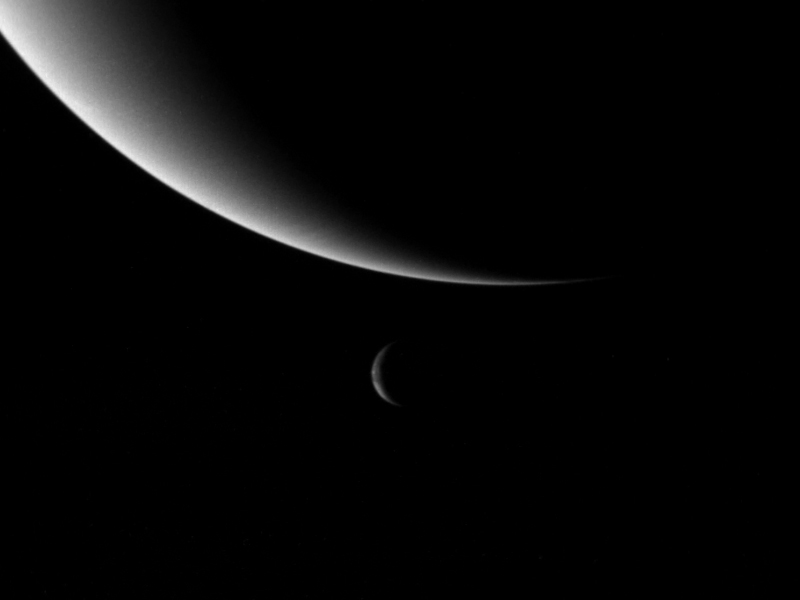
Starts With A Bang podcast #129 – Triton and the outer solar system
🎙️
0Read More

Starts With A Bang podcast #129 – Triton and the outer solar system

Big Think·Ethan Siegel·6 months ago
#KpMKf5YW
#post#page#colophon#solar#system

Triton is Neptune's largest moon today, but it was once the undisputed king of the Kuiper belt. Here's why the outer solar system matters.

15s
How to Deploy Llama 3.2 with Triton Inference Server on a $14/Month DigitalOcean GPU Droplet: Production-Grade Batching at 1/80th API Cost
🖼️
0Read More

How to Deploy Llama 3.2 with Triton Inference Server on a $14/Month DigitalOcean GPU Droplet: Production-Grade Batching at 1/80th API Cost

DEV Community·RamosAI·6 months ago
#s4ml6M7o
#deploy#programming#tutorial#ai#llama

From Dev.to - tutorial: How to Deploy Llama 3.2 with Triton Inference Server on a $14/Month DigitalOcean GPU Droplet: Production-Grade Batching at 1/80th API Cost

15s